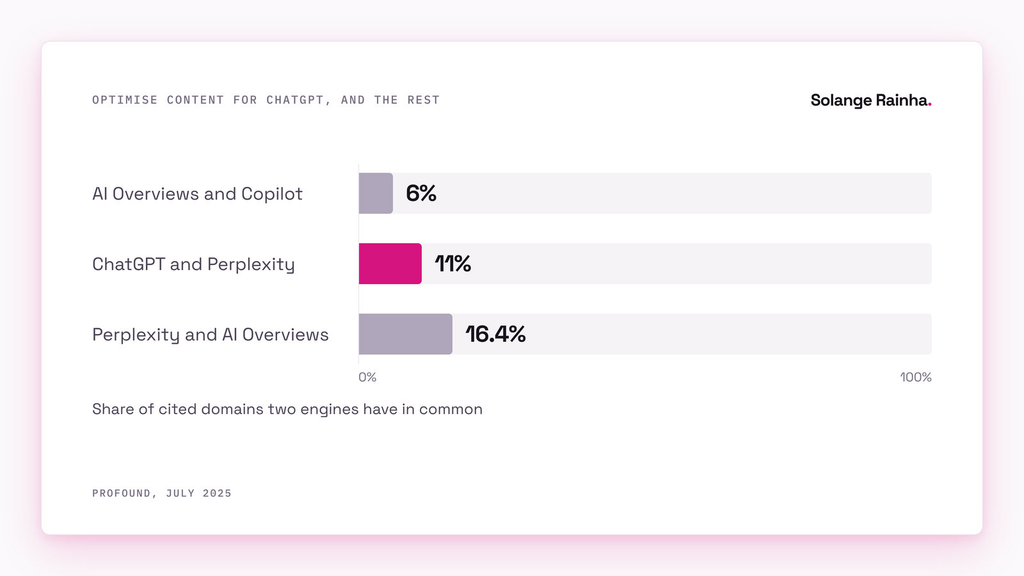
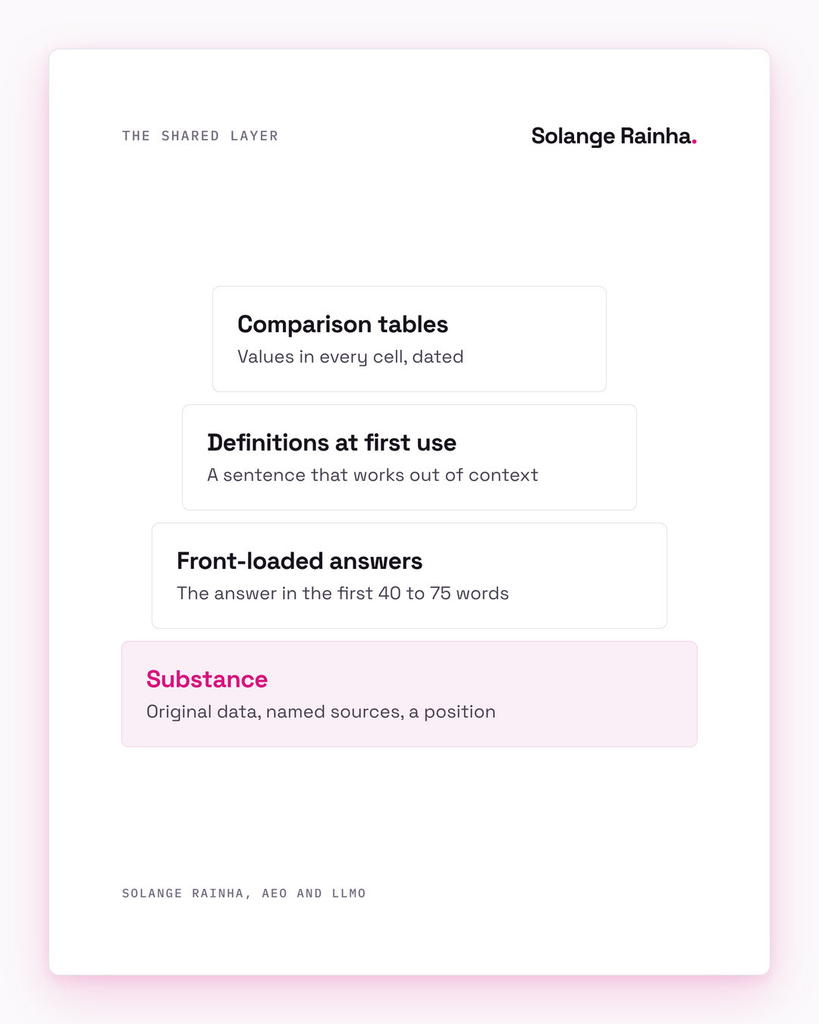
To optimise content for ChatGPT, Perplexity, Claude and Google AI Overviews, build one shared layer into every page and then pick a single platform-specific tactic based on where your buyers research. The engines retrieve differently, favour different sources and cite the same page at very different rates: only 11% of domains cited by ChatGPT and Perplexity overlap, so one “AI-optimised” template gets you cited by one engine and ignored by the others. The shared layer is substance first (original data, named sources, a position), then front-loaded answers, definitions at first use and comparison tables. Freshness helps on ChatGPT and Perplexity, and AI Overviews mostly reward what already ranks.
If you want to optimise content for ChatGPT, that’s a different job from optimising it for Perplexity, and both differ again from Claude and AI Overviews. Profound ran 100,000 prompts on both ChatGPT and Perplexity and found only 11% of the domains they cited appeared on both, with overlap between other pairs of engines ranging from 6% to 16.4%. Those figures kill the idea of generic AI optimisation, and what survives is a shared layer that works on every engine, plus one platform tactic chosen by where your buyers spend their research time.
The strategy behind it, meaning why substance comes before structure, sits in my AEO/LLMO content optimisation framework, and the general citability mechanics are in the tactical guide to AI-citable content. This piece is about what changes per platform.
How do ChatGPT, Perplexity, Claude and AI Overviews cite differently?
ChatGPT, Perplexity, Claude and AI Overviews retrieve in different ways, and that produces four different source preferences.
| Platform | How it retrieves | What it favours | What that means for a draft |
|---|---|---|---|
| ChatGPT | Searches the web for some prompts and answers others from training data. | Reference sources: Wikipedia is 47.9% of its ten most-cited sources, and it showed the strongest preference for fresh content in Ahrefs’ study. | Be the clear reference answer on the definitional parts, put credentials and named authority on the page, and keep it dated and current. |
| Perplexity | Live web search on almost every query, citing sources on 95% of queries in Passionfruit’s tracking. | Community sources, with Reddit at 46.7% of its ten most-cited sources, and recent material. | Freshness and dating count here, and your presence in communities does work your website can’t. |
| Claude | Searches less often: it cited sources on 64% of queries in Passionfruit’s tracking, the lowest of the four, but cited the most sources when it did. | In my experience, depth and clean structure. | Structure the depth instead of cutting it, since this is the engine most likely to pull several sources from a long, well-organised page. |
| Google AI Overviews | Google’s existing ranking infrastructure, with 54% of AI Overview citations matching pages in the organic results in BrightEdge’s data. | What already ranks, and the least interest in fresh content of any engine Ahrefs measured. | Your existing SEO work is the input; this is the least novel of the four. |
Two consequences worth sitting with:
- Freshness pays off on ChatGPT and Perplexity both. I originally wrote that it mostly worked on Perplexity and that ChatGPT weighted stability, but Ahrefs’ analysis of about 17 million cited URLs found ChatGPT’s citations averaged 458 days newer than organic results, the strongest freshness preference of any assistant, with Perplexity at 250 days newer and AI Overviews slightly older than organic. So a quarterly refresh with a visible update date is cheap, and it works on the two engines buyers use most.
- ChatGPT is the biggest traffic source by a distance. Conductor’s 2026 benchmarks, covering 13,770 domains, found AI referrals were just over 1% of web traffic and ChatGPT drove 87.4% of them. It’s also the engine that cites fewest sources per answer alongside Gemini, so being one of the few it does cite is where the traffic sits.

Which structural patterns get cited across all four?
The patterns that get cited across all four engines are definitions at first use, question headings with answers right under them, and comparison tables, and they go into every draft whether I’m trying to optimise content for ChatGPT, Perplexity or neither in particular.
- Explicit definitions at first use. Every key term defined in a sentence that survives being lifted out of the page entirely. If the definition only makes sense inside its paragraph, no engine is extracting it.
- Use question-format headings with self-contained answers: the H2 is the question a person asks, and the 40 to 75 words underneath answer it completely before any context arrives. Kevin Indig’s analysis of 1.2 million AI answers found 44.2% of ChatGPT’s citations came from the first 30% of a page, so burying the answer is expensive.
- A comparison structured as a table, meaning an actual comparison with values in the cells and never ticks, hands a model discrete facts with the relationships already resolved. It’s the pattern that pays off most consistently, and it’s why the comparison page is such an under-built asset.
Underneath all three sits the substance requirement. The Princeton GEO study (Aggarwal et al., KDD 2024, 10,000 queries) found the methods that lift visibility in AI answers are about substance: quotations from named sources added about 41% on its main measure, statistics about 31% and citing sources about 28%, while keyword stuffing fell below the unmodified page. Structure delivers the substance underneath it and can’t stand in for it, which is the argument in why the AEO playbook is usually run backwards.
What do the edits look like?
The edits are specific changes to sentences, and these are the three I make most.
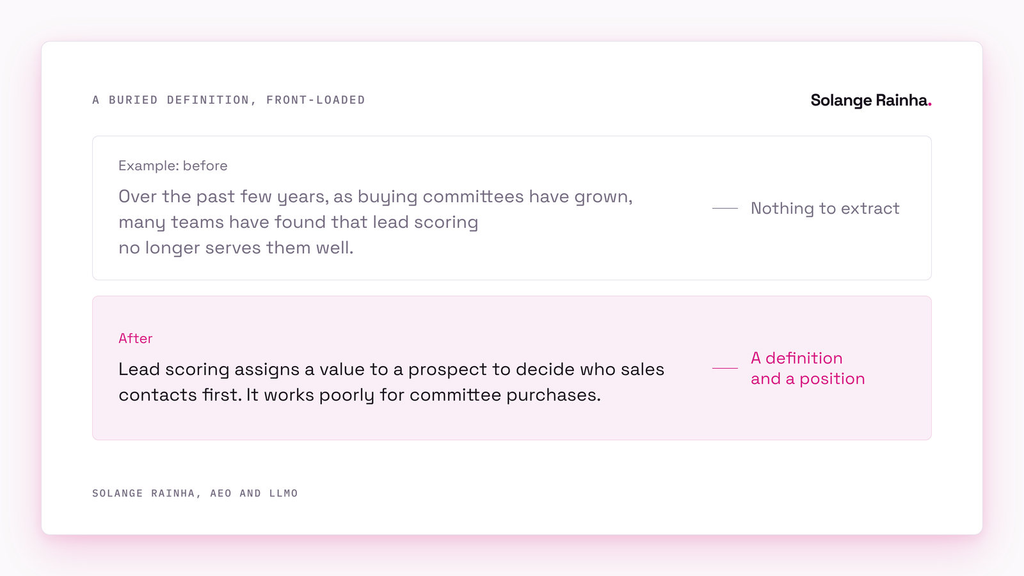
A buried definition, front-loaded
Before: “Over the past few years, as buying committees have grown and procurement has become more involved, many teams have found that the traditional approach to lead scoring no longer serves them well.”
After: “Lead scoring assigns a numerical value to a prospect based on their behaviour and profile, to decide who sales contacts first. It works poorly for committee purchases, and here’s why.”
The second version defines the term, states a position and survives extraction on its own, while the first says nothing a model could lift.
An unsourced claim, attributed
Before: “Most B2B content never gets used.”
After: “SiriusDecisions, now part of Forrester, has reported since 2013 that 60 to 70% of content produced by B2B marketing organisations goes unused.”
It’s the same claim, but one version is an assertion and the other is a citable fact with a named source and a date, which is one of the biggest lifts in the research. (The source is Forrester’s own write-up.)
Prose comparison, converted to a table
Any paragraph containing the word “whereas” plus two product names is a table that hasn’t been built yet. Pull the attributes out, make them rows, put a value in every cell for every option, and date the whole thing.
What should you prioritise when you can’t optimise for everything?
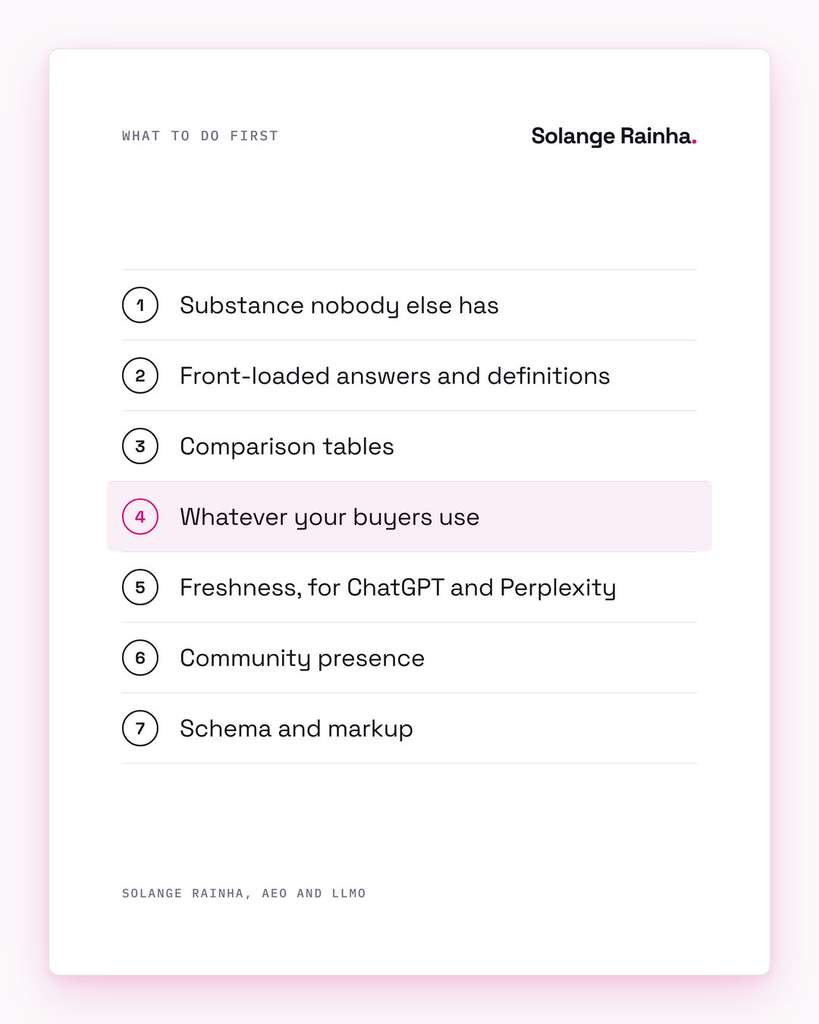
Prioritise in this order, which reflects payoff per hour and not the sequence most guides use. None of the platform tactics, including everything above about how to optimise content for ChatGPT specifically, does anything if you skip the first item.
- Substance that isn’t available elsewhere. Original data, a named source nobody else has quoted, a position somebody could disagree with. Every platform-specific tactic below is worthless applied to a page a model can reconstruct from ten others.
- Front-loaded answers and explicit definitions. Cheap, and they work on all four engines.
- Comparison tables where a comparison exists. The highest-return structural change, and it doubles as decision content.
- Whatever your buyers use. Check your own referral data, which I set up as described in tracking AI traffic in GA4, and ask in sales calls before assuming ChatGPT. A research-heavy B2B audience can skew toward Perplexity in ways a consumer audience doesn’t.
- Freshness and update dates. A quarterly refresh with a visible date, aimed at ChatGPT and Perplexity.
- Community presence. It happens off your website, which is why it gets skipped, and it’s the direct route into Perplexity’s preferred source pool.
- Schema and technical markup. It’s hygiene, and it goes last, because it’s the layer everybody does first and it explains the least.
The one I’d fight for hardest is number four, because optimising for a platform your buyers don’t use is a well-executed waste, and the way you find out is running a prompt inventory across engines and logging who gets cited. Include your documentation URLs when you do, because the page that gets cited is often product documentation instead of the blog.
What goes on the editorial checklist?
The editorial checklist is eleven checks I run on every draft before it publishes, and no item takes longer than a couple of minutes, whatever engine you’re aiming at.
- [ ] Does the page contain at least one claim, figure or named source a model can’t get from ten other pages?
- [ ] Is every key term defined at first use, in a sentence that works out of context?
- [ ] Do the first 40 to 75 words after the H1 answer the title question completely?
- [ ] Is every H2 a question somebody asks, phrased the way they’d ask it?
- [ ] Does each section stand alone if it’s the only part extracted?
- [ ] Is every external figure sitting immediately beside its source link?
- [ ] Is any comparison built as a table with values, never ticks?
- [ ] Is there an FAQ block of three or four self-contained pairs?
- [ ] Does the page carry a visible last-updated date, and is it true?
- [ ] Is every claim traced to documentation, data or a named stakeholder in the source log?
- [ ] Do related pages link to each other instead of repeating each other?
The last two carry more weight than the formatting items above them: one fabricated statistic costs the authority signal on the whole page once models cross-reference claims across sources, and a cross-linked set of pages reads as depth in a way that fifteen orphaned posts never will.
Where does this advice run out?
Most of the figures in this piece come from companies that sell AI visibility tooling or services, and each measures citations its own way: Profound, Passionfruit, Ahrefs, Conductor and BrightEdge all sell into this market.
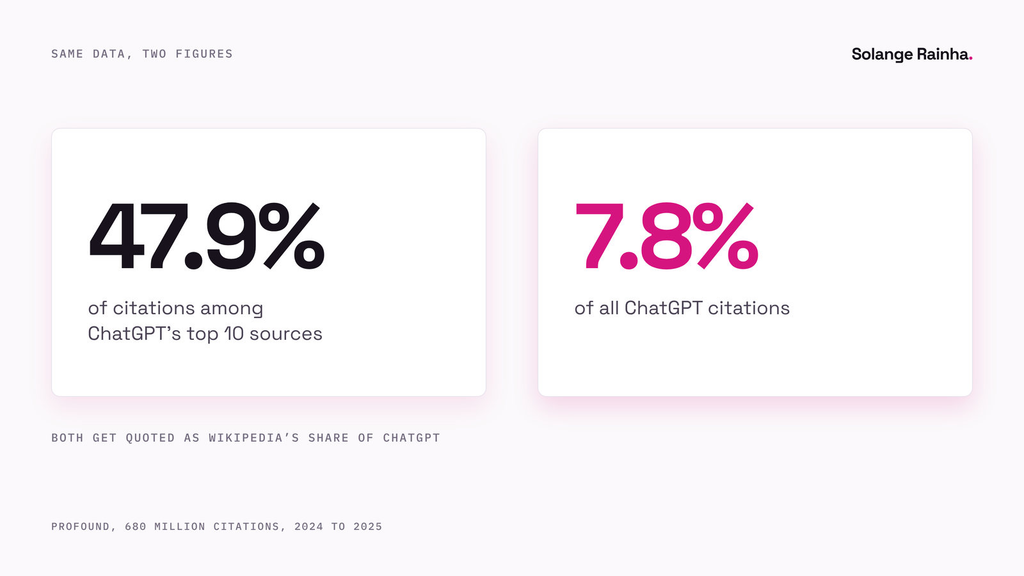
The figures also get quoted carelessly: Profound’s own data puts Wikipedia at 47.9% of ChatGPT’s ten most-cited sources and at 7.8% of all its citations, and both figures circulate as “Wikipedia’s share of ChatGPT”, which is how you end up with figures that look contradictory and are measuring different denominators. The 11% overlap figure comes from a large sample with its method described, and every dataset I’ve seen shows wide gaps between engines, so I’d stand behind those, though not the precise source-share percentages.
The Princeton figures are from 2024, and the engines have changed since, but what’s held up across everything I’ve applied this to is the ordering: substance, then structure, then measurement. The platform-specific tactics sit on top of that and they’ll date faster than the rest of this page, which is also why llms.txt is worth less than the discourse suggests and why the investment call between SEO, AEO and LLMO is a sequencing decision more than a technology bet.
Frequently asked questions
You can optimise content for ChatGPT and Perplexity at the same time for the shared layer: front-loaded answers, explicit definitions, question-format headings, comparison tables and attributed data. Both engines also favour fresh content, so a visible, substantive update helps on each. Beyond that they pull apart, since Perplexity leans on community sources like Reddit while ChatGPT leans on reference sources like Wikipedia, and only around 11% of the domains they cite overlap. Build the shared layer into every piece, then pick one platform tactic based on where your buyers research.
Google AI Overviews need less separate work than the other engines, since they run on Google’s existing ranking infrastructure and 54% of their citations match pages in the organic results, according to BrightEdge. They also showed no preference for fresher content in Ahrefs’ study, so ranking is the input. The extractability work (self-contained sections, definitions, direct answers in the opening) is what turns a ranking page into a cited one, and existing SEO investment covers most of the rest.
The most important AI platform depends on your audience, and checking beats assuming. ChatGPT carries the overwhelming majority of AI referral traffic, at 87.4% in Conductor’s 2026 benchmarks, while citing fewer sources per answer than Claude or Perplexity, so it’s the biggest channel and one of the hardest to get into. Perplexity cites sources on almost every query and leans on communities, which suits research-heavy buyers. Run your own prompt set across the engines and read your referral data before committing effort.
AI-optimised content should be updated quarterly, with a visible and accurate update date, because ChatGPT and Perplexity both cite content that’s newer on average than Google’s organic results, with ChatGPT showing the strongest preference in Ahrefs’ analysis of about 17 million citations. The update has to be substantive, meaning new data, corrected claims or a revised position, because changing a date on unchanged content costs credibility when a model cross-references the page against other sources.