A B2B comparison page names the trade-offs between options, including the ones where you lose, and it’s the asset most B2B SaaS teams still refuse to build. Refusing doesn’t take the comparison out of the buyer’s process, it just hands the job to review aggregators, which now sit among the most cited sources in AI answers about software, with no stake in which buyer you’re good for. Build three different pages (buy versus build, alternatives, and segment fit), put the comparison in a table with values for every option, source and date every competitor claim, and concede where the other option wins, because that concession is what makes the rest of the page believable.
Most B2B content explains: it defines the category, walks through how the technology works, lists benefits, and then stops exactly where the buyer’s question starts. Given my situation, which of these should I pick, and what do I give up by picking it? That question is what a B2B comparison page exists to answer, and a model assembling a shortlist can’t extract an answer from a page that never attempts one, so it takes the trade-offs from wherever they’re published.
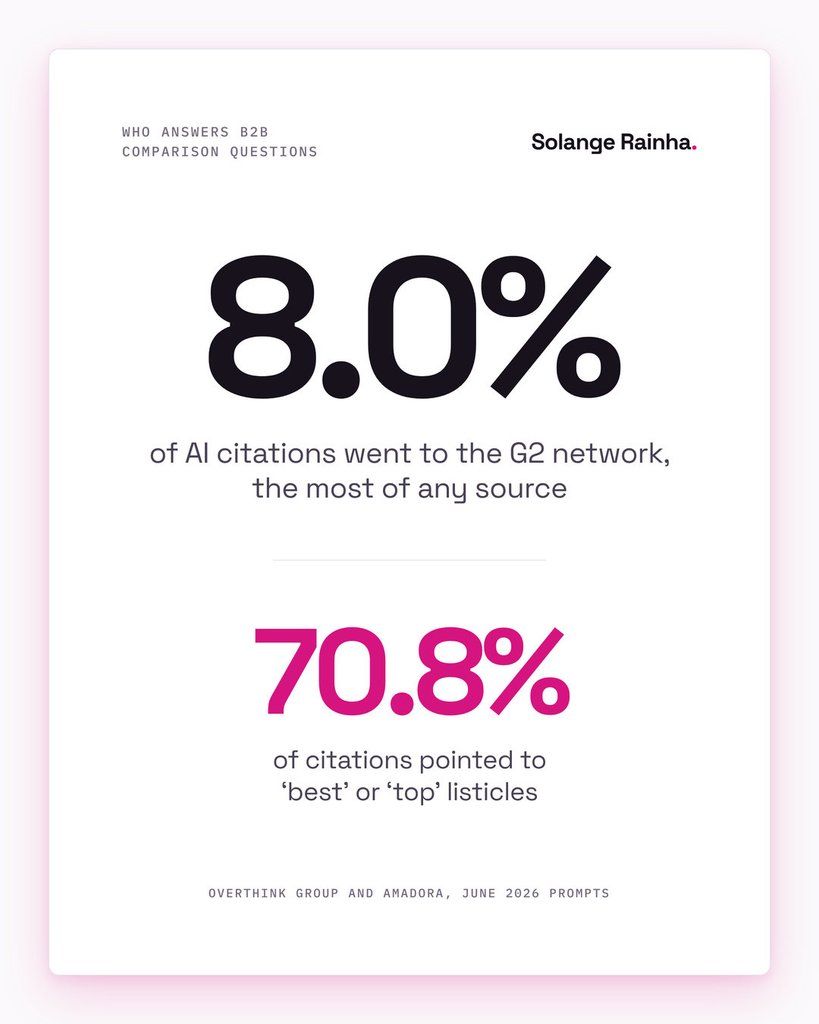
Somebody else is doing well out of that. Overthink Group and Amadora ran about 1,260 B2B software prompts across ChatGPT, Gemini, Perplexity and Google AI Overviews in June 2026 and found the G2 network accounted for 8.0% of all citations, with G2.com the single most-cited domain, and 70.8% of citations pointing to “best” or “top” listicles. G2’s own figure for its influence on software queries across ChatGPT, Perplexity and Google AI Mode is 22.4%. Review aggregators run a business model that depends on ranking you, with no obligation to get your positioning right.
My position is that if somebody’s going to summarise your category anyway, it may as well happen somewhere you control the accuracy, which means writing the B2B comparison page you’ve been avoiding.
Why does decision content outperform explanation content in AI retrieval?
Decision content gets retrieved because a model answering an evaluative question needs evaluative material, and that’s much rarer than explanation. There are ten thousand near-identical pages answering “what is conjoint analysis”, and no model needs yours to write one more answer, while the field thins out fast on a question like “which survey tool should a two-person research team pick, and why”, because most vendor content refuses to name a scenario where the answer isn’t them.
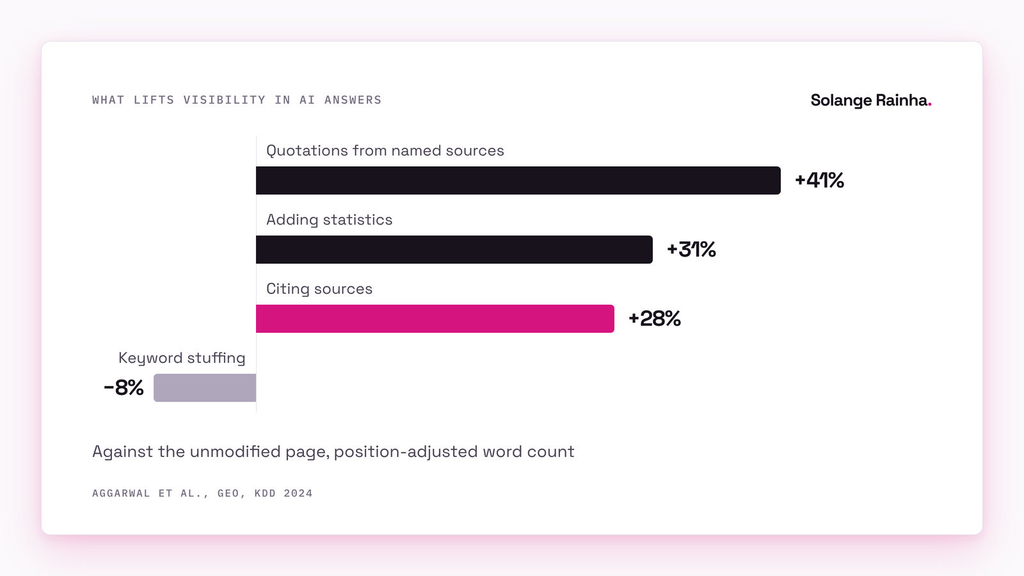
The Princeton GEO study (Aggarwal et al., KDD 2024, 10,000 queries across generative engines) found the methods that lift visibility in AI answers are about substance: quotations from named sources added about 41% on its main measure, adding statistics about 31% and citing sources about 28%, with Search Engine Land’s write-up reporting a 115.1% lift for sites ranked fifth from citing sources, while keyword stuffing fell below the unmodified page. A B2B comparison page built properly is dense with exactly that material: specific attributes and figures, and named third parties.
There’s a second reason, and it’s about when buying decisions get made. 6sense’s Buyer Experience Report, drawn from nearly 4,000 buyers, found buyers chose a vendor from their day-one shortlist 95% of the time, up from 85% the year before. If the shortlist forms during anonymous research and hardens before anyone contacts you, the page that gets you onto it has to do the comparison work itself, and it works best when your awareness content has already set the criteria it judges on, the chain I set out in full-funnel content strategy.
Why do comparison tables get extracted so cleanly?
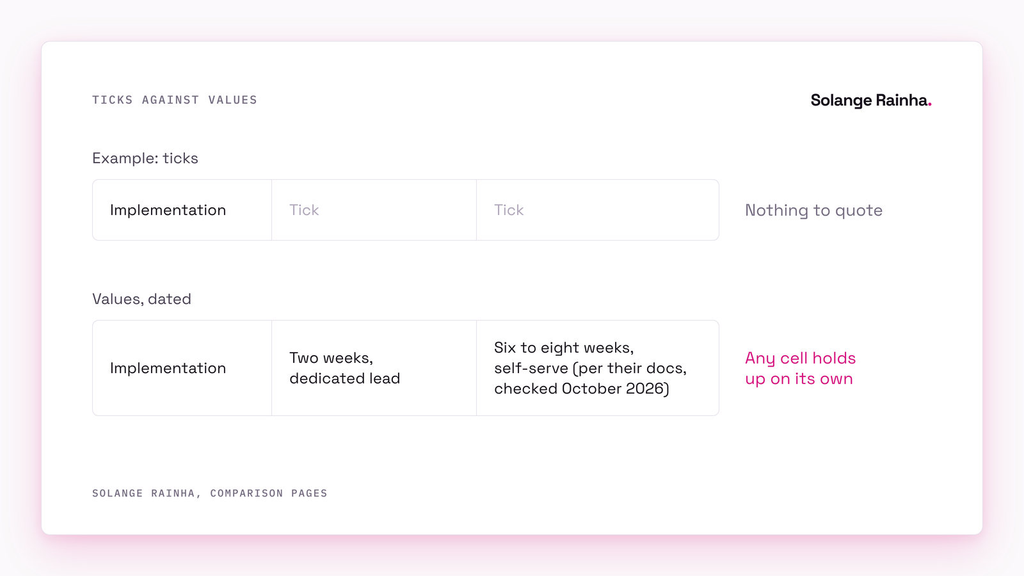
A comparison table hands a model a set of discrete, attributable facts with the relationships already resolved, which is what an extraction system wants and what prose makes it infer. Take one attribute, say implementation time. In prose it’s a clause buried in a paragraph about onboarding, tied to your product only, with nothing to compare it against; in a table it’s a labelled row with a value against each option, and any single cell survives being lifted out of the page. That’s the extraction test in one question: does this fragment still hold its meaning on its own? I’ve broken down the structural side in the tactical guide to making content citable, the engine-by-engine differences in optimising content for ChatGPT, Perplexity and AI Overviews, and the full ordering in my AEO/LLMO content optimisation framework.
The rules I apply to every comparison table:
- Same attributes across every option, in the same order. A table that evaluates you on eight dimensions and the competitor on three is a sales pitch in table form, and both a reader and a model can see it.
- Put values in the cells, never ticks. A green tick tells nobody anything, while “two weeks with a dedicated implementation lead” is a fact somebody can quote, check, and hold you to.
- Anything that moves gets a date, since competitor pricing and feature availability go stale within a quarter, and a wrong figure is the fastest way to lose the credibility the page exists to build.
Structure alone earns nothing, though, and a beautifully formatted table of generic attributes stays invisible, the same problem I’ve written about in why AEO won’t save a weak content strategy and in why so much B2B content sounds identical.
How do you name competitors on a B2B comparison page without legal drama?
Make claims about your own product in absolute terms, and claims about theirs in sourced, dated, factual terms. The rules I work to:
- Quote competitor facts from their own public material (pricing page, documentation, published limits), link the source, and date the capture.
- Never state a competitor is worse in general; state that a specific attribute differs, with the value shown for both.
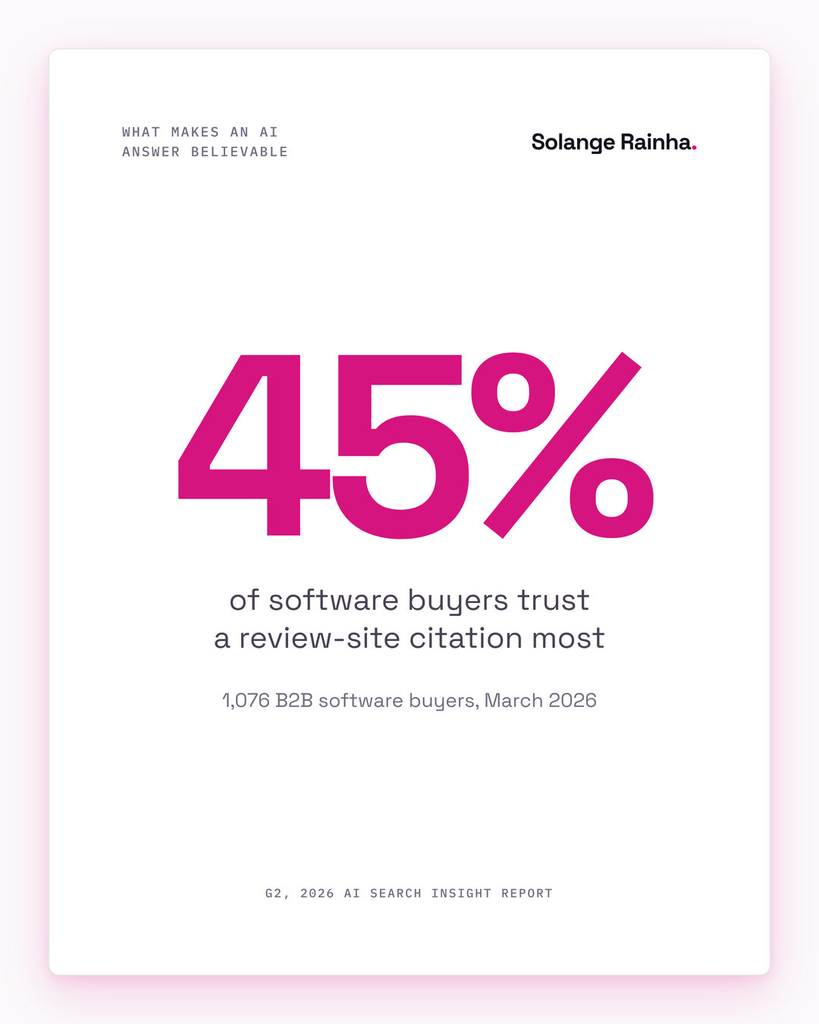
- Use third-party evidence over assertion where it exists. Review platforms carry weight with buyers for a reason, and G2’s 2026 survey of 1,076 software buyers found 45% called a citation from a review site the most confidence-inspiring signal in an AI answer.
- Re-check every competitor claim quarterly and log who checked it, because an unverified comparison table is a liability sitting on your own domain.
The petty version of a B2B comparison page is worse than not writing it, because every buyer in your category has seen the one where the competitor column lists what they can’t do and your column lists what you can, and they read it as ad copy.
The concession is what makes the page credible, so write the sentence that says which buyer should pick the other option, name them specifically, and mean it. Without one “not us” you actually mean, a buyer has no reason to believe the parts where you say “us”.
That sentence also does the strategic work, because ruling out a wrong-fit buyer at the comparison stage is cheaper than ruling them out in month four of a bad implementation, and sales notices the difference in pipeline quality before marketing does. It’s the same standard I apply to writing quality generally, which I’ve argued for in treating editorial quality as a competitive moat.
Which kinds of B2B comparison page do teams collapse into one?
Teams collapse buy versus build, alternatives, and segment fit into one page, even though they answer different questions for different people, and the merged page half-answers all of them.
| Page | The query behind it | Who’s reading | The decision it resolves |
|---|---|---|---|
| Buy versus build | “Should we just build this internally?” | Technical evaluators, CIOs, engineering leads. | Whether the problem is worth in-house engineering time, priced on total cost over three years and not on licence price. |
| Alternatives | “[Vendor] alternatives” or “X vs Y” | Buyers already evaluating a named competitor. | Which of a known set fits their constraints, and where each one loses. |
| Segment fit | “Best tool for a team like ours” | Buyers unsure they’re even your customer. | Whether the product suits their size, stage, sector or workflow. |
The buy-versus-build page is the one B2B SaaS most often ducks, and the one technical buyers most want. It has to price the build openly: engineering months, maintenance, the compliance and security work nobody scopes at the start, and the roadmap that doesn’t ship while your team builds internal tooling. It also has to concede where building wins, which usually means a core differentiator or an internal platform that already solves half the problem.
The alternatives page is the direct one, and the discipline is attribute parity plus dating. It ranks for branded competitor queries, which convert at a rate no top-of-funnel piece touches, and it’s the closest thing in the library to a sales asset that works while nobody’s watching.
The segment fit page is the least built and the cheapest to produce, because it’s mostly disqualification: who this works for, who it doesn’t, and the threshold where you outgrow it. It’s also the one most likely to be quoted by a model answering “is X right for a company like mine”, which is what a buyer asks when deciding whether to bother.
What did I build for build-versus-buy buyers, and what would I add now?
I built the technical trust half of it and left the buy half to sales, which was a gap. At a B2B SaaS company serving 200+ higher education institutions, the go-to-market moved from admissions-led to IT-first, which made CIOs and CTOs the primary buyer, and those are people who evaluate build versus buy routinely. I researched that audience from scratch and built the technical set for them: integration blueprints, security documentation and architecture guides, aimed at the evaluator deciding whether their own team could do this instead. How that content got researched is in writing technical content for CIOs, and the wider rebuild is in the ICP pivot piece.
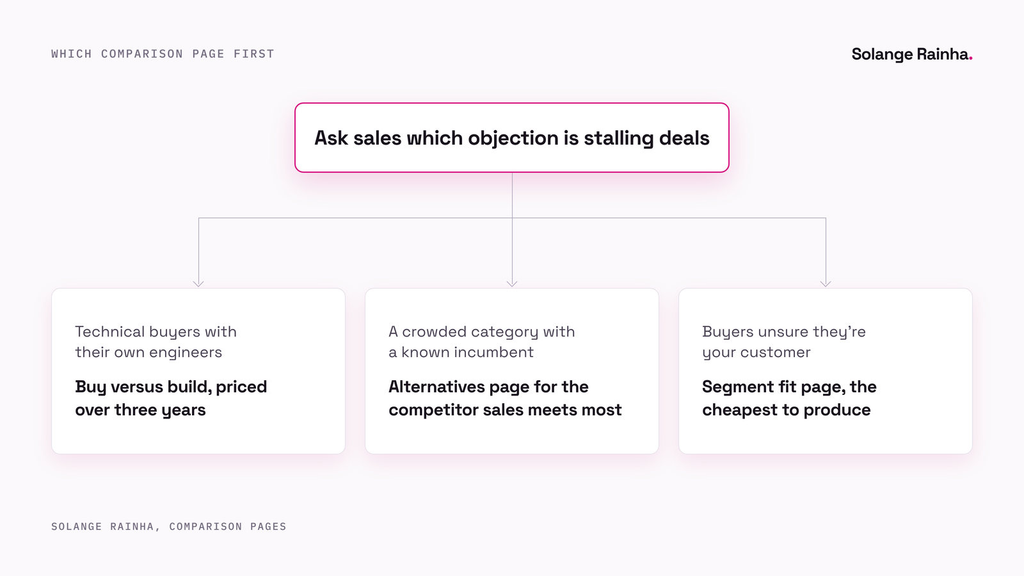
Those were technical trust assets, though, and none of them was a named-competitor comparison page. What I’d add now, in order: the buy-versus-build page with a three-year cost model in place of a licence-price argument, then the segment fit page, then named alternatives pages for the two competitors sales met most often.
Buy versus build was the objection stalling deals, and I’d sequence the rest with my content prioritisation framework: gate on impact, price the effort, then check alignment.
When do trade-offs win deals?
Trade-offs win the deals you keep, and the deals they lose were usually lost already. The fear is that naming a competitor’s strength sends the buyer to the competitor, and fair, sometimes it does, but that’s a deal you’d have lost three months later anyway, with a sales cycle spent on it.
What the concession on a B2B comparison page buys in the deals you keep:
- Credibility on everything else on the page. A buyer who finds one “they’re better at this” reads the rest of your claims as evidence.
- Your champion gets a ready answer for their stakeholders: the person advocating for you has to survive colleagues asking “why not the other one”, and the page that already answered it is what they forward.
- Retrievability, since a model summarising your category pulls the source that names trade-offs, and pages that only assert superiority give it nothing to work with.
- Better-qualified pipeline, because wrong-fit buyers who disqualify themselves on your segment fit page never enter the funnel, and that shows up as a cleaner conversion rate.
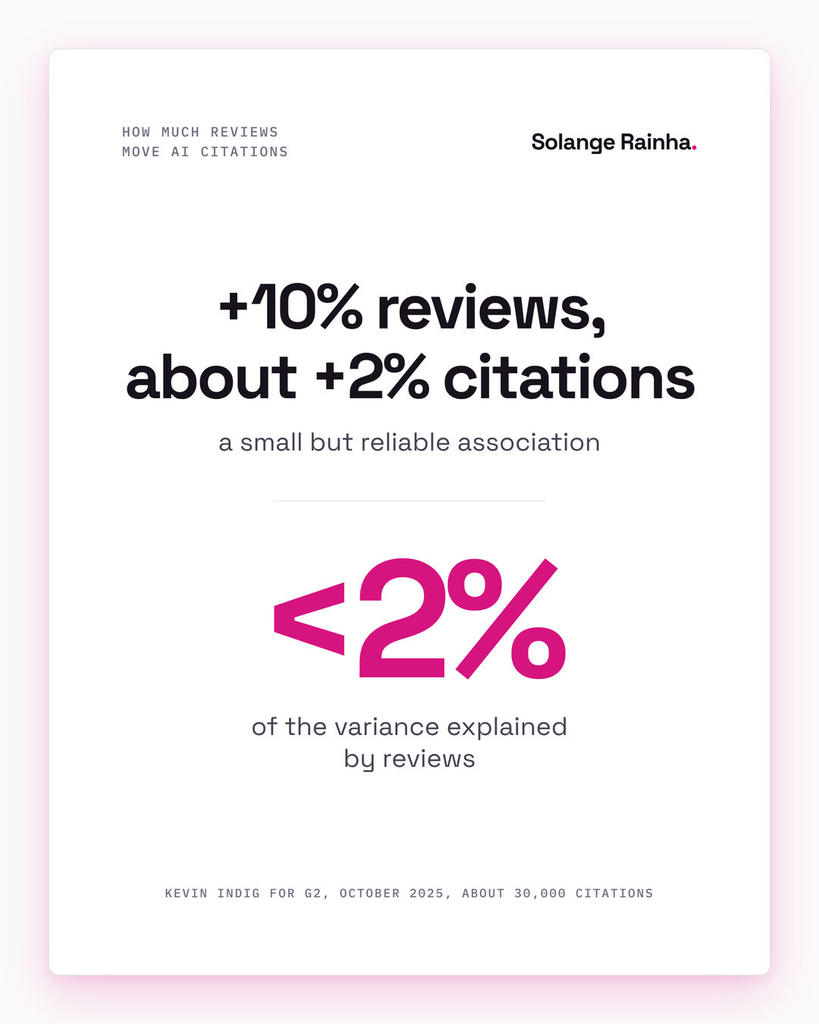
Third-party presence still counts, and I’m not arguing it away, but it does less than review vendors suggest. Kevin Indig’s analysis of about 30,000 AI citations across 500 G2 categories found a 10% increase in reviews went with roughly a 2% increase in citations, and in his words, “Reviews explain less than 2% of the variance.” Run the review programme, just stop letting it be the only place your category gets compared, and track whether your own pages get cited when buyers ask, using a fixed set from prompt research and the signals in measuring AI visibility when analytics won’t show it.
Frequently asked questions
A B2B comparison page is a page on a vendor’s own site that evaluates their product against real alternatives on a consistent set of attributes, including the cases where an alternative is the better fit. It differs from a features page by naming other options and stating trade-offs instead of asserting superiority. Three distinct types get collapsed into one: buy versus build (for technical evaluators considering internal development), alternatives pages (for buyers already evaluating a named competitor), and segment fit pages (for buyers unsure the product suits their size or sector).
Naming competitors is manageable when claims about their product are factual, sourced from their own public material, and dated. State attribute-level differences with the value shown for both options rather than general claims that a competitor is worse, and re-verify the whole table quarterly, since stale pricing and feature claims are the most common accuracy problem on comparison pages. The bigger risk in practice is the opposite: a page with no honest concession reads as marketing, and buyers discount every claim on it.
Comparison pages matter for AI visibility because models answering evaluative questions need evaluative material, and most vendor content is explanatory. A structured comparison table gives an AI system discrete, attributable facts with the relationships already resolved, so any single row survives extraction with its meaning intact. Where vendors don’t publish trade-offs, models pull them from review aggregators instead: one analysis of 1,260 B2B SaaS prompts found the G2 network accounted for around 8% of all citations, and G2’s own analysis put its influence on software queries at 22.4%.
Build the page that answers the objection currently stalling deals, which you find by asking sales what prospects push back on, not by checking search volume. For products sold to technical buyers with in-house engineering capacity, that’s usually the buy-versus-build page, priced over three years including maintenance and compliance work and not on licence cost alone. For crowded categories with well-known incumbents, start with the alternatives page for the competitor sales meets most often. The segment fit page is the cheapest of the three to produce.