Does llms.txt work for AI visibility? Not on any evidence published so far. SE Ranking’s study of nearly 300,000 domains found no link between having the file and being cited by AI systems, Ahrefs found 97% of llms.txt files got zero requests in a month, and Google’s own AI optimisation guide says Google Search ignores them. The file’s spec never promised citations either: it was written to help agents use a website, and its 2026 update leans further that way. Add one in fifteen minutes if you publish developer documentation, or as cheap insurance, and put the budget into substance, third-party mentions and pages a model can lift answers from.
Does llms.txt work? Someone has probably told you it does: a vendor, a LinkedIn post, an audit tool flagging its absence in red. The pitch sounds like robots.txt for the AI era, one small file uploaded once and suddenly ChatGPT and Perplexity cite you more. I build answer engine optimisation (AEO) and large language model optimisation (LLMO) strategy for a living, which is the work of getting a brand named and cited in AI answers, and I’ve written up how the two differ from SEO.
So before recommending the fashionable file to anyone I went looking for citation data instead of vendor promises, and the evidence turned out to be unusually one-sided, with every study published this year pointing the same way.
What is llms.txt, and what does it claim to do?
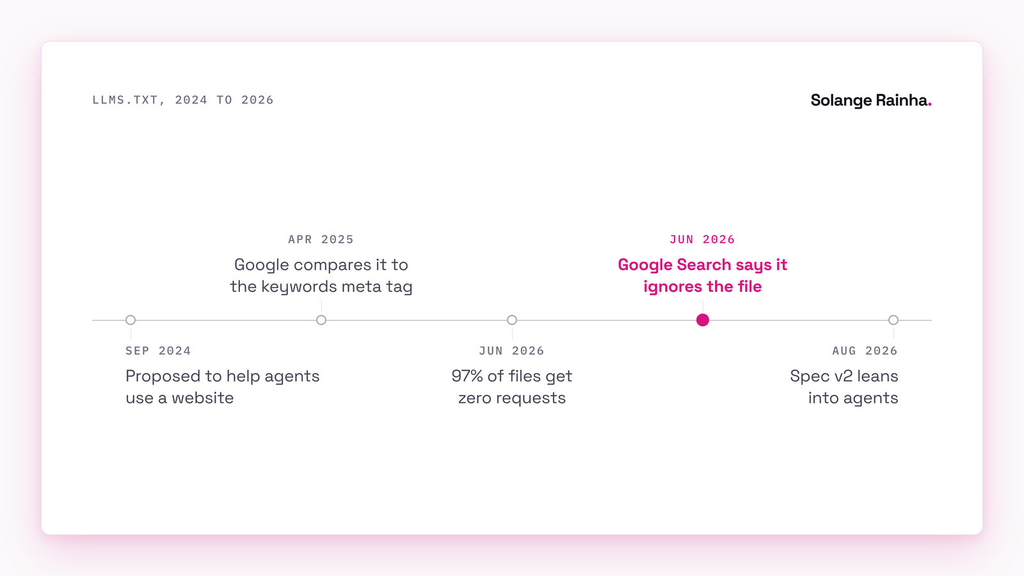
An llms.txt file is a Markdown file at your domain root (yoursite.com/llms.txt) that gives large language models a curated summary of your site, with links to clean versions of your key pages. Jeremy Howard of Answer.AI proposed it in September 2024 as a way to help AI agents use a website without wading through cluttered HTML. It’s a community proposal, so no standards body backs it and nothing enforces it, and each AI company adopts it, or ignores it, on its own terms.
The spec got a second version in August 2026, and the changes all point at agents: link tags that send an agent to a page’s Markdown copy, llms.txt files that can cover a single subfolder, and examples rewritten around how agents use websites today. Neither version claims the file improves search rankings or AI citations, so that promise came from marketing, and it’s the one worth testing: the file takes minutes to make, so the open question is whether anything reads it.
Does llms.txt work for AI citations?
No. Across every large study published so far, having an llms.txt file makes no measurable difference to how often AI systems cite you, and the crawlers it’s built for barely fetch it.
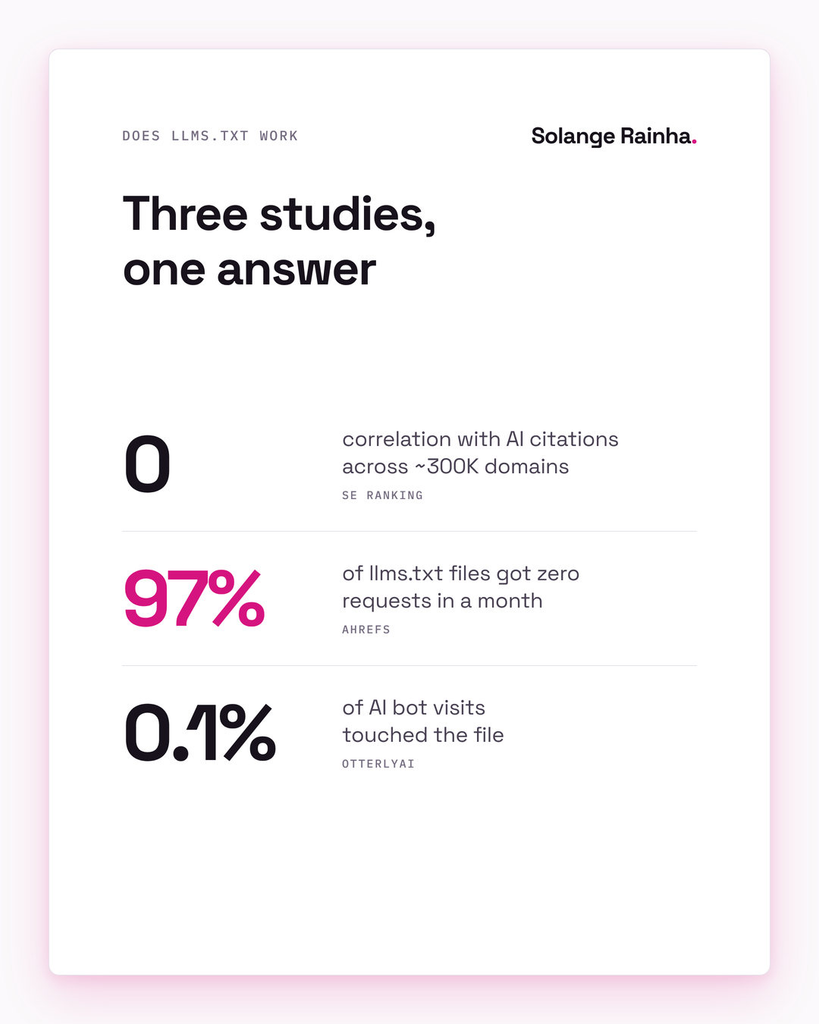
The correlation study comes from SE Ranking, which analysed nearly 300,000 domains using Spearman correlation, an XGBoost model and SHAP analysis to test whether the file predicted how often a domain got cited. It didn’t, and taking the llms.txt variable out of the model made its predictions more accurate, so the file was adding noise. Only 10.13% of domains had one, and sites with over 100,000 visits adopted it less (8.27%) than mid-tier sites did. SE Ranking’s conclusion: “LLMs.txt doesn’t impact how AI systems see or cite your content today.”
Server logs tell the same story from the other end: Ahrefs looked at 137,210 domains in May 2026, about 38,000 of them with a valid llms.txt, and 97% of those files got zero requests that month.
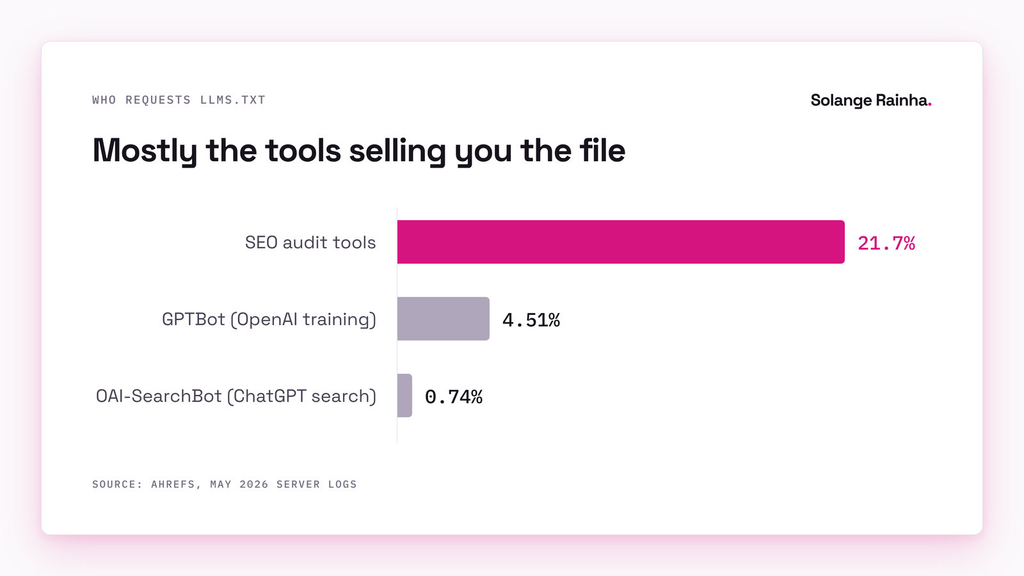
When Ahrefs checked requests for llms.txt files that didn’t exist, AI bots accounted for none of them, so no AI crawler goes looking for the file. The biggest single group reading llms.txt files was SEO audit tools, at 21.7% of all requests, with Ahrefs’s own crawlers making up 10.6% of the total. The top AI fetcher, OpenAI’s GPTBot training crawler, made 4.51%, and OAI-SearchBot, the retrieval bot behind ChatGPT search, made 0.74%. So the most loyal reader of your llms.txt is the audit tool that told you to make one.
OtterlyAI ran the single-site version of the test: over 90 days and more than 62,100 AI bot visits, 84 requests touched the file, about 0.1%, which put it barely ahead of an average PDF on the same site. OtterlyAI then pulled its llms.txt checker out of its own generative engine optimisation (GEO) audit, GEO being the research name for optimising content to appear in AI-generated answers.
Google has now said it in writing, too: the mythbusting section of its guide to optimising for generative AI features, updated in June 2026, says you don’t need machine-readable files, AI text files or Markdown to appear in Google Search, and that llms.txt files “will neither harm nor help your site’s visibility or rankings in Google Search” because Search ignores them. John Mueller, a Search Advocate at Google, had already given the verdict in a Reddit thread in April 2025:
“To me, it’s comparable to the keywords meta tag.”
The keywords meta tag was where site owners typed what they wished they ranked for, and search engines stopped reading it because a site describing itself proves nothing. Mueller added that none of the AI services had said they use the file, and that server logs show they don’t even check for it. Here’s the evidence side by side:
| Source | Scale | What it measured | Finding |
|---|---|---|---|
| SE Ranking (October 2026) | Nearly 300,000 domains | Correlation between having llms.txt and AI citation frequency | No correlation; removing the variable made the model more accurate |
| Ahrefs (June 2026) | 137,210 domains, about 38,000 valid files | Requests to llms.txt files in server logs, May 2026 | 97% of files got zero requests; no AI bot asked for a missing file |
| OtterlyAI (February 2026) | 1 domain, 90 days | Share of AI bot visits touching llms.txt | 84 of 62,100+ visits, about 0.1% |
| Google (June 2026) | Official Search guidance | Whether llms.txt affects Google Search and its AI features | Neither harms nor helps; Google Search ignores the file |
Fair, adoption keeps climbing anyway, which the hot takes skip: Ahrefs puts it at 28% of domains in its sample, which it calls an upper bound because its customers skew technical and SEO-aware, against SE Ranking’s 10.13%. Googlebot also fetched llms.txt files about 900 times in May 2026, as part of ordinary crawling. A file that gets fetched now and then exists as far as a crawler’s concerned, and no study has found any AI system using it as a citation signal.
Why haven’t AI companies adopted llms.txt?
Because llms.txt is a site describing itself, and self-description is the easiest signal on the web to game. That’s Mueller’s keywords-tag point, and AI answer systems already have harder-to-fake ways to judge a source: who else mentions it, who links to it, and whether credible pages back it up.
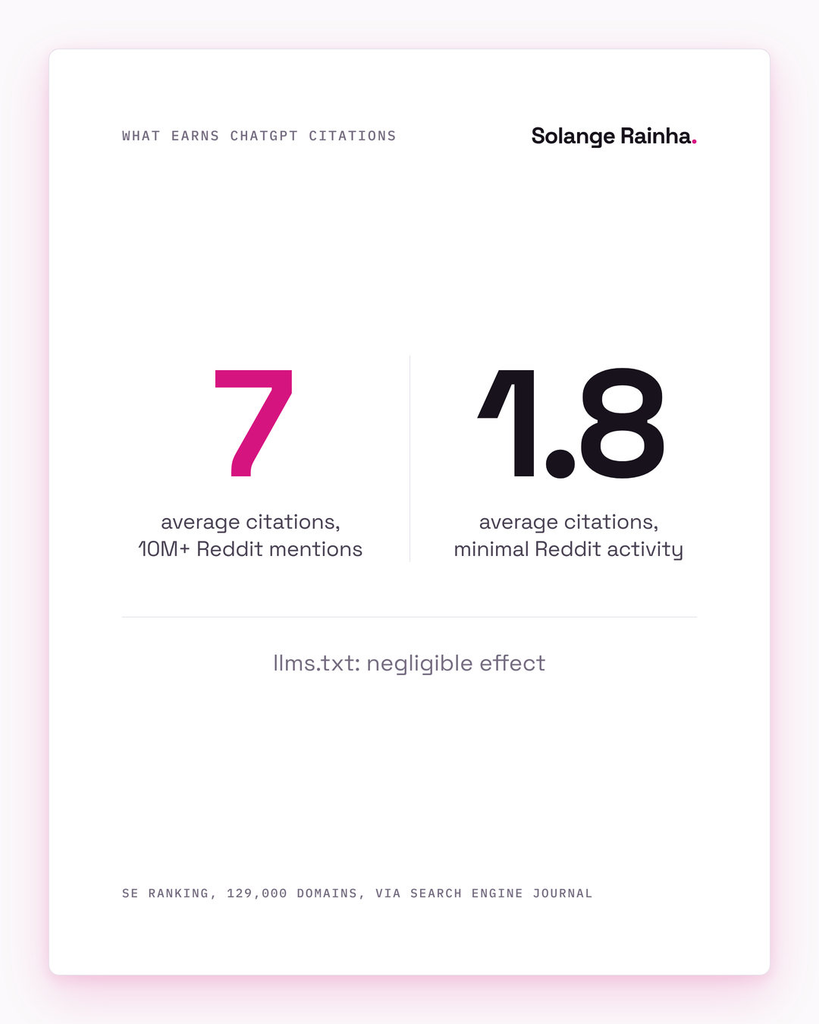
The citation data rewards exactly those outside signals: in a separate SE Ranking study of 129,000 domains, reported by Search Engine Journal, domains with over 10 million Reddit mentions averaged 7 ChatGPT citations, against 1.8 for domains with minimal Reddit activity, and heavy Quora presence showed the same pattern (7.0 against 1.7). The same study found llms.txt had a negligible effect on citations.
There’s a plainer operational reason too: Google says its AI features, AI Overviews and AI Mode included, are rooted in its core Search ranking and quality systems and pull pages from its Search index, which means the retrieval runs on crawled HTML. A second way in, built for a file most sites don’t have and anyone can fill with whatever they like, costs a provider work and buys it nothing. Ahrefs, whose own crawlers are among the file’s busiest readers, says no major LLM provider supports it. The controls AI companies do honour sit in robots.txt and your CDN, which is where Cloudflare’s AI crawler defaults bite.
Where should AI visibility effort go instead?
Into what a model retrieves and what other people say about you, which is what my AEO/LLMO framework is built around, and none of it lives in a root-directory file.
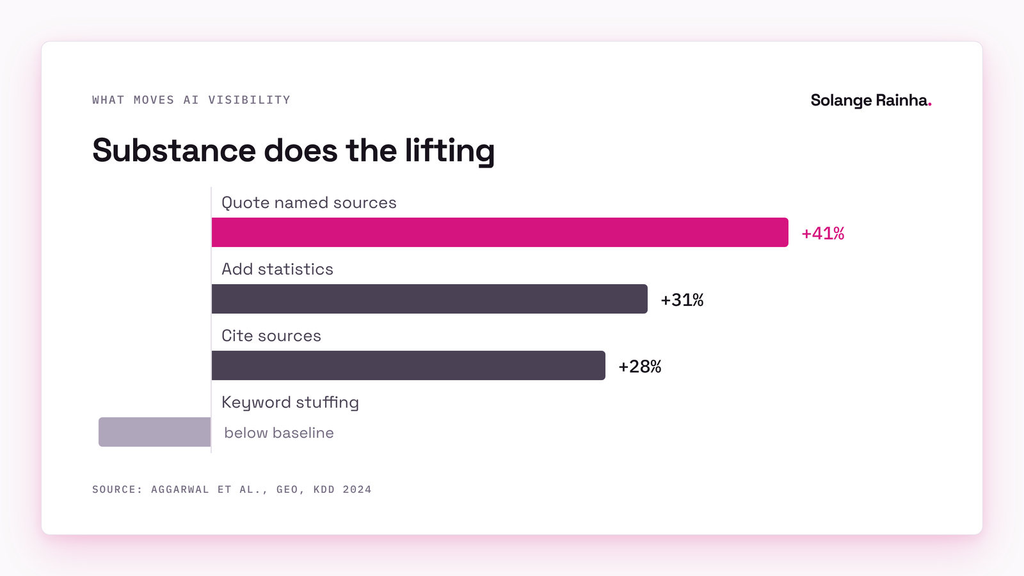
Substance a model can’t get elsewhere comes first: in the Princeton GEO study (Aggarwal et al., KDD 2024), quoting named sources lifted visibility in generative engine answers by about 41%, adding statistics by about 31% and citing sources by about 28%, while keyword stuffing came in below baseline. Citing sources did far more for pages starting lower down: Search Engine Land’s write-up of the study reports a 115.1% lift for the site ranked fifth. That’s the kind of effect people hoped the file would have, and it measurably doesn’t. I’ve written about why structure without substance stays invisible, and llms.txt is the purest example of the pattern: it’s structure about structure.
Off-site presence is next, for the reasons in the Reddit figures above: a model trusts a source more when other people talk about it.
Then there’s the page itself, where front-loaded answers, question headings, self-contained sections and tables all help, because the crawlers that skip llms.txt are reading your HTML, so the HTML is where the optimisation belongs. Auditing a library against those checks is what my AI readiness audit covers, and it’ll do more for citations than any file at your root, since it improves the content that gets retrieved.
And measure the result where it happens: at OpinionX I set up AI citation tracking on 20 buyer prompts across ChatGPT, Perplexity, Claude, Gemini and Google AI Overviews, and the first baseline had OpinionX named in 38% of answers and cited as a source in 37%. Citation share is the scoreboard, and it’s the only one that tells you whether any of this worked. I’ve covered measuring AI visibility without a referral report separately, and it’s the same discipline I apply to content metrics generally.
When is llms.txt still worth adding?
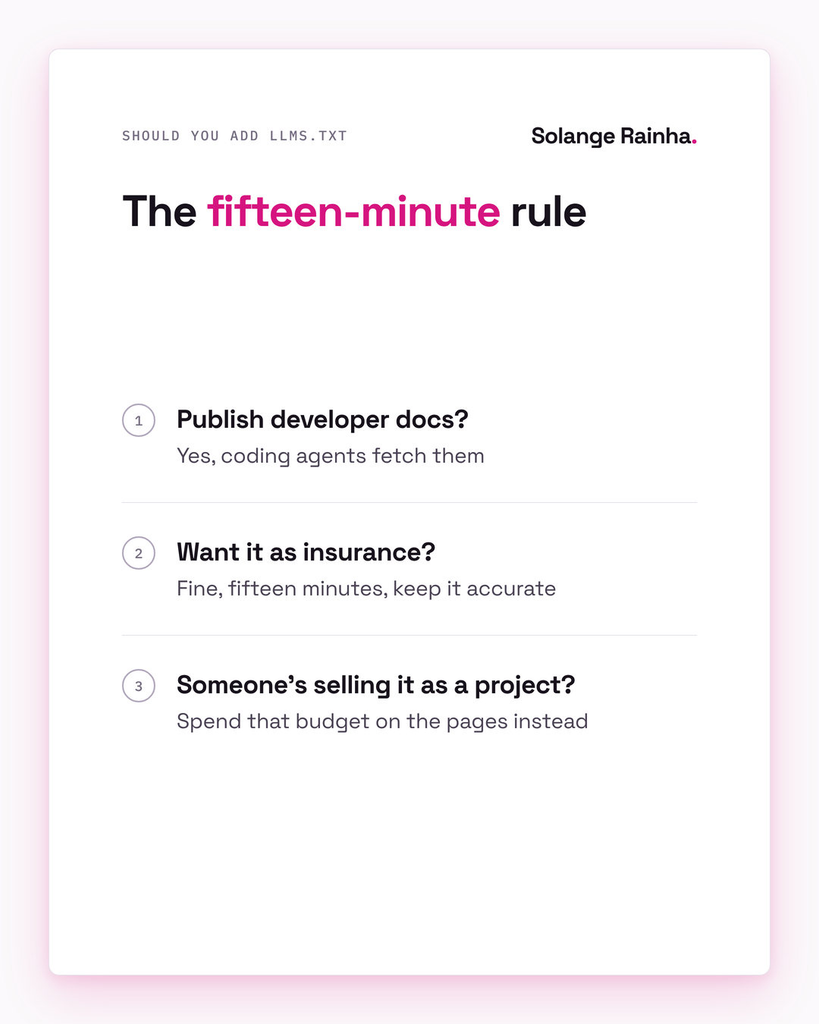
Does llms.txt work for anything, then? Yes, when you publish developer documentation, and it’s also fine as cheap insurance, though neither case has anything to do with citations.
Developer docs are the use the spec was written for. Anthropic, Stripe, Vercel and Cloudflare all publish one (Anthropic, Stripe, Vercel, Cloudflare), each pointing at Markdown versions of their documentation. Coding agents fetch these files: in the Ahrefs logs, Claude Code, Anthropic’s coding tool, was the third most active named AI fetcher, ahead of every AI search and retrieval bot. If you sell to developers, the file is a developer-experience feature and worth an afternoon, and your docs are probably your most citable content already.
For everyone else, it’s insurance: the file costs almost nothing to create and carries little risk as long as you keep it accurate and don’t spin up a Markdown duplicate of every page, and if a major provider ever commits to reading it, you’re already there. Just be clear with everyone involved that it’s a lottery ticket. My content prioritisation framework scores it as impact near zero and effort near zero, which makes it fine as a fifteen-minute task and a waste of a sprint as a project.
What could change this verdict?
A provider announcement. If OpenAI, Anthropic or Google said its answer systems read llms.txt, the server logs would shift within weeks and so would this advice. The studies have limits too: SE Ranking’s is a correlation, Ahrefs’s sample skews toward technical, SEO-aware sites, and OtterlyAI’s covers one domain. None of them can see what a model would do with the file once fetched, but they can all see that almost nothing fetches it, which leaves the “it’s being used quietly” argument with very little to stand on.
So does llms.txt work at all?
Not as an AI visibility tactic. If a vendor’s charging proper money to implement the file, that tells you more about the vendor than the file, and the same evidence-first test applies to the next fashionable checkbox, because AEO built on weak foundations doesn’t get rescued by one.
Frequently asked questions
No, not on current evidence. SE Ranking’s study of nearly 300,000 domains found no correlation between having an llms.txt file and how often AI systems cite a domain, and removing the file from its model made the predictions more accurate. Ahrefs found 97% of llms.txt files got zero requests in May 2026, and Google’s guide on generative AI features says Google Search ignores llms.txt files, so having one neither helps nor harms visibility there.
Yes, for developer documentation, because coding agents such as Claude Code fetch llms.txt files, and Anthropic, Stripe, Vercel and Cloudflare all publish one for their docs. For everyone else, an llms.txt file is optional, low-cost insurance against a provider adopting it later. Treat it as a fifteen-minute task, keep it accurate, and don’t let it take time from the content itself.
Substance, third-party presence and extractable pages. In the Princeton GEO study, quoting named sources lifted AI visibility by about 41%, adding statistics by about 31% and citing sources by about 28%. An SE Ranking study of 129,000 domains found domains with over 10 million Reddit mentions averaged 7 ChatGPT citations against 1.8 for minimal presence. Pages with front-loaded answers, question headings and self-contained sections give AI crawlers clean passages to lift from the HTML they already read.
No. robots.txt is a decades-old convention that major crawlers read and honour, and it controls what they’re allowed to access. llms.txt is a community proposal with no standards body and no enforcement, meant to describe a site to AI agents, and no major AI provider has said it reads the file in production. Google’s John Mueller compared llms.txt to the keywords meta tag, a self-declared signal search engines learned to ignore.