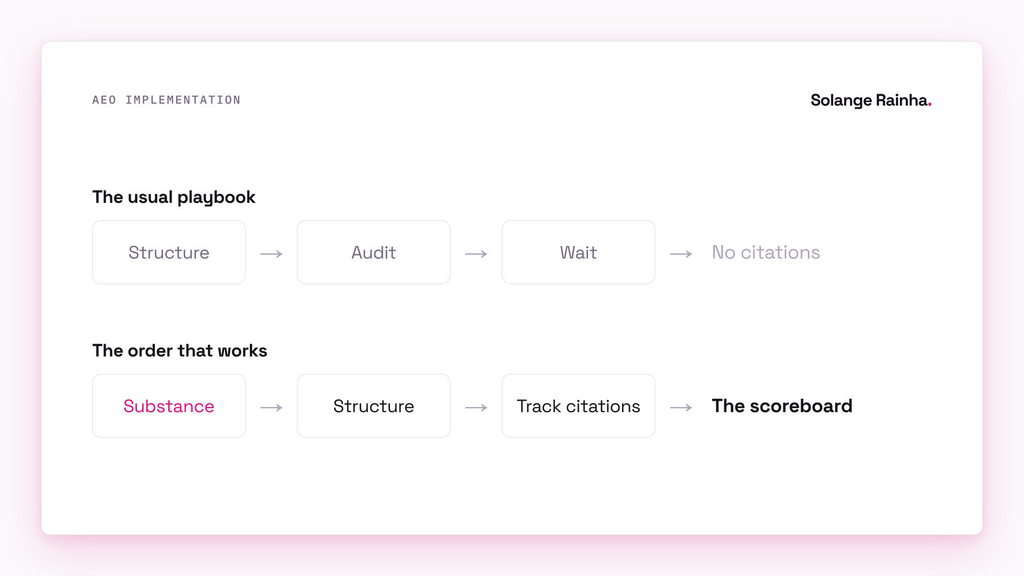
The most common AEO implementation mistakes come from one error: treating answer engine optimisation as a structural retrofit, with schema, FAQ blocks and question headings bolted onto content that already exists. Teams do the structure first, run an audit that scores formatting, then wait for AI citations that never come, because the research on what earns citations points at substance: quotations from named sources, statistics and cited sources. The fix is to run the playbook in the opposite order: substance, then structure, with citation tracking as the scoreboard.
AEO implementation mistakes nearly all come from running the playbook in the wrong order. AEO (answer engine optimisation) is the work of making content easy for search features and AI tools to lift and credit when they answer a question (how it differs from SEO and LLMO is in SEO vs AEO vs LLMO), and the hype around it has a point: the way people find information has shifted. But almost every team I’ve watched start an AEO programme did the work backwards, because the playbook they were handed treats AEO as a layer you apply to finished content: add FAQ schema, rewrite the H2s as questions, drop a TL;DR at the top, run an audit that counts the boxes ticked, then wait for citations.
The citations don’t come, so the team concludes either that AEO doesn’t work or that it needs a better tool, and both conclusions are wrong.
I built an AEO and LLMO framework from scratch at a B2B SaaS company serving higher education and applied it across every content type we shipped, and I’ve since rebuilt it around the order this article argues for. The precondition for any of it working is in AEO won’t save your content strategy: structure can’t rescue weak content. This piece goes one level down, into what teams get wrong once they’ve accepted AEO is worth doing and started.
What are the most common AEO implementation mistakes?
Treating AEO as a technical bolt-on: teams polish the structure, trust audits that score formatting instead of what drives citation, and leave the substance alone. All of it comes from believing AEO is a packaging problem, when it’s a content quality problem. Here’s the order I see teams run, and why each step lets them down.
- They start with the structure: schema markup, question headings, FAQ blocks, answer-first paragraphs. It’s the easy, satisfying part, because it’s mechanical and a junior marketer or a plugin can do most of it in an afternoon, so teams do it first and thoroughly, and it becomes what they point to when leadership asks “are we doing AEO?”
- Then they run an audit (usually a tool, sometimes an agency deliverable) that checks whether the schema validates, the headings are questions, there’s a summary block up top and the FAQPage markup is present. The score goes up when you add structure, so the team adds more structure.
- Then they wait, but content that was thin and interchangeable before the treatment is just as thin after it, now with nice schema, and AI tools read the prose, which didn’t change.
The sequence polishes the cheapest, most measurable layer and leaves alone the one that decides whether you get cited. It’s the first of the AEO implementation mistakes and the one almost nobody names, because the order feels intuitive.
Google’s own guidance undercuts the schema-first instinct too: its documentation on AI features says there are no extra requirements or special optimisations needed to appear in AI Overviews or AI Mode, and puts it plainly:
“There’s also no special schema.org structured data that you need to add.”
And the FAQ block that so many AEO checklists treat as essential stopped earning rich results for most sites years ago: in August 2023 Google limited FAQ rich results to well-known, authoritative government and health websites. FAQ sections still help readers and extraction, and I write one for every piece, but on their own they won’t get you cited.
Why do AEO audits measure the wrong signals?
Because they measure what a machine can check, which isn’t what a machine cites. Schema validation, heading format and the presence of an FAQ block are checks a script can run in milliseconds; whether your content holds a specific, attributed statistic a model will reach for when it answers a question takes judgement, so a generic audit doesn’t check it, and AEO implementation mistakes sail through a clean report.
You end up with a green dashboard and no citations, the worst combination going, because it tells you you’re fine when you aren’t. Structure has value: front-loaded answers, clean headings and self-contained sections help extraction, and I build all of them into every piece. The trouble starts when teams treat that work as the finish line. An audit that only scores structure measures whether content is extractable without asking whether it’s worth extracting, and the second question is the one that pays.
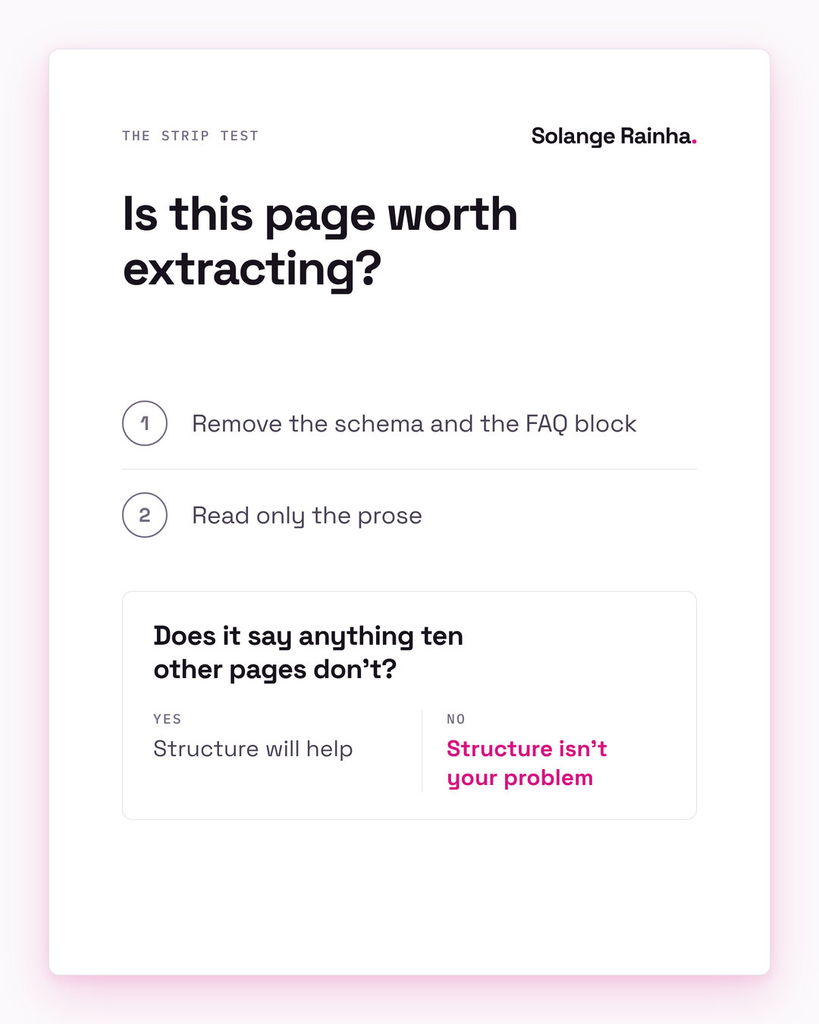
There’s a quick test: strip the schema and the FAQ block off a page and read the raw prose. Does it say anything a model couldn’t synthesise from ten other pages making the same point? If not, structure isn’t the problem. When I built my own AI readiness audit, citable substance became the check that carries the most weight for exactly this reason, and running it on my own site turned up my weakest score on attributed evidence, which was humbling.
What does the research say drives AI citation?
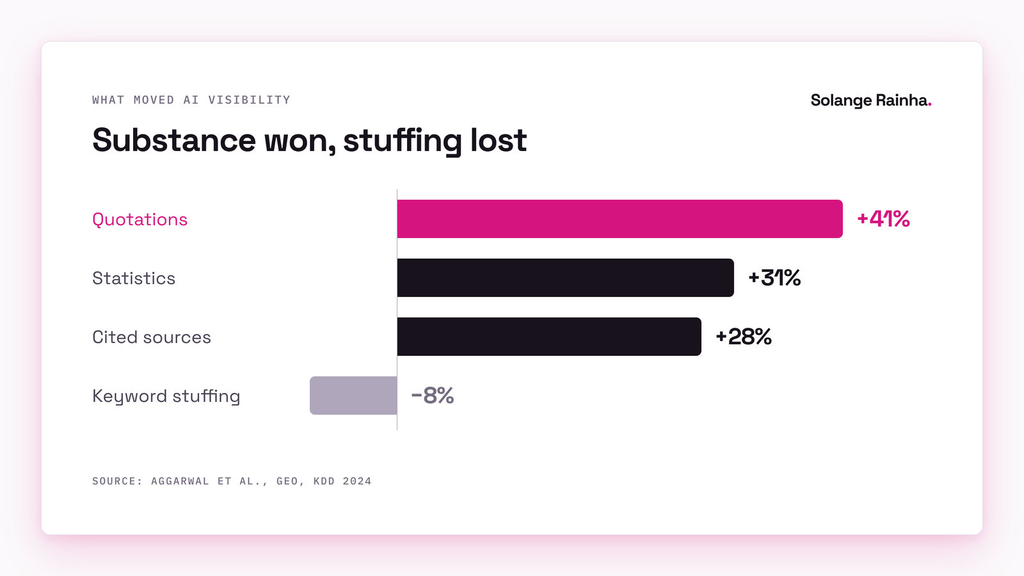
Substance, mostly, and this is where the consensus and the evidence part ways. The most cited measurement is the Princeton GEO study (Aggarwal et al., presented at ACM KDD 2024), which tested nine ways of rewriting content across 10,000 queries on generative engines; GEO, generative engine optimisation, is the academic name for roughly what marketers call AEO. The study’s headline finding is that the right changes can lift visibility in AI answers by up to 40%, and the changes that did the lifting were content changes:
- Adding quotations from named sources was the strongest method, lifting visibility by about 41% on the paper’s word-count measure and 28% on its impression measure.
- Adding statistics lifted it by about 31% and 23% on the same two measures.
- Citing external sources lifted it by about 28% overall, and far more for pages that started further down: Search Engine Land’s write-up of the study reports a 115.1% increase for websites ranked fifth, while the top-ranked site’s visibility fell 30.3% on average.
- Keyword stuffing came in below the unmodified baseline.
Read that list with the standard playbook in mind: quotations, statistics and source citations are content quality moves. They need research, something specific to say, and knowing who the credible voices in your field are well enough to quote them accurately. Schema and heading format aren’t on that list, and neither is anything a typical AEO audit scores.
Newer data points the same way at sentence level: Kevin Indig’s 2026 analysis of 1.2 million AI answers and 18,012 verified ChatGPT citations found cited passages were nearly twice as likely to use clear definitions, and 44.2% of citations came from the first 30% of a page. Models reward what a discerning reader rewards (specific claims, evidence and a point of view), as long as the structure doesn’t get in the way.
What do AEO implementation mistakes look like on the page?
Put a weak page next to a strong one and the difference is obvious, because “add substance” is the kind of advice that’s true and useless at the same time. Take one topic, “What is customer onboarding?”, done twice:
| Bad AEO | Good AEO | |
|---|---|---|
| Opening | A summary box restating the title | A direct answer to the question in the first 150 words |
| Claims | Onboarding “is important” and “improves retention” | A specific claim with a named study, a percentage and a year |
| Sources | None | Cited inline, where each claim sits |
| Expert voice | None | A named practitioner, quoted accurately |
| Evidence | Prose only | A comparison table of onboarding approaches and their trade-offs |
| Argument | Nothing a competitor’s page doesn’t say | A position on which approach suits which company stage |
| Audit score | 95/100 | Similar |
| Cited by AI tools | No | Has a reason to be |
Both pages are well formatted, and the bad one might even score higher, but only the good one says anything. The bad one has the outline of saying something and nothing inside it, so when a model assembles an answer about onboarding, that page offers nothing it can’t get elsewhere and nobody quotes it.
How should you order AEO work instead?
Invert it: the standard playbook says write the content, then apply AEO, while mine treats the AEO decisions as content decisions, made before and during writing. That one reordering prevents most AEO implementation mistakes, because nobody can skip the substance work when it’s step one.
So the substance comes first. Before schema enters my head, I’m asking what specific, attributable claims this piece can make that nobody else is making, what data I’m citing and whether the source is credible and current, and whether there’s an original observation from my own work that a model can’t pull from the recycled takes everyone else publishes. That part earns the citation, so that’s the part I protect.
Structure comes second, and it’s non-negotiable but fast: front-load the answer, write headings as the questions people ask, keep sections self-contained so they survive being lifted out of context, and attribute every claim visibly. The full version is my AEO and LLMO content optimisation framework (I tell the story of building it in most B2B content is invisible to AI search), the section-level tactics are in write for humans, structure for machines, and the platform-specific layer is in optimising content for ChatGPT, Perplexity and AI Overviews.
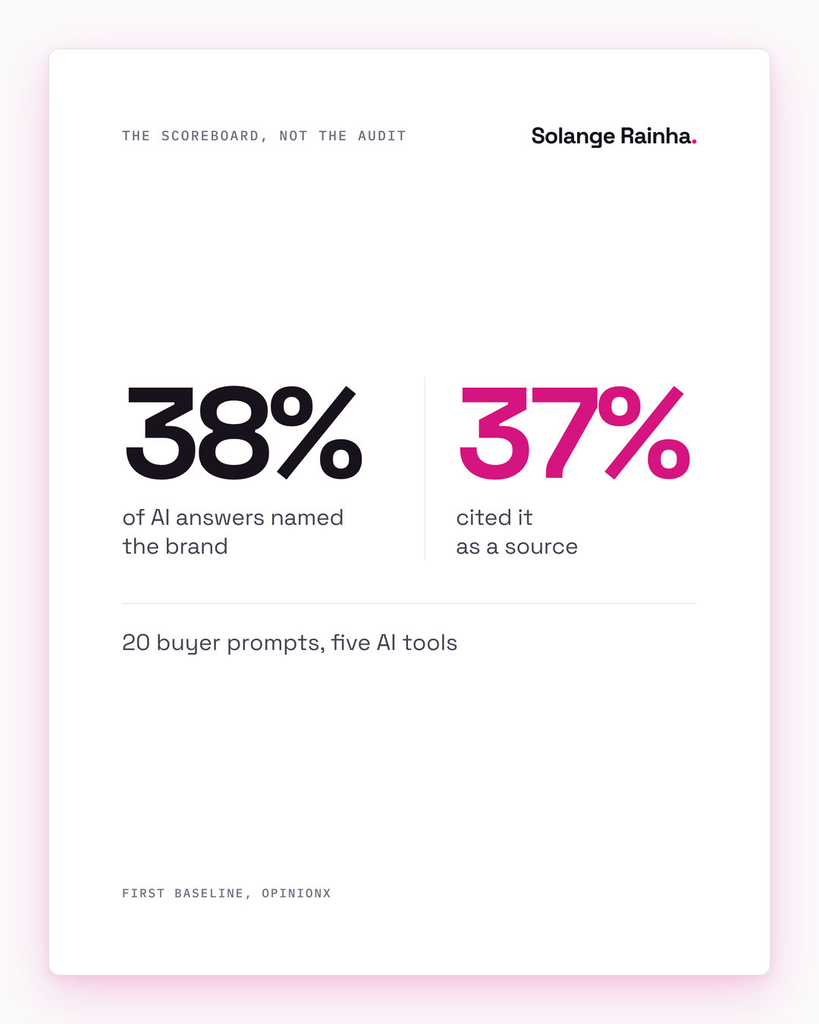
Then measure the outcome that counts: a green audit tells me my structure is clean and nothing about whether I’m being cited, so I track AI citations directly, which I’ve written up in how I track whether AI is citing my content. When I set that up at OpinionX, running 20 buyer prompts across ChatGPT, Perplexity, Claude, Gemini and Google AI Overviews, the first baseline had the brand named in 38% of answers and cited as a source in 37%. That’s a figure I can move and report, and no audit score would have shown it to me.
What would I do differently, and what am I still unsure about?
When I first built my framework, I made the same AEO implementation mistakes: the original version leaned hard on extractability mechanics, because that’s where my head was. I’ve since rebuilt it so the substance decisions (original data, named sources, a position) sit at the top, and I label the structure work as second-order.
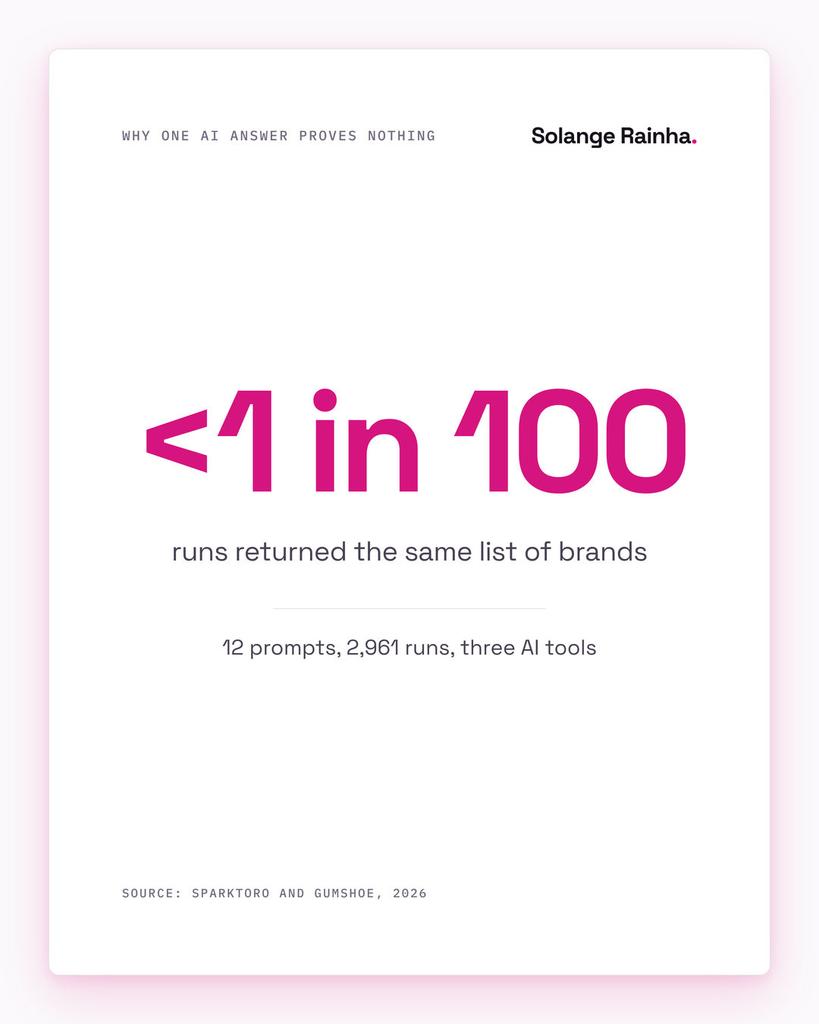
I’m also wary of the citation figures everyone quotes, mine included. The Princeton study is solid, but it’s from 2024, it tested a subset of results rather than live Google rankings, and the engines have changed since. AI answers also move a lot from one run to the next: SparkToro and Gumshoe had 600 volunteers run 12 prompts through ChatGPT, Claude and Google’s AI 2,961 times, and found the tools rarely return the same list of brands, fewer than 1 in 100 times. That’s why I track visibility as a share across many runs and ignore any single month.
The direction holds, with substance ahead of structure, but the exact sizes of those effects are softer than the confident playbooks make them sound, and the order itself has held up across every content type I’ve applied it to.
Frequently asked questions
The biggest AEO implementation mistake is treating answer engine optimisation as a structural retrofit applied to finished content, instead of a set of content decisions made during writing. Teams add schema, question headings and FAQ blocks to thin content, run an audit that scores formatting, and wonder why AI tools never cite them. Structure is necessary but second-order, because the substance (specific data, named sources and a clear argument) is what earns the citation, so it has to come first.
AEO audits don’t predict citation because they measure what a script can check, such as schema validity, heading format and whether an FAQ block exists, and their scores rise as you add structure. None of that checks whether the content holds the quotations, statistics and cited sources that the Princeton GEO study found lifted AI visibility by up to 40%. Google also says you don’t need special schema to appear in AI Overviews. That’s how AEO implementation mistakes pass an audit with a high score.
No. The Princeton GEO study (Aggarwal et al., KDD 2024) found that content changes, adding quotations from named sources, statistics and citations, drove the biggest visibility gains, but structure still helps AI tools extract content cleanly. Front-loaded answers, question headings and self-contained sections are worth doing. The point is order: structure is fast and cheap, and it only pays off once the substance underneath gives a model a reason to cite you over ten similar pages.
Measure AEO by tracking whether AI tools cite you, not by audit scores. Pick a fixed set of buyer-style prompts, run them across ChatGPT, Perplexity, Claude, Gemini and Google AI Overviews, and log how often your brand is named and cited. Because AI answers vary a lot between runs, read the share across many runs and the trend over months rather than any single result. My first baseline at OpinionX, from 20 prompts across five AI tools, had the brand named in 38% of answers and cited in 37%.