AI-citable content is content structured so that AI systems can parse, extract, and cite it when generating answers. This article is the tactical companion to the AEO/LLMO framework I built from scratch: the specific patterns that turn ordinary writing into AI-citable content, with before-and-after examples and the editorial rules I used to enforce each one across a full B2B SaaS content library.
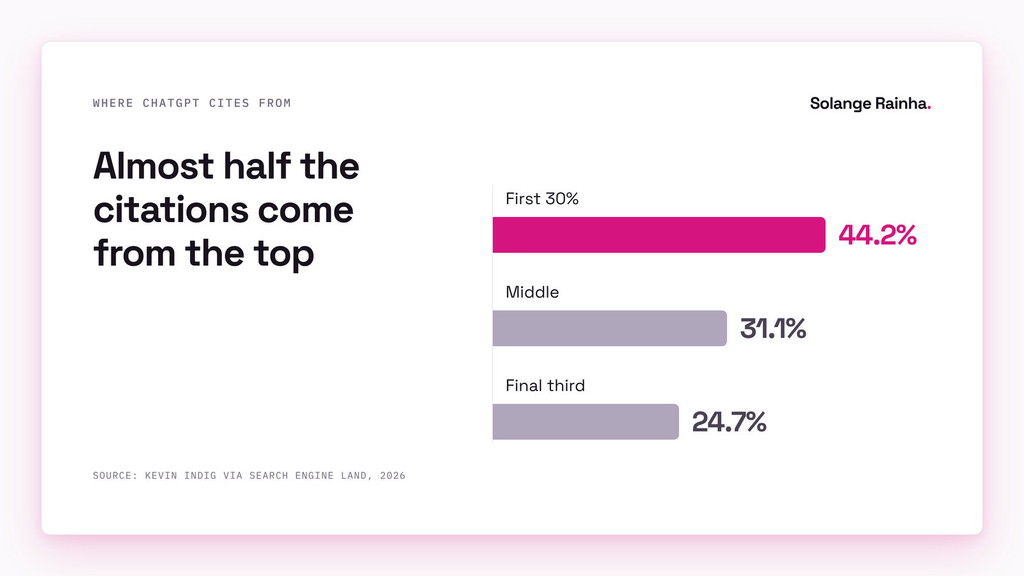
AI-citable content comes down to four patterns: claims specific and verified enough to quote, sources attributed in the same sentence as the claim, a summary in the first 150 words that actually answers the question, and FAQ answers that work on their own. Where you put things counts as much as what you write, because Kevin Indig’s study of ChatGPT citations, reported by Search Engine Land in February 2026, found 44.2% of citations came from the first 30% of a page. I enforced all four patterns across the content library of a B2B SaaS company serving 200+ higher education institutions. If you only steal one habit from this guide, make it the source log, because it fixes your claims and your attribution in one go.
I covered the strategy in the AEO/LLMO framework piece, and the full method lives on the AEO/LLMO content optimisation framework page. This one’s the tactical playbook, the stuff you can take into your next blog draft or product page rewrite tomorrow. It covers blog posts, product pages, whitepapers, FAQs, landing pages and sales enablement, which is everywhere I tested these patterns before writing the ones that survived into editorial standards a one-person content function could actually follow.
What makes a claim citable?
A citable claim is one an AI tool could quote and still look credible doing it, which means it’s specific and verifiable, with its source named. That was the test I ran on every piece before it went live, and most B2B SaaS content fails it, usually because the information’s fine but written too vaguely or hedged too much to be worth quoting.
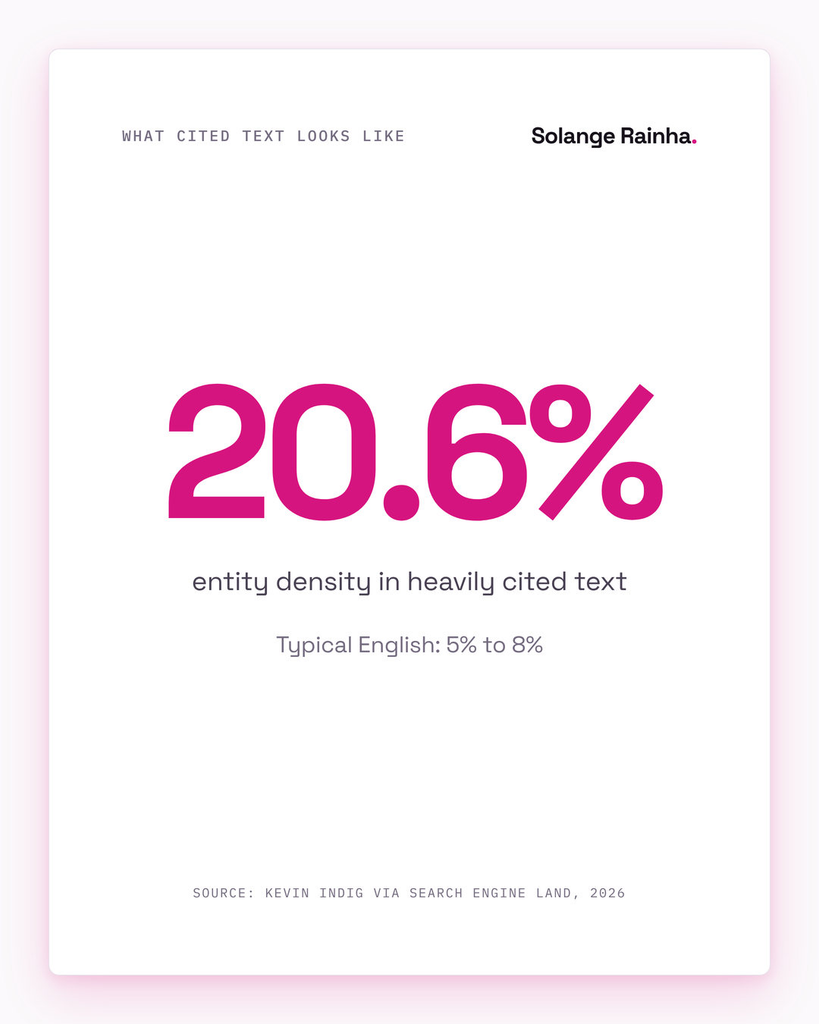
The research points the same way: the Princeton team behind the GEO study found that adding statistics, quotations from named sources and citations lifted visibility in AI answers by up to 40%, and Indig’s data shows what that looks like at sentence level, with cited passages nearly twice as likely to use clear, definitive language and heavily cited text averaging 20.6% entity density (proper nouns, numbers, specific terms) against 5% to 8% in typical English.
Here’s the difference in practice, with a made-up product so nobody gets ideas:
“Our platform is designed to help institutions streamline their operations.”
“Institutions using [Product] reported a 34% reduction in manual data entry across admissions workflows, based on a 2024 cohort study of 18 universities across four countries.”
The first one is pure marketing language with nothing to hold onto, while the second gives a model the claim, the metric, the method and the scope, so it can quote the sentence with confidence and attribute it to you.
The editorial rule behind it. I built a verification process where I traced every quantitative claim and comparison, plus any timeline, back to a documented source: help documentation, internal project data, stakeholder sign-off or published third-party research. I kept a source log for every piece, and if I couldn’t trace a claim, I cut it entirely instead of hedging it with “approximately” or “roughly”. That process turned out to be one of the most valuable things I built in that role, and I’ve written about the editorial discipline it takes separately. If your team writes help docs, read why product documentation is outranking your blog in AI answers too, because those pages tend to pass this test by default.
How should you attribute sources so AI tools trust them?
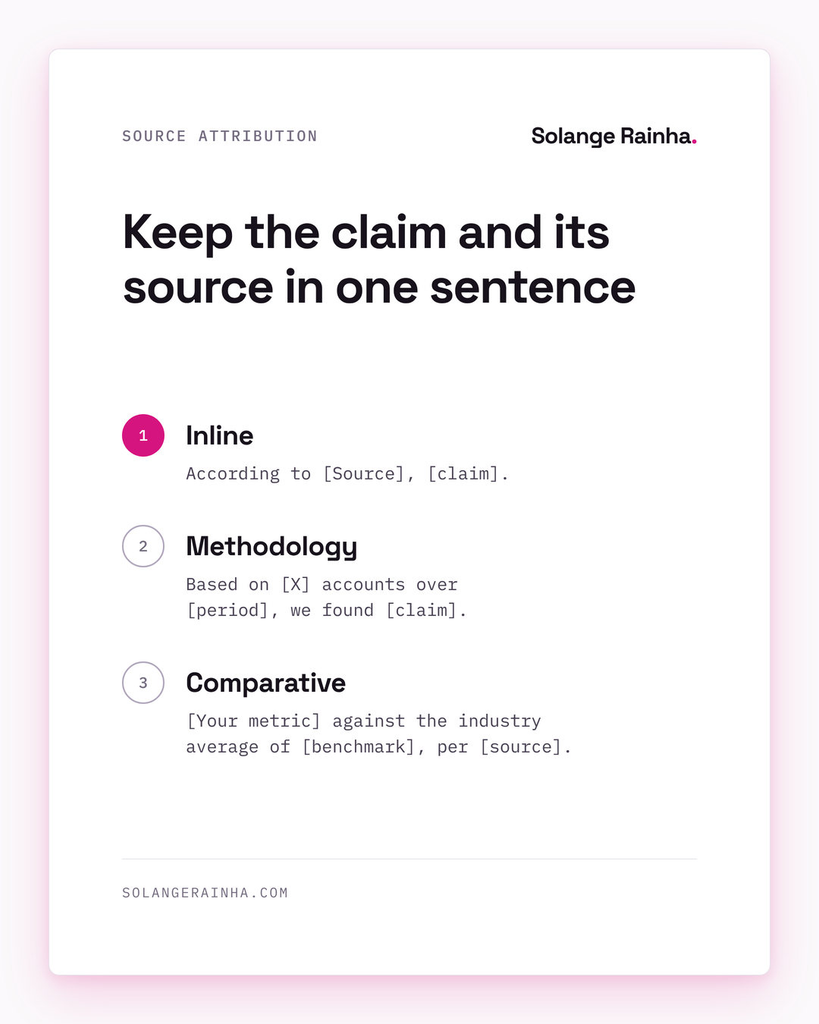
Put the source in the same sentence as the claim, every time. Traditional SEO never asked for much here (write the stat, maybe link it, done), but AI-citable content needs the claim and its source to travel together, because a model lifting your sentence takes whatever’s inside it and nothing around it.
The attribution patterns I used cover nearly everything:
- Inline attribution, the simplest and most useful: “According to [Source], [claim]” or “[Claim], based on [Source]’s [Year] report.” The claim and the source live in one sentence, so the model is more likely to cite you, with your source attached, instead of going off to find the original.
- Methodology references for your own data: “Based on analysis of [X] accounts over [time period], we found [claim].” It tells the model the data is primary and gives it the sample size and scope.
- Comparative framing against a benchmark: “[Your metric] compared to the industry average of [benchmark], according to [source]”, which packs your figure and a sourced benchmark into one line.
Avoid unsourced superlatives: “Best-in-class”, “industry-leading” and “world-class” are empty marketing language, and they hurt citability too, because they tell a model the whole page is promotional, which drags down the credibility of everything else on it.
Every piece I published went through a credibility audit, where I flagged each claim missing visible attribution and each superlative with nothing behind it. The rule was simple: if you can’t show your work, rewrite the sentence until you can. Sometimes that meant killing impressive-sounding claims because I couldn’t verify the data underneath, and that was always the right call.
How do extractable summaries make content AI-citable?
An extractable summary is a short block in the first 150 words that answers the page’s question completely, so an AI tool that reads only the top still gets the point. Most long-form B2B content opens with scene-setting instead, a bit of context and industry framing, maybe a provocative question. That’s fine for someone scrolling with a coffee, but it’s useless for a model trying to work out whether your page answers a query, and Indig’s data above shows how heavily citations lean on the top of the page. His own description of how a model reads is the best one I’ve seen:
“It’s a busy editor, not a patient student.”
Instead of opening with “The landscape of higher education technology is evolving rapidly”, a blog post about choosing an enterprise SaaS platform for higher education should open with something like this:
“Enterprise SaaS selection for higher education institutions depends on five factors: integration depth with existing student information systems, data security compliance with regional education standards, scalability across multi-campus deployments, total cost of ownership over a five-year horizon, and vendor stability. This guide breaks down each factor with evaluation criteria and common pitfalls.”
A model can quote that and attribute it, while the first version just sends it digging further for the answer.
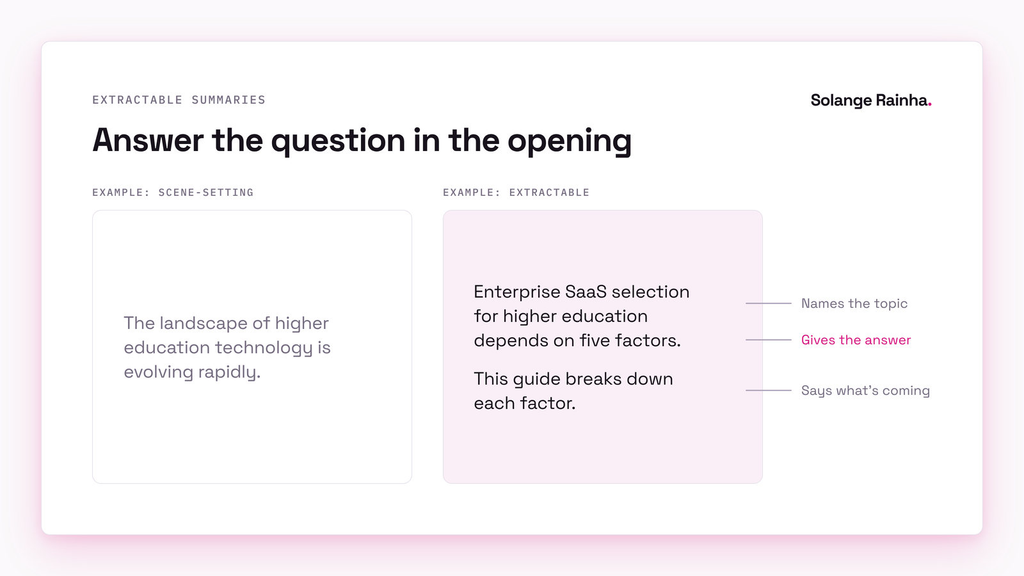
The editorial rule I used: every piece over 1,000 words needed a summary block in the first 150 words that said what the piece was about and who it was for, plus what the reader would know by the end. If the summary didn’t work as a useful paragraph stripped from the rest of the article, I rewrote it until it did. The craft side of this, for human readers as much as machines, is in how to write an opening that survives the scroll.
What makes an FAQ section AI-citable?
An FAQ is AI-citable when every answer works as a standalone unit, naming the product or topic and answering the question with at least one concrete detail, and most FAQ sections fail that badly. A typical answer assumes you’ve read the page it sits on, so you get “Yes, we support that. You can set it up through the integrations dashboard”, which means nothing without the question, or without knowing what product we’re talking about.
Question-led structure is worth the effort: Indig found cited content was twice as likely to contain a question mark, and 78.4% of citations tied to questions came from headings, which is exactly what FAQ questions are.
Before: Q: Does it integrate with our existing systems? A: Yes! We offer a wide range of integrations. Check out our integrations page for the full list.
After: Q: Does [Product] integrate with existing student information systems? A: [Product] offers native integrations with major student information systems including [System A], [System B] and [System C], as well as a REST API for custom integrations. Setup requires no custom development and typically takes under two hours for standard SIS connections.
The second version answers a question someone actually asks with specifics, so a model reading it doesn’t have to guess anything.
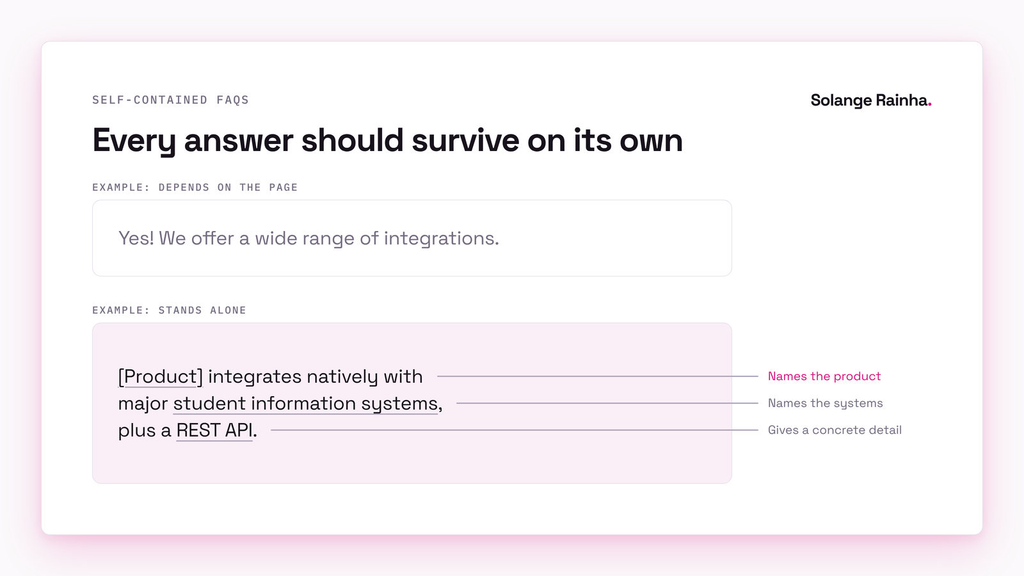
I tested this by reading every FAQ answer in total isolation: if I couldn’t tell what product, company or topic it referred to without the question or the page around it, I rewrote it. I also put the question’s core terms into the answer text, so the pair held together even when the question wasn’t next to it. I’ve covered how the major engines treat FAQs differently in how to optimise content for ChatGPT, Perplexity and AI Overviews.
How do you make AI-citable content repeatable?
You make AI-citable content repeatable by writing the rules into the content brief, so every piece gets checked before it’s written rather than rescued after. I folded the AI-citable content requirements into the brief alongside the usual SEO, audience and funnel-stage specs:
| Brief requirement | Applies to | The rule | Pre-publish test |
|---|---|---|---|
| Claim verification | Everything | Every quantitative claim, comparison or timeline has a documented source in the source log | Pick any figure and find its source in under a minute |
| Attribution | Everything | At least one inline attribution per 500 words, methodology references for any proprietary data, no unsourced superlatives | Search the draft for superlatives and unlinked figures |
| Summary block | Anything over 1,000 words | Answers what it’s about, who it’s for and what they’ll learn, inside the first 150 words | Read the block alone: does it work as a paragraph? |
| FAQ section | Product and landing pages; blog posts over 1,500 words | Every answer self-contained, with the question’s core terms repeated | Read each answer without its question |
| Extraction test | Everything | Every H2 section makes sense on its own | Read each section in isolation and fix any that lean on the one above |
It adds maybe 15 to 20 minutes to a typical blog post once the habits click, and what comes out works for traditional search, AI search and plain old reading. I built the same requirements into the editorial standards I maintained for the company, so every piece went through the same checklist whether I wrote it or a freelancer did. My reasoning was that a model judges what your site knows from more than one page, and a library where half the pages follow the rules sends it a mixed signal. If you’re retrofitting a library rather than starting fresh, the five checks I run on a content library are the place to start.
What are the limits of AI-citable content?
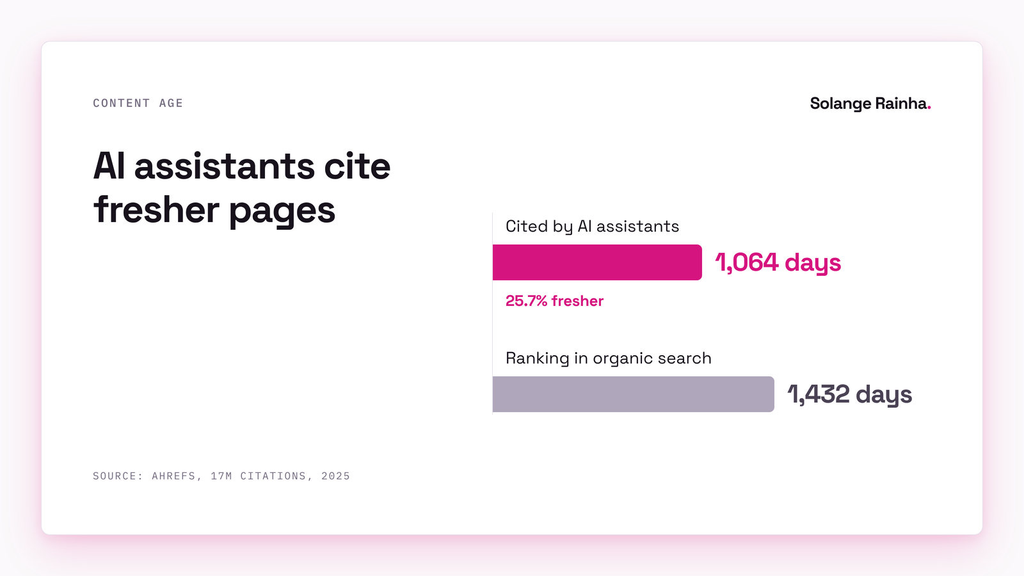
AI-citable content raises your odds of being cited without guaranteeing anything, because how AI tools pick and cite sources keeps shifting. Ahrefs’ analysis of 17 million citations found AI assistants cited content that was 25.7% fresher than what ranked in organic results, with Google’s AI Overviews the one exception, so a page that’s perfectly structured today still needs updating to stay in the answer set.
I originally quoted a 4.4x conversion premium for AI-referred visitors as the business case, but the only multi-site study I’ve found that tested for significance, Amsive’s analysis of 54 sites, saw no significant overall difference, though its B2B sites did see AI referrals convert at 2.17% against 1.16% for organic. I’ve gone through that evidence properly in tracking AI traffic in GA4, and the short version is that citations are a better case for this work than conversion multiples.
These AI-citable content patterns worked in practice: the content operation that used them grew organic traffic 33% quarter on quarter and contributed to 48% of marketing-sourced pipeline in peak months, at a company where I was the only content person, though citability was one ingredient in that and I can’t isolate its share.
If I set up the brief again, I’d put claim verification at the top rather than the summary block, because verification is the step teams skip whenever it isn’t first; I’ve written up the AEO implementation mistakes that come from doing it the other way around. And none of it saves a strategy with nothing to say, which is the argument in AEO won’t save your content strategy. To know whether any of it’s working, track the citations themselves, which is how I track whether AI is actually citing my content.
Frequently asked questions
AI-citable content is content that AI tools like ChatGPT, Perplexity, Claude and Google AI Overviews can extract and quote, with credit to you, when they answer a question. It rests on four patterns: specific claims verified against a source, inline attribution in the same sentence as each claim, an extractable summary in the first 150 words, and FAQ answers that work without the page around them. Kevin Indig’s 2026 analysis of ChatGPT citations found 44.2% came from the first 30% of a page, so where those elements sit counts as much as whether they exist.
A citation-worthy claim is specific and verifiable, with its source named in the same sentence. Replace vague marketing language like “our platform helps institutions streamline operations” with a sourced claim that gives the metric, method and scope, then trace every figure to a documented source in a source log and cut anything you can’t trace rather than hedging it. The Princeton GEO study found that adding statistics, quotations and citations lifted visibility in AI answers by up to 40%, and Indig found heavily cited text averaged 20.6% entity density against 5% to 8% in typical English.
AI-citable content should put its main answer in the first 150 words and its strongest claims in the first third of the page. Kevin Indig’s 2026 study of ChatGPT citations found 44.2% came from the first 30% of content, 31.1% from the middle and 24.7% from the final third. Question-format headings help too, since cited content was twice as likely to contain a question mark and 78.4% of question-related citations came from headings.
Adding AEO/LLMO requirements to a content workflow took me roughly 15 to 20 minutes extra per blog post once the habits were in place. The requirements are a verified source for every claim, at least one inline attribution per 500 words, an extractable summary in the first 150 words, self-contained FAQ answers, and an extraction test where you read each H2 section in isolation. Writing them into the content brief and editorial checklist makes the process systematic instead of relying on each writer’s judgement.