Product documentation is usually the most factual and structured content a B2B company owns, and the easiest to extract, which is what AI answer engines select for, and it usually sits outside marketing’s remit. AI systems already read it heavily: on GitBook, AI agents made up 51.8% of intentional documentation reads in a week of spring 2026. The fix is an audit of the docs against every claim on the marketing site and a shared review route, with marketing taking nothing over and the procedures, structure and tone left to the team that writes them. Nobody has yet published a head-to-head study of docs against blog citation rates, so treat the “more than your blog” part as a pattern I keep seeing, backed by how the engines behave.
Run five of your buyers’ questions through ChatGPT and Perplexity, then look at which of your own URLs come back. In a lot of B2B SaaS companies the answer is the help centre and the API reference, and the blog nobody has audited since the last rebrand doesn’t show up at all.
That result makes sense once you look at what the two kinds of page contain. Product documentation is written by people whose job is to be correct: a definition, a procedure, a parameter, a limit, a version number. There’s no preamble or positioning, and no paragraph warming up to the point, so it’s the format retrieval systems handle best, produced by a team that has never once thought about AI visibility.
The engines are reading it, too. GitBook’s data team found AI agents accounted for 51.8% of intentional documentation reads across its hosted docs in one week of spring 2026, up from under 10% of its documentation traffic in January 2025, with ChatGPT making up 54% of that agent traffic. GitBook sells documentation software, so it has every reason to find this, but the direction matches what citation trackers see. Bill Widmer logged 13,184 citations across four AI tools for Orbit Media and found ChatGPT “skews towards primary sources”, naming vendors’ pricing and help pages among them.
And the people who own your documentation have no idea it’s doing marketing work.

Why does product documentation match what AI answer engines want?
Product documentation matches what AI answer engines want because the qualities that make a doc good are the same ones that make a passage easy to lift into an answer.
Engines assemble answers from passages, and the page that ranks first for your query is less and less likely to be the one they quote. Ahrefs found that in March 2026 only 37.9% of the URLs cited in Google’s AI Overviews also ranked in the top 10 for the same query, down from about 76% in July 2025, with the rest coming from pages that rank for the related sub-queries Google runs behind the scenes. Those sub-queries are narrow and specific, which is exactly what a doc page answers.
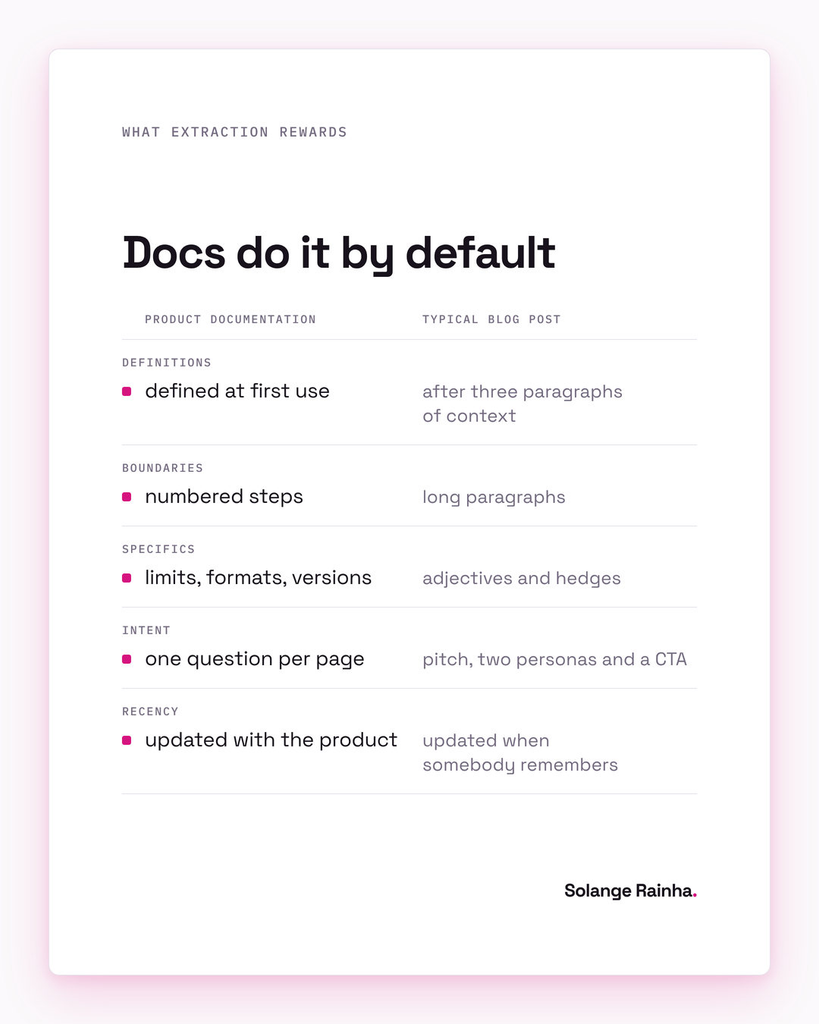
| What extraction rewards | Product documentation | A typical B2B blog post |
|---|---|---|
| Definitions at first use | Standard, because a support article can’t assume the reader knows the term | Often skipped, or arrives after three paragraphs of context |
| Clean boundaries | Procedures as numbered steps | Advice spread across long paragraphs |
| Specifics | Limits, formats, error codes, supported versions | Adjectives, and figures hedged because legal asked |
| One intent per page | One question per page | A question, a positioning pitch, two personas and a CTA |
| Recency | Updated whenever the product changes | Updated when somebody remembers |
The specifics row carries the most weight. In the Princeton GEO study, adding statistics lifted a page’s visibility in generated answers by about 31%, and citing sources by about 28%, while keyword stuffing fell below the unmodified page. Recency counts too: Ahrefs’ analysis of about 17 million citations found AI assistants cited content 25.7% fresher than what ranked in organic results, with Google’s AI Overviews the one exception. Docs get that freshness for free, because they change when the product does.
The extractability mechanics are in my tactical guide to AI-citable content, and every one of them describes documentation by accident.
What goes wrong when documentation sits outside marketing?
The pages most likely to be quoted back to a buyer are the pages nobody in marketing has read.
In most companies docs are owned by support, technical writing or engineering, budgeted separately, published on a different system, with no shared review cycle. That arrangement is fine while documentation is post-purchase reading, and stops being fine when a model pulls a doc page into an answer for an evaluation-stage question and presents it as your company’s position. A few problems follow fast.
Your positioning gets set by whoever wrote the integration guide. There’s no malice in it: a technical writer describing what a feature does today has no reason to think about how it reads next to a homepage claim.
Nobody applies editorial standards to it. The voice, the terminology and the naming of your own features get decided independently, often inconsistently between doc pages, which weakens the entity consistency models use to work out what you are. It’s the problem I wrote about in building editorial standards from zero, applied to a body of content marketing doesn’t know it has.
Then there’s measurement: if your citation tracking only covers the blog, you’re missing where you’re being cited, so put product documentation URLs in the prompt set from the start and report them as their own group, separate from the blog and the guides. That’s part of how I track AI citations, and it counts for more as agents become readers in their own right, which I covered in content for AI agents.
How do you audit product documentation against marketing claims?
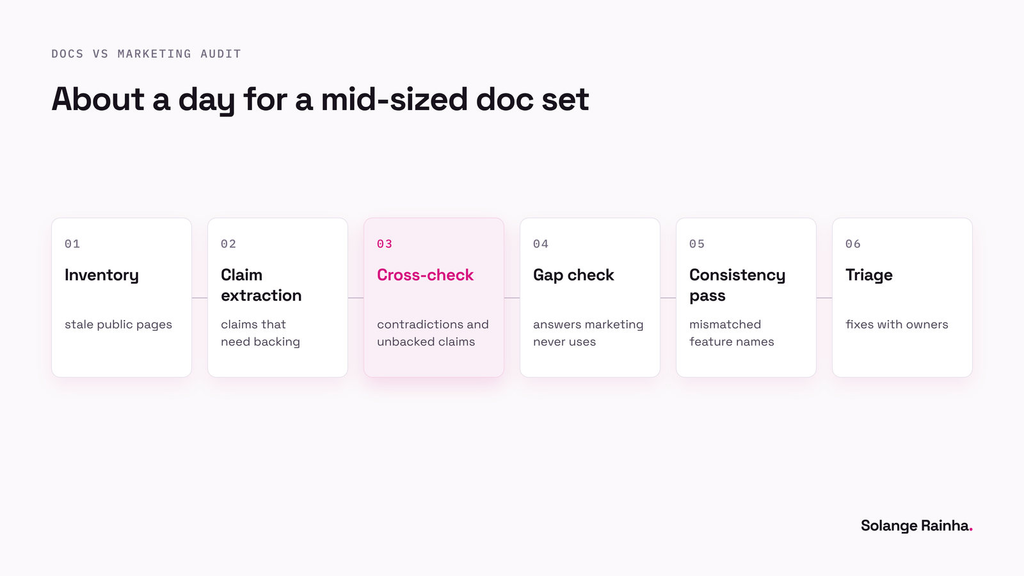
You inventory the public docs, pull every factual claim off the marketing site, and match the two line by line; for a mid-sized doc set it takes about a day.
I ran a version of this while building technical content for CIO and CTO buyers at a B2B SaaS company serving 200+ higher education institutions, where the product documentation was my primary source material, which I’ve described in writing technical content for CIOs. Reading the docs closely against what the site said turned up places where the two didn’t line up: capabilities described more confidently in marketing copy than in the docs, and behaviour documented in ways the positioning hadn’t caught up with. It became part of the source verification process I built there, and I’ve since run it as a standalone audit.
| Step | What you do | What it catches |
|---|---|---|
| 1. Inventory | List every doc URL that’s publicly indexable, with its last-updated date. | Pages nobody knew were public, and stale pages still being crawled. |
| 2. Claim extraction | Pull every factual claim from the marketing site: capabilities, limits, integrations, security posture, pricing logic. | The claims that need backing. |
| 3. Cross-check | Match each marketing claim against the doc page covering the same feature. | Direct contradictions, and claims with no documented basis. |
| 4. Gap check | Note buyer questions the docs answer that marketing never covers. | Free content, already written, needing only a link. |
| 5. Consistency pass | Compare feature names, terminology and versioning across both. | Entity inconsistency, which weakens both sets of pages. |
| 6. Triage | Sort each finding into fix the marketing claim, fix the doc, or leave alone. | The output, with owners attached. |
Step three produces the uncomfortable conversations, and that’s the point of the exercise. A claim on the site with nothing in the product documentation to support it is either an undocumented feature or an overstatement, and finding out which is worth the discomfort. The blog side of the library deserves the same scrutiny, and the checks for that are in the AI readiness audit.
What’s the risk when the site and the docs disagree?
You publish two contradictory sources about your own product and let a model choose between them.
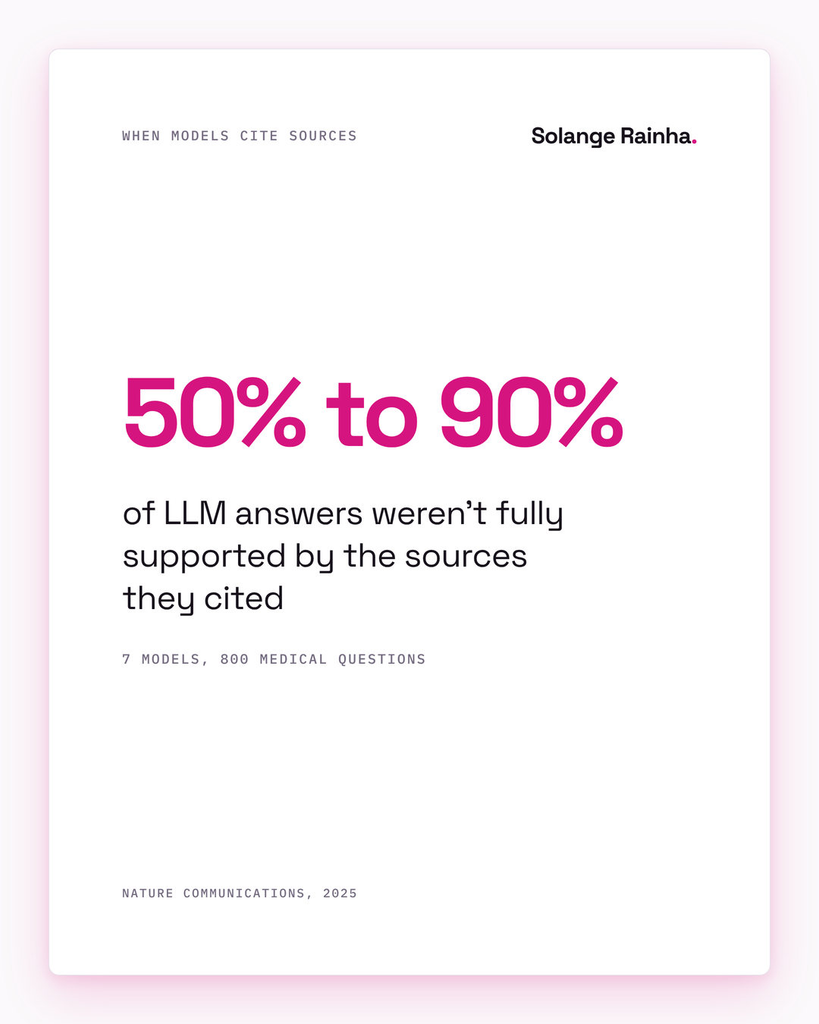
Models aren’t careful readers of their own sources either: a Stanford team publishing in Nature Communications tested seven LLMs on 800 medical questions and found between 50% and 90% of responses weren’t fully supported, and were sometimes contradicted, by the sources they cited. That’s medicine, not B2B software, but the mechanism carries over: give a model two versions of your own truth and there’s no guarantee it picks the one you’d choose.
The commercial risk is worse than the technical one: a buyer at the evaluation stage asks whether your product does X, and the model answers from your documentation, which says X works under three specific conditions your marketing page never mentions. Nobody is lying, and the buyer still gets a more qualified answer than your positioning promised, from your own domain, with no salesperson present to add the context.
There’s also the reverse case, which should worry you more: the product documentation says the capability exists and the marketing site has never mentioned it. That’s a differentiator sitting in a support article, findable by a model and invisible to your own positioning. Buyers go looking for exactly that material during evaluation, which is why integration and security documentation beats a generic architecture chapter in what B2B buyers read instead of whitepapers.
What does a shared ownership model look like?
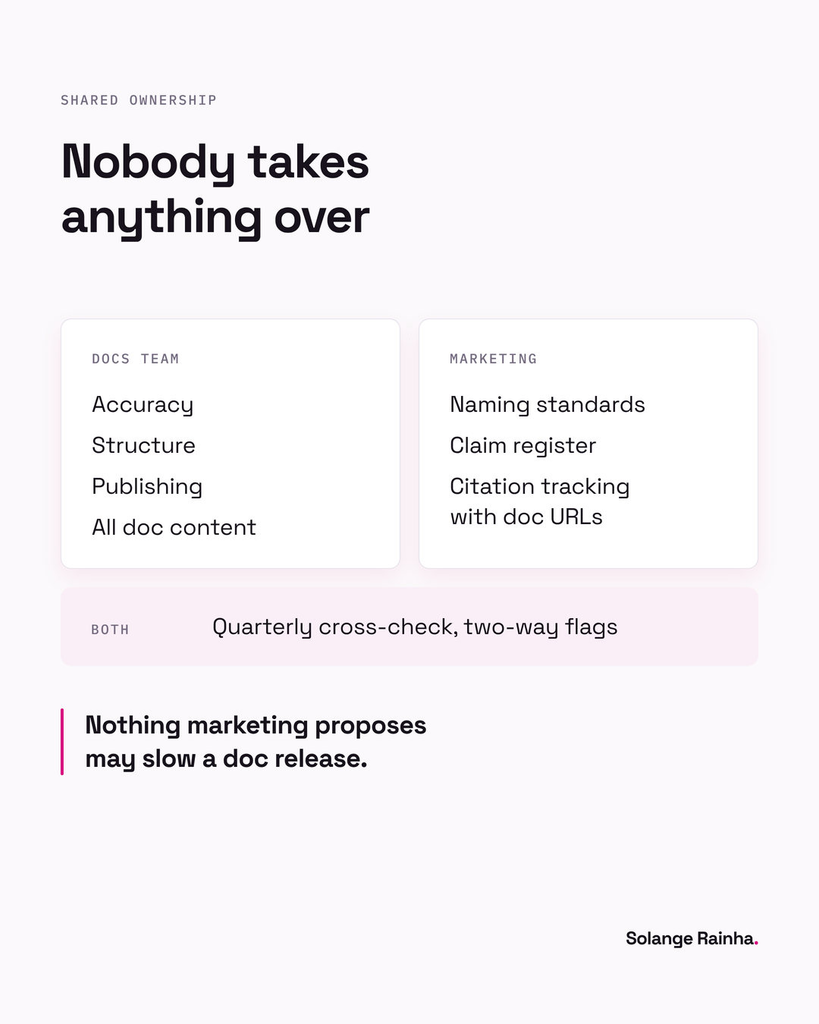
A shared ownership model adds a review route between the two teams and gives nobody anything new to own, because the turf war starts the moment marketing proposes owning the docs.
| Who | Owns | Doesn’t own |
|---|---|---|
| Docs team (support, technical writing, engineering) | Accuracy, structure, publishing, the entire content of the docs. | Positioning language, competitive claims. |
| Marketing | Terminology and feature naming standards, the claim register, the citation tracking that includes doc URLs. | Editing doc content, changing procedures, review gates on doc releases. |
| Both | A quarterly cross-check, and a defined route for flagging contradictions in either direction. | Anything requiring a new approval step. |
Marketing brings evidence, meaning a specific contradiction with two URLs attached, and never a general note about tone. Flags travel both ways, so the docs team can flag a marketing claim they can’t support, which is what turns this from an audit into a working relationship. And nothing marketing proposes may slow down a doc release, because the moment it does, the arrangement is dead and deserves to be.
The systems argument underneath this is the one I made in why a content system beats a bigger content team: a documented shared standard does more than extra headcount or goodwill ever will.
What should marketing leave alone?
Most of it, and being clear about that upfront is what gets you through the door.
Leave the procedures and the technical accuracy alone, since the docs team is better at both than you are. The structure stays too, because it’s already better built for extraction than your blog. Same with the tone: documentation reads flat because flat is correct for someone troubleshooting at 2am, and warming it up makes it worse at its job without helping citation at all.
Also resist the urge to add marketing content to the knowledge base. A product documentation page that opens with a value proposition is a worse doc page and a worse citation candidate, since one intent per page is what makes the format work. The temptation to “optimise” docs is where this initiative usually goes wrong, and the AEO mistakes that waste the investment mostly come from adding structure and language when the substance is what needs fixing. The one technical addition with a case is an llms.txt file for developer docs, since AI coding assistants do fetch curated docs files, as I found when testing llms.txt against the data; for everything else, leave the format alone.
What marketing brings is narrower than it wants to be: consistent naming, accurate claims, awareness of which pages are being cited, and the occasional link from a doc page to the piece that explains why the feature exists. Most companies don’t do any of it yet. If the docs keep turning up in answers, the per-engine differences are in how to optimise content for ChatGPT, Perplexity and AI Overviews.
What doesn’t the evidence show yet?
Nobody has published a head-to-head comparison of citation rates for product documentation against blog content, so the claim in the title rests on a pattern I keep seeing in prompt checks and on how the engines select passages.
The agent-traffic figures come from documentation platforms (GitBook here, and Mintlify, which found AI coding agents made 45.3% of requests to its hosted docs), which sell docs software and measure reads, not citations in answers. Developer-heavy products will see more of this than a product with a thin help centre, and if your docs are stale, the same extraction logic works against you, because a model will happily quote an outdated limit. Run the five-question test on your own buyers’ questions before you take my word for any of it.
Frequently asked questions
Product documentation matches what AI answer engines select: definitions at first use, procedures in numbered steps, specific values in place of adjectives, one intent per page, and updates whenever the product changes. Blog content tends to front-load context, serve several audiences at once and hedge the figures a model would lift. Since Google’s AI Overviews now cite many pages outside the top 10 for a query, a clean doc passage can beat a better-promoted post, though no study has yet compared docs and blog citation rates directly.
Yes, and heavily. GitBook found AI agents made up 51.8% of intentional documentation reads across its hosted docs in a week of spring 2026, up from under 10% of documentation traffic in January 2025, with ChatGPT the largest single agent. GitBook sells documentation software, and the figure measures reads rather than citations in answers, but citation trackers report ChatGPT favouring primary sources such as vendors’ help pages.
No, and proposing it is the fastest way to lose the cooperation you need. A workable split gives the docs team full ownership of accuracy, structure and publishing, gives marketing the terminology standards, the register of public claims and citation tracking that includes doc URLs, and adds a quarterly cross-check plus a two-way route for flagging contradictions. The rule that keeps it alive is that nothing marketing proposes may delay a documentation release.
Inventory every publicly indexable doc URL with its last-updated date, extract every factual claim from the marketing site, then match each claim against the doc page covering the same feature. The cross-check produces three kinds of finding: direct contradictions, marketing claims with no documented basis, and documented capabilities the marketing site never mentions. Finish with a consistency pass on feature names and terminology, then triage each finding into fix the claim, fix the doc, or leave alone, with an owner attached.