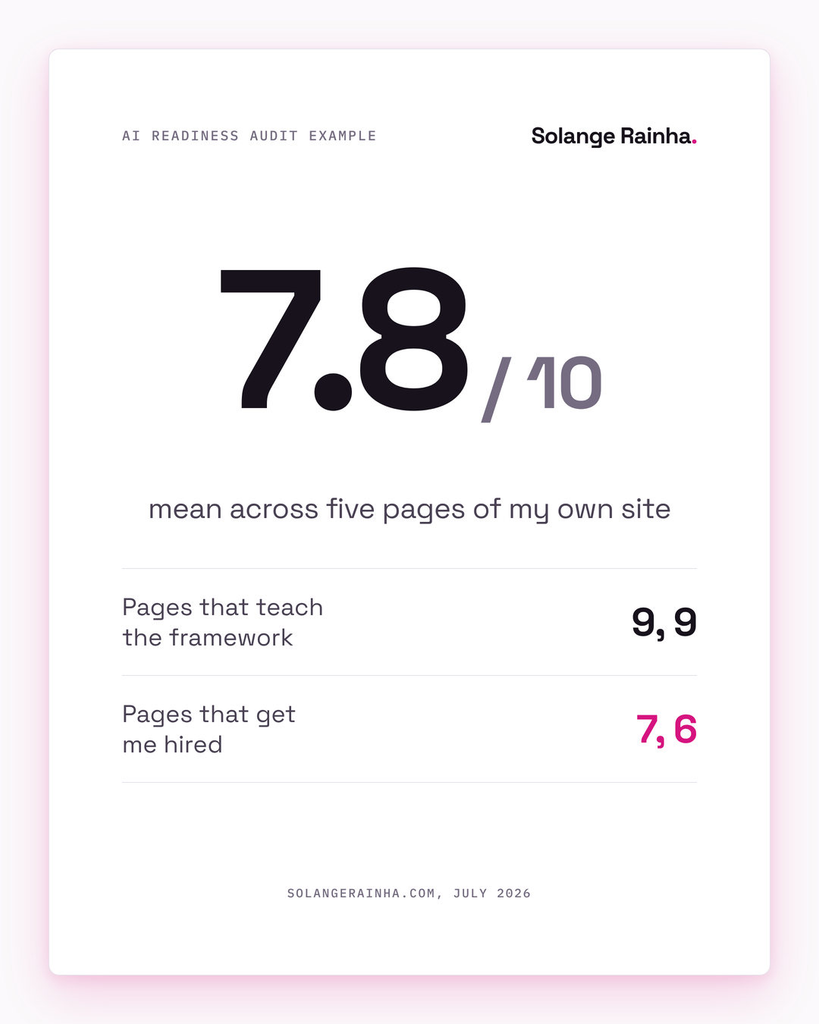
This is an AI readiness audit example run on my own site, published with the failures intact. I scored solangerainha.com against the five-check instrument I publish, and the result was uncomfortable in a way I didn’t predict: my blog and framework pages scored 8 to 9 out of 10, while the CV and portfolio, the pages that get me hired, scored 7 and 6. The mean was 7.8. Most of the lost points came from two checks, unsourced first-party figures and headings written for voice instead of retrieval, and the fix list came to two pages. An audit like this measures whether a page should be citable; whether it is cited needs separate tracking.
Publishing a framework is cheap: anyone can write a scoring rubric, and nobody checks whether the author’s own work would pass it, so I ran my AI Readiness Audit Framework against my own site, scored it the way I’d score a client’s library, and published the scores before fixing anything.
The headline: a mean of 7.8 out of 10 across the audited pages, with two pages in the salvageable band, and both of those are pages a hiring manager lands on. My highest-scoring page teaches the framework, and my portfolio came bottom.
How did I scope this AI readiness audit?
The way the framework prescribes, without inventing a more impressive-sounding method: score the head in full, sample fifteen to twenty pages from the tail, time-box the pass, and fix nothing while scoring.
For this run I scored the head, meaning the pages carrying business value for someone deciding whether to interview me: the homepage, the CV, the portfolio and the flagship framework page. I added one blog article as a tail sample, picking a piece from March 2026 instead of a recent one, on the reasoning that older work shows what my standards looked like before the framework hardened.
The limits belong up front, because an AI readiness audit example that hides its method is worthless. Five pages is a head-and-sample pass, not a census of the library. And this audit measures whether a page should be citable; whether it is cited needs its own scoreboard, which I’ve written about in AI citation tracking and measuring AI visibility without analytics. At OpinionX I run that tracking across 20 buyer prompts in five AI engines, and the first baseline had the brand named in 38% of answers and cited as a source in 37%, which is a separate exercise entirely.
What did the pages score?
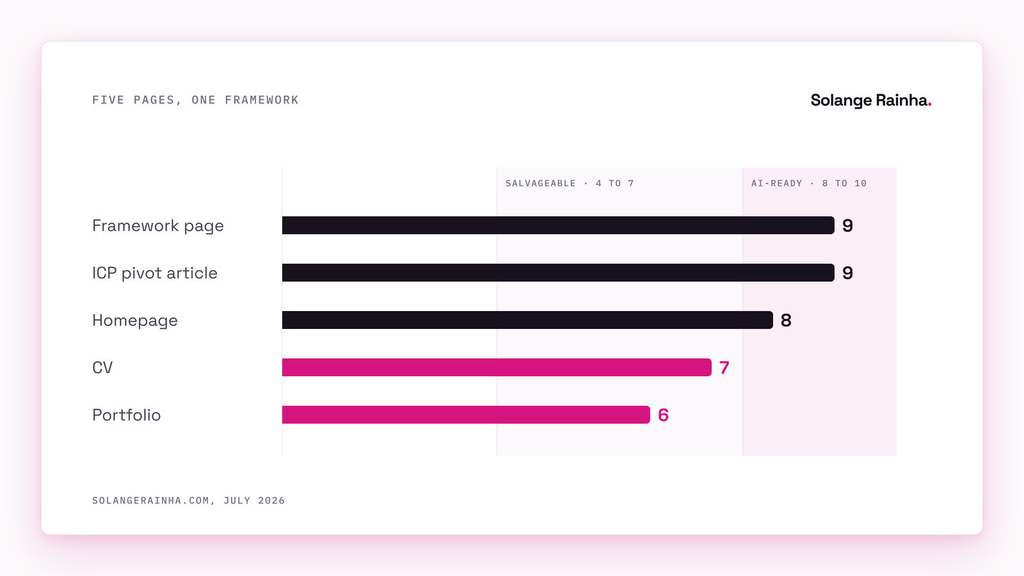
Three cleared the AI-ready band and two landed in salvageable, from five checks scored zero to two each, out of ten. Checks 2 and 4 grade substance; 1, 3 and 5 grade structure.
| Page | 1. Front-loaded answer | 2. Citable substance | 3. Standalone sections | 4. Attributed evidence | 5. Retrievable structure | Total | Bucket |
|---|---|---|---|---|---|---|---|
| AI Readiness Audit Framework | 2 | 2 | 2 | 2 | 1 | 9 | AI-ready |
| ICP pivot article (blog) | 2 | 2 | 2 | 1 | 2 | 9 | AI-ready |
| Homepage | 2 | 2 | 2 | 1 | 1 | 8 | AI-ready |
| CV | 1 | 2 | 2 | 1 | 1 | 7 | Salvageable |
| Portfolio | 1 | 1 | 2 | 1 | 1 | 6 | Salvageable |
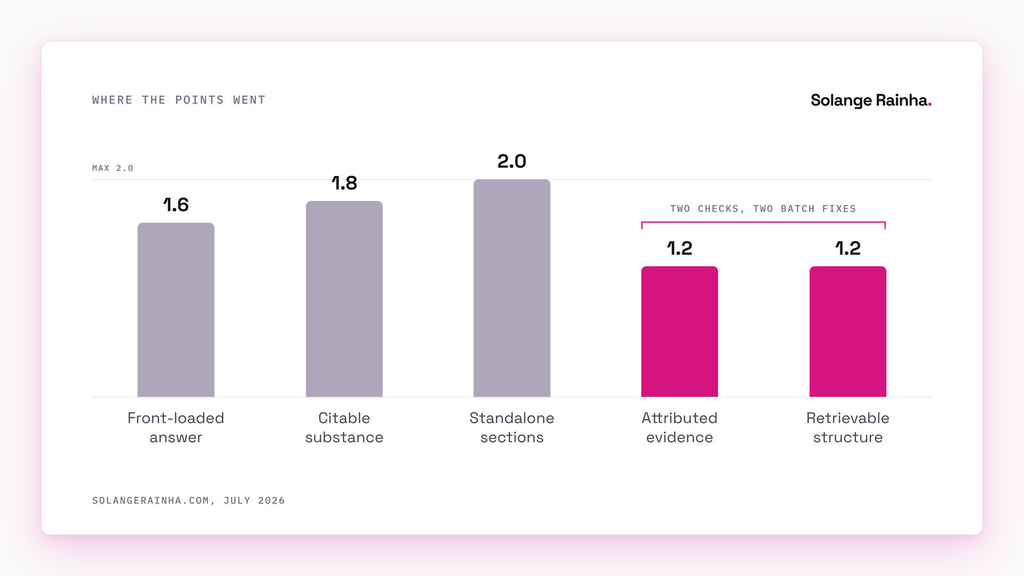
| Mean | 1.6 | 1.8 | 2.0 | 1.2 | 1.2 | 7.8 |
Nothing scored AI-invisible, which is the one result I’d have been embarrassed by, and the only part of this I’d call reassuring.
Why did the hiring pages score lowest?
Because I built them before the method existed, as design objects for a human scanning quickly. I’d assumed the blog would be my weak spot, since it’s the biggest part of the site and the hardest to keep consistent, and the opposite turned out to be true.
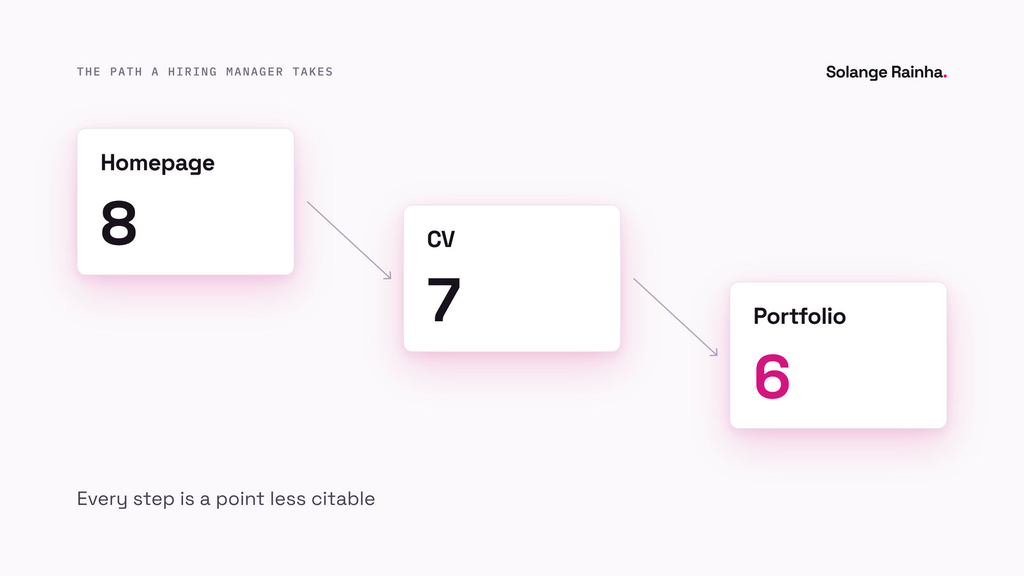
Content pages outperformed conversion pages, and the path someone evaluating me typically takes, from the homepage to the CV to the portfolio, runs straight downhill in citability. It’s also the path most interviewers never get to the end of, which makes the inbound reader, the one who finds the site before any process starts, the audience these pages most need to serve.
The reason is uncomfortable and, in hindsight, obvious: the blog and the framework pages came after the AEO methodology, so they inherited it. Nobody applies an extraction framework to their own CV, so I optimised the pages that teach the framework and left the ones that get me hired alone.
Where did the points go missing?
Two checks account for almost all the lost marks, and the pattern is consistent enough to fix in batches instead of page by page.
Attributed evidence, check 4, averaged 1.2 out of 2. It’s my joint-worst check, which is an unflattering result given that the orphan statistic sits second on my own list of the five failures that tank a page score. My site is full of orphan statistics, and they’re all mine: “48% marketing-sourced pipeline” appears on the homepage and the CV with no link, methodology or date, and the same goes for “+217% reach”, “35% of website traffic” and “+28% YoY organic”. Sourced figures earn their weight with models: in the original GEO study by Aggarwal and colleagues, adding statistics lifted a source’s visibility in generative answers by around 31% and citing sources by around 28%. Google’s own guide to helpful content asks the same question of people, whether the content earns trust through “clear sourcing”.
The irony is that the methodology exists: I wrote a full article explaining how the 48% was calculated, including what it does and doesn’t mean. I just never linked the figure to the explanation.
Retrievable structure, check 5, also averaged 1.2, and this one is a trade-off, not an oversight. My headings are written in a voice: “Not everything. Just the highlights.” “Where I’ve shipped.” “The toolbox.” “Three systems, built in production.” They’re distinctive and sound like a person, which is part of why the site doesn’t read like a template. For retrieval they’re close to useless, because they match nothing anyone would type and tell a model nothing about what sits underneath them. Google’s guide asks whether the main heading gives “a descriptive, helpful summary of the content”, and mine mostly don’t. Hoa Loranger at Nielsen Norman Group put the usability case more bluntly:
“Don’t succumb to cute or faddish vocabulary.”
The blog article scored 2 on this check precisely because every heading there is a question: “How do you triage an entire content library during a pivot?”
What went on the fix list?
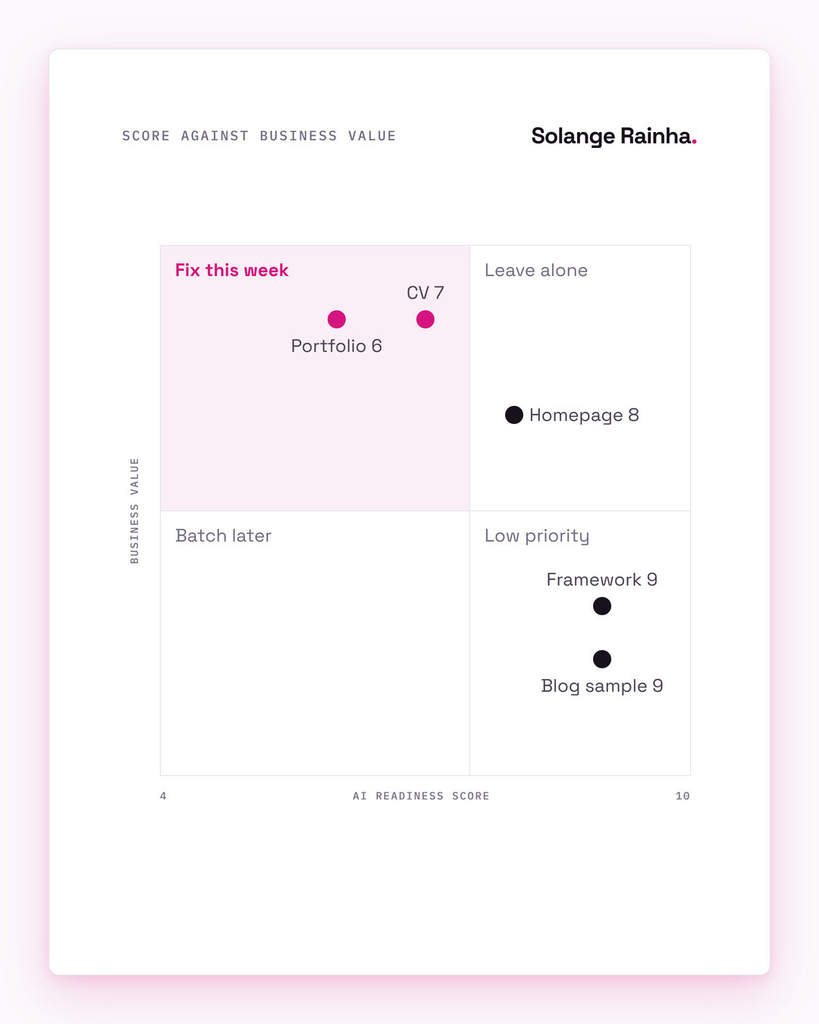
Two pages, the CV and the portfolio, because the framework says to cross each score with business value and spend the week in the salvageable-and-valuable quadrant. Both sit at 6 to 7 with the highest business value on the site, so they’re exactly the pages to prioritise, with three fixes each, batched by failure type.
Sourcing the first-party figures comes first. Every headline metric gets a link to its methodology where one exists, and a date and scope where it doesn’t: the 48% links to the methodology article, and the others get “measured over five months, LinkedIn, Instagram and Facebook combined” style qualifiers inline.
Then the front-loaded answer on the portfolio. “Not everything. Just the highlights.” tells a reader and a model nothing about the work. It stays as the visual headline, with a 40-to-75-word answer block immediately underneath saying what the work is, who it was for and what it produced. That’s the same discipline I argue for in writing openings that survive the scroll, which I apparently applied to my articles and not to my own portfolio. The top of the page is where it counts most for AI, too: Kevin Indig’s analysis of ChatGPT citations found 44.2% came from the first 30% of a page.
Last, question-format subheadings where they don’t cost the voice: the section labels on the CV can carry a question underneath them, so the personality stays in the display heading and retrieval gets something to match.
The blog gets one batch pass instead of a rewrite, because the tail sample scored 9, so there’s no crisis, but the one check it dropped was attributed evidence for want of a table: the triage in that article is four categories described in prose, the “comparison trapped in prose” failure from my own list. The batch fix is to find the comparisons across the library and build the tables.
| Page | Score | Business value | Decision |
|---|---|---|---|
| CV | 7 | Highest: read before any interview | Fix this week |
| Portfolio | 6 | Highest: the evidence behind the CV | Fix this week |
| Blog library | 9 (sample) | Medium: inbound and AI visibility | One batch pass for tables |
| Homepage | 8 | High, but reached by name | Leave |
| Framework page | 9 | Medium | Leave |
What did I leave alone, and why?
Everything that was already good enough, because an audit that ends with “fix everything” is one nobody acts on.
- The homepage stays at 8. It’s already in the AI-ready band, and the two points it’s missing sit in the same voice trade-off as everything else. Pushing it to 10 would mean flattening the headings that make it feel like me, for a marginal gain on a page people mostly reach by name.
- The framework page keeps its heading style too. It scored 9 and lost its point on check 5 for the same reason, and I’ll take a 9 with a voice over a 10 that reads like documentation.
- I’m not auditing the long tail page by page. The sample told me what I needed: the blog inherited the methodology and behaves, and enumerating 50+ more articles would buy a slow confirmation of that, which is a mistake I’ve made before and named in the framework.
- The orphan-stat fix doesn’t extend to every figure on the site. Where a figure is decorative, adding a source line costs more clarity than it buys credibility.
What did auditing my own site teach me about the framework?
That two parts of my own instrument need tightening. Running it on my own work was the first time the framework met pages I couldn’t rationalise.
The business-value axis needs to be explicit about conversion pages. The framework says to cross the score with traffic, buyer intent and strategic relevance. On a personal site, the highest-intent page isn’t the highest-traffic page, and I nearly skipped auditing the CV because it felt like a document more than content.
Check 5 needs a voice caveat: as written, it treats non-question headings as a straightforward deduction, when in practice you’re trading distinctiveness against extractability. A framework that scores you down for having a voice should say plainly that taking the deduction is sometimes correct. I’d rather lose a point on purpose than pretend the tension doesn’t exist; Loranger’s advice holds for usability, and for a personal site I’m choosing to break it in display headings. The deeper argument for why substance leads and structure follows is in the AEO/LLMO framework, and this is a case where the structure layer should yield.
The substance checks held up. Checks 2 and 4 are where the framework claims the citation lives, and every page scored 2 on citable substance except the portfolio, which is a catalogue more than an argument. That’s the framework working as designed: it caught the one page where I have specifics but no position.
Why publish the failures?
Because the alternative is a framework nobody can verify, and this whole site is an argument that verifiable beats impressive.
A hiring manager reading my AI readiness audit framework has no way to know whether it survives contact with working pages. Publishing an AI readiness audit example run on my own site, with a 6 out of 10 on the portfolio I built and a criticism of the instrument itself, is harder to fake than a case study about a company I worked at. It also shows what the framework is for: a short fix list you’ll act on this week. It’s the same case I made for this blog in personal branding versus the work: show the receipts.
If you want to check my scoring, every page is live and the instrument is published. Run it yourself and see whether you get the same scores. That verifiability is the same principle behind treating content as a system rather than a set of one-off wins.
Scores reflect a pass run in late July 2026 against the published five-check instrument. Pages change, so the live pages may already differ from the scores above.
Frequently asked questions
An AI readiness audit example looks like a scoring table and a short fix list. You read each page against five checks scored zero to two, for a total out of ten, then sorted into AI-ready (8 to 10), salvageable (4 to 7) or AI-invisible (0 to 3). You cross the scores with business value, and only the salvageable-and-valuable pages earn the week’s work. On my own site that produced a mean of 7.8 and a fix list of two pages.
Because they were built earlier, as design objects for human recruiters, before the AEO methodology existed. Conversion pages tend to feel exempt from content rules, so few people point an extraction framework at their own CV. They lost points on unsourced first-party metrics and stylish non-question headings, both cheap to fix without redesigning anything.
Orphan statistics, with an average of 1.2 out of 2 on attributed evidence. Figures like “48% marketing-sourced pipeline” appeared with no link, date or scope, even where a full methodology article existed elsewhere on the site. The fix is linking each figure to its explanation, and it’s worth doing: in the GEO study, adding statistics and citing sources each lifted visibility in generative answers by around 30%.
No. The framework deliberately ends with a short list, because an audit that recommends fixing everything is one nobody acts on. On this run, two pages went on the fix list, three were left alone with the reasoning written down, and the long tail was sampled instead of enumerated.