An AI readiness audit scores each page in an existing content library on whether an AI system like ChatGPT, Claude or Perplexity could pull a clean answer from it and credit you for it. I score every page against five checks (front-loaded answer, citable substance, standalone sections, attributed evidence, retrievable structure), 0 to 2 each, then sort pages into fix, rewrite or leave, and fix the salvageable pages the business needs first. I check substance before structure, because a well-formatted page that says nothing still won’t get cited. Sampling the long tail keeps the audit to about a week. What it can’t tell you is whether a page is actually being cited; that needs separate tracking.
An AI readiness audit is a scored, page-by-page check of whether an AI model can lift and cite your existing content, fast enough to get through a whole library without becoming a quarter-long project. The output is a prioritised list: what to fix, what to kill, what to leave alone. You need one because you’ve inherited a library of two hundred pages, maybe four hundred, built over years by people who’ve since left and optimised for a version of search that’s shrinking, and someone has read a LinkedIn post about AI search and wants to know if it’s “AI-ready”. Nobody knows, because nobody has looked at it that way.
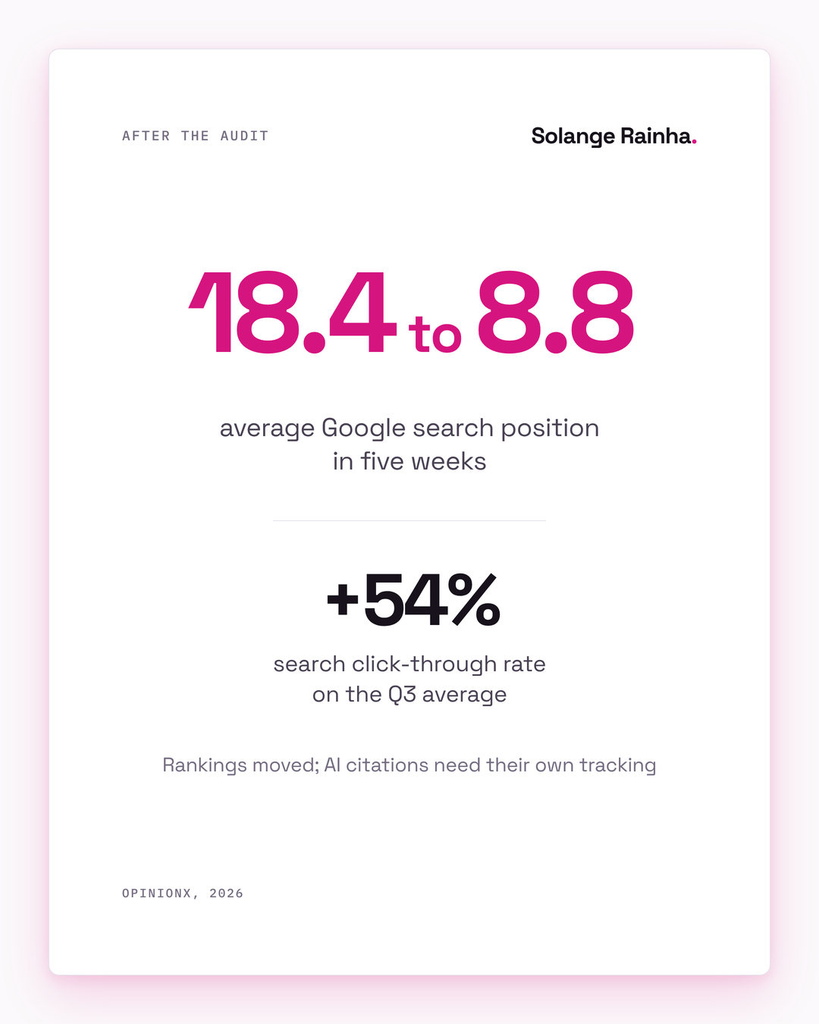
I’ve run this on libraries I built myself and on ones I walked into cold, most recently at OpinionX, where I audited and updated the whole blog library for AEO and LLMO and average Google search position moved from 18.4 to 8.8 in five weeks. The version below survived contact with all of them.
Discovery is moving off the blue link, which is what makes this urgent: in SparkToro’s analysis of US Google searches in early 2026, 68.01% ended without a click, and G2 found in April 2026 that 51% of B2B software buyers now start their research with an AI chatbot, up from 29% the year before. A library nobody can cite is slowly dropping out of where buyers look, whatever its traffic graph says.
What is an AI readiness audit, and why run one?
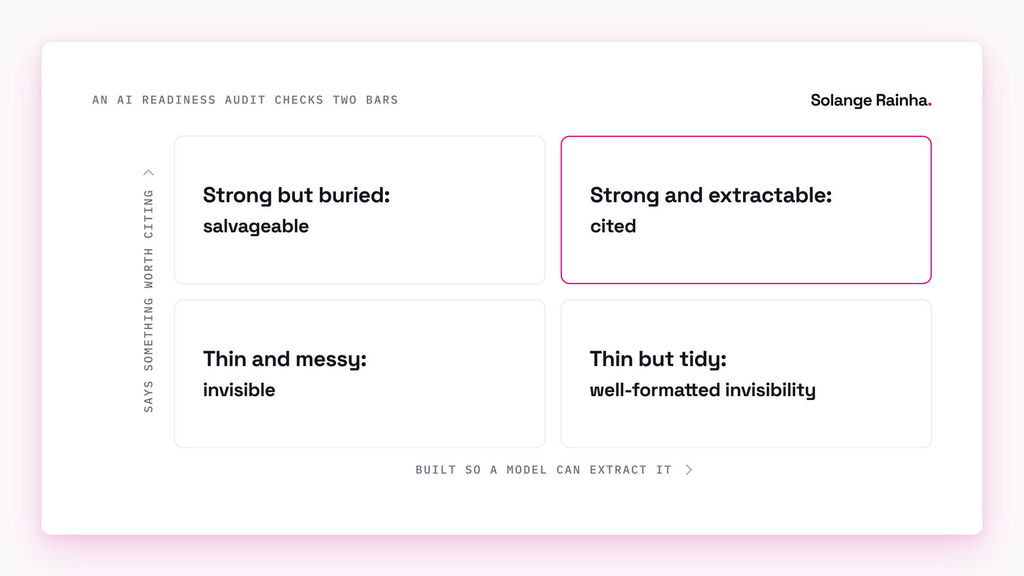
An AI readiness audit asks two questions of every page: whether it says something worth citing, and whether it’s built so a machine can extract that without reading the whole page. Those are separate problems, and most teams only audit the second: they run a tool that checks for schema, FAQ blocks and heading format, get a green score and assume the work is done. I went deep on why that’s backwards in the AEO implementation mistakes playbook, but the short version is that a thin page with a green audit still won’t get cited.
So the audit grades both: a page that makes a specific, attributed claim but buries it under three paragraphs of throat-clearing scores badly on extraction, while a page with perfect structure that repeats what ten other pages already say scores badly on substance. What you want clears both bars, and the audit tells you how many of those you have.
The volume problem predates AI: Forrester has reported that 60% to 70% of the content B2B marketing organisations produce goes unused. The audit doubles as a reason to confront that pile, because a lot of what you find won’t be worth optimising for anything, AI included.
What are the five checks in an AI readiness audit?
Front-loaded answer, citable substance, standalone sections, attributed evidence and retrievable structure, each scored 0, 1 or 2 for a page total out of 10. They come from my AEO/LLMO content optimisation framework, reordered so substance comes before structure, because that’s the order the research supports and the one teams get wrong. The interactive scorer lives on the AI readiness audit framework page; here’s the rubric in brief:
| Check | Scores 0 when | Scores 2 when |
|---|---|---|
| 1. Front-loaded answer | The question is answered halfway down, or never directly | The first 40 to 75 words after the heading answer it, with the caveat right behind |
| 2. Citable substance | Every claim is one a competitor’s page also makes | There’s an original position, attributed data or a named source only this page has |
| 3. Standalone sections | Sections only make sense after reading the ones above | Each section answers one question and survives being lifted out alone |
| 4. Attributed evidence | Figures have no source; comparisons sit in prose | Every figure links to its source; comparisons are tables |
| 5. Retrievable structure | Vague label headings, buried definitions, a JavaScript-rendered body | Question headings, terms defined at first use, clean pre-rendered HTML |
A 1 sits in between: an answer that exists but is wrapped in setup, some specifics among a lot of consensus, mixed sourcing.
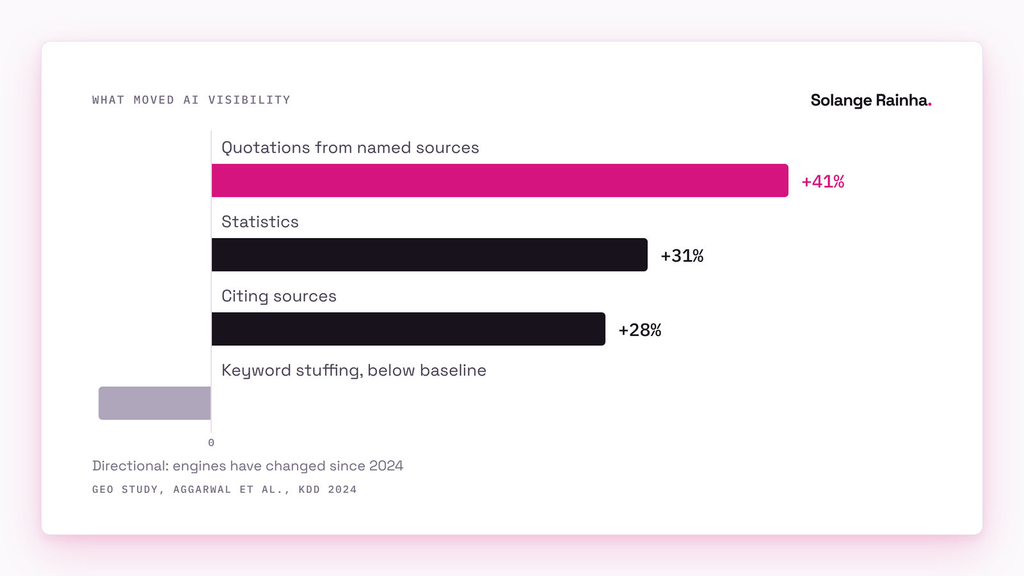
Citable substance does the heaviest lifting, and it’s the check a structural tool can’t see. The Princeton GEO study (Aggarwal et al., presented at ACM KDD 2024, tested across 10,000 queries) found the methods that moved visibility in generative answers were substance-side: quotations from named sources lifted it by about 41%, adding statistics by about 31%, and citing sources by about 28%, while keyword stuffing came in below the baseline. Search Engine Land’s write-up of the study adds that citing sources lifted visibility 115.1% for sites ranked fifth. Treat the magnitudes as directional, because the engines have changed since 2024, but the ordering has held on every library I’ve scored.
How do you score a page in two minutes?
Read the first screen, skim the headings and look for one sourced figure, because that’s where most of the signal lives. In Kevin Indig’s analysis of ChatGPT citations, covering 1.2 million answers and 18,012 citations, 44.2% of cited passages came from the first 30% of a page, so a weak opening wastes the part of the page models cite most.
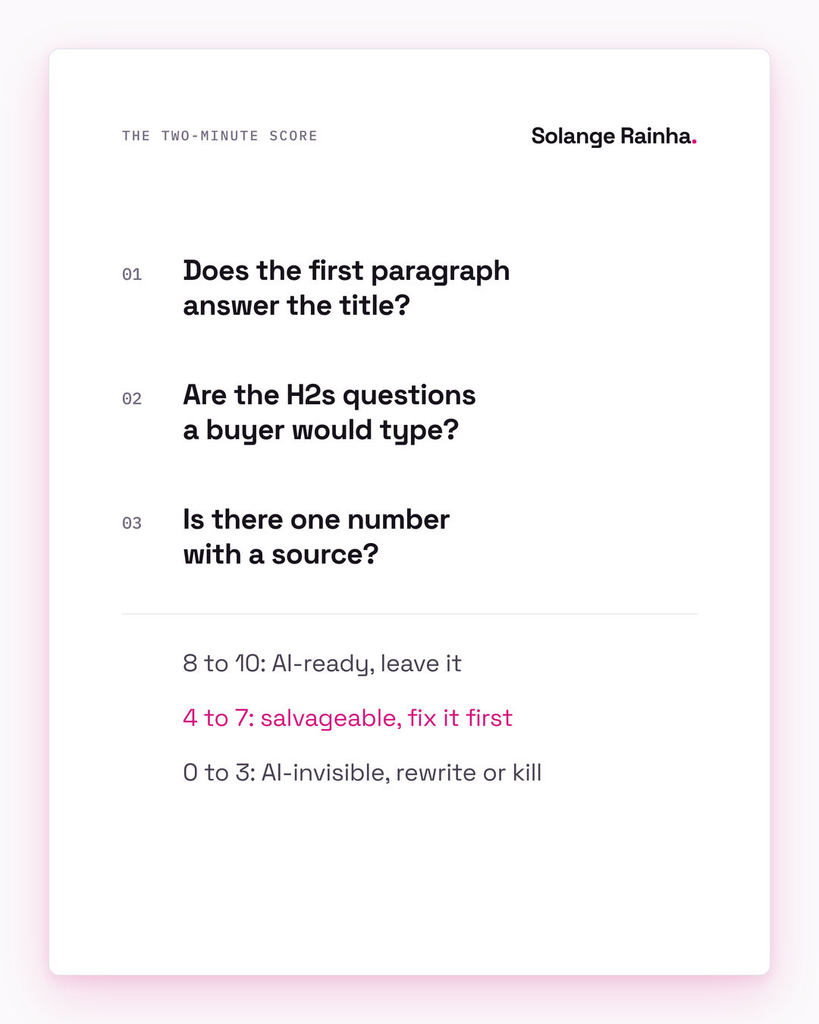
Start with the first paragraph: does it answer the question the title implies, or just warm up? Then scan the H2s and ask whether they’re questions a buyer would type or label nouns like “Overview” and “Benefits”. The last read is for one figure with a source attached. Those three reads cover checks one, five and four in about ninety seconds; substance and standalone sections take another thirty seconds of judgement. Write the score down and move on, and resist fixing anything while you score, because auditing and fixing are different jobs and mixing them is the fastest way to turn a one-week audit into a two-month one.
Each scored page lands in one of three buckets:
| Score | Bucket | What to do |
|---|---|---|
| 8 to 10 | AI-ready | Leave it, and note it as a model for the rest of the library |
| 4 to 7 | Salvageable | This is where the effort goes: the substance is mostly there and the fixes are mechanical |
| 0 to 3 | AI-invisible | Rewrite from scratch or kill it, because polishing a page that says nothing won’t get it cited |
The salvageable bucket is the whole game: a page scoring 6 usually has the substance and needs its answer pulled to the top and its evidence sourced, an hour of work that can take it to a 9, while a 2 needs rebuilding or removing, which makes it a new-content decision, and the audit’s job ends at flagging it.
What should you fix first after an AI readiness audit?
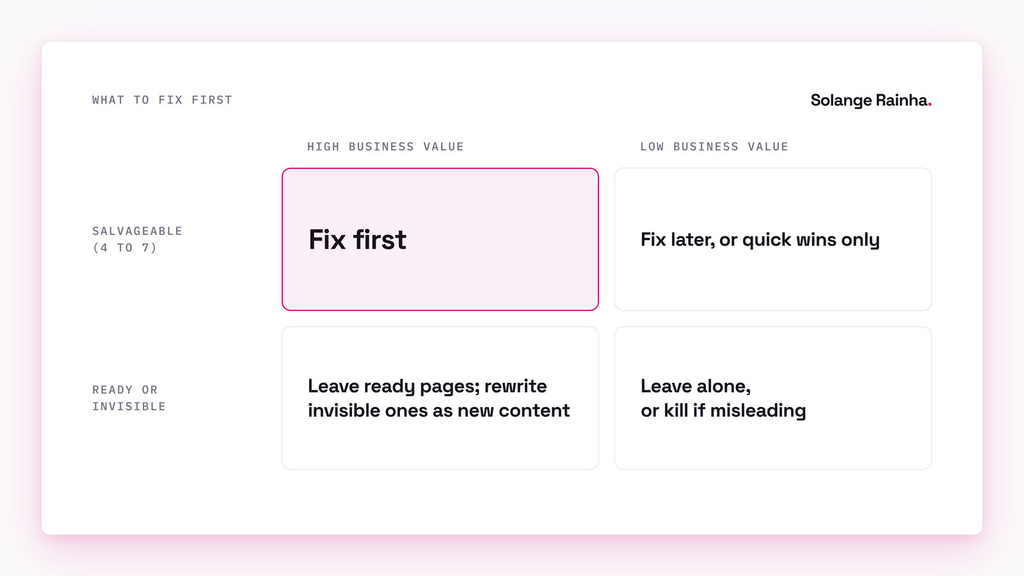
The salvageable pages that already get traffic or map to a buying decision, in that order, and almost nothing else for now. The audit will hand you a list far longer than you can act on, so the prioritisation call is what keeps the project from collapsing. I score the fix list on two axes: how close the page is to AI-ready, and what it’s worth to the business (traffic, buyer intent or strategic relevance to what you sell now).
| High business value | Low business value | |
|---|---|---|
| Salvageable (4 to 7) | Fix first: the best return on effort in the library | Fix later, or only if it’s a quick win |
| AI-ready (8 to 10) or AI-invisible (0 to 3) | Leave the AI-ready ones; schedule a rewrite for the invisible ones as new content | Leave alone, or kill if it’s misleading |
It’s the same logic I use for deciding what to make in the first place, written up as a content prioritisation framework. The audit version is simpler because the content exists, so effort is mostly known and the only question is impact: a high-traffic page sitting at a 5 is the best use of your time, because the traffic proves it has authority worth making citable.
The trap is the inverse: a stakeholder’s favourite page that scores well and nobody needs, or a pristine pillar piece on a topic you’ve since dropped. Score it and note it, then leave it. Effort spent making an irrelevant page AI-ready is effort stolen from a page that could earn citations on something you sell.
Which failures show up most often?
The same handful account for most low scores, and once you’ve seen them you can spot them at a glance.
The buried answer. The page knows the answer and makes you wait, with a 250-word introduction about “the changing world of X” between the heading and the first useful sentence. With 44.2% of ChatGPT’s citations coming from the first 30% of a page, the answer in paragraph four is easy for a model to miss. The fix is brutal and fast: cut the introduction, promote the answer.
The orphan statistic is next: a page claims “73% of buyers do X” with no link, study or year. A human skims past it, and a model has no reason to cite an unverifiable figure when other pages attribute the same one.
Then there are sections that can’t stand alone: one that opens with “as mentioned above”, or relies on a definition three screens earlier, can’t be lifted cleanly. Make every section restate just enough to work alone, which also helps skim-readers. Definitions earn their place twice over: Indig found cited passages were nearly twice as likely to contain clear definitions.
The comparison trapped in prose. Three approaches compared across four dimensions in flowing paragraphs read fine and hand a model nothing structured to extract. Where a page buries a comparison in sentences, building the table is often the single most useful edit on it.
And then there’s the page that says nothing, which no structural fix saves: it’s well written and on topic, and it contains not one claim, figure or position a model couldn’t assemble from the rest of the open web. It’s the page to question instead of optimise, and it’s why substance is check two.
How do you scope an AI readiness audit so it doesn’t eat six months?
Sample the long tail, time-box the scoring and batch the fixes. Audit a four-hundred-page library page by page at full depth and the project never ships, so nothing in it earns a citation.
Score every page that gets traffic or maps to a current buying decision, which is usually a fraction of the library, and score a representative sample of fifteen or twenty pages from the long tail. The failures cluster, so the sample tells you what the rest looks like without opening all of it. I leaned hard on this kind of triage when I rebuilt a content function in 90 days, where there was no time to treat every page as precious.
Give the scoring pass a fixed window of a day or two and accept that some scores will be rough; a rough score on every important page beats a perfect score on the first forty and nothing after. Then batch the fixes by failure type, with one session for promoting buried answers across twenty pages, another for sourcing orphan stats and a third for building tables. Batching is faster than fixing each page end to end, and far less mind-numbing when you’re staring down a list this long.
Done this way, the audit is a week of work for a library that would take a quarter to do exhaustively, and the week gets you most of the value. It’s the operational discipline that lets a one-person content function run a strategic framework, which is the whole argument behind treating content as a system rather than a team.
What would I do differently?
I’d sample from the start: the first time I ran an audit like this, I scored everything and spent two days on a long tail when I should have been fixing the ten pages worth fixing. The long-tail scores told me nothing the sample wouldn’t have; full enumeration feels more rigorous, and on a long tail it mostly buys a slow confirmation of what the sample already said.
I’d also be clearer, earlier, about the measurement gap: the audit scores how citable a page should be, and it doesn’t tell you whether the page is being cited. The two drift apart because citation is noisy: in SparkToro and Gumshoe’s 2026 study, AI tools returned the same list of brands fewer than 1 in 100 times across 2,961 runs of the same prompts. A page that scores 9 can still underperform on a given engine for reasons the audit can’t see, and engines differ in what they retrieve, which I covered in optimising content for ChatGPT, Perplexity and AI Overviews. Proving you’re cited needs separate tracking, which I wrote up in measuring AI visibility without analytics and the content marketing metrics worth reporting.
And I’d push back harder on the instinct to optimise the whole library, which usually comes from anxiety more than strategy. Rand Fishkin put the broader version bluntly in a SparkToro post covered by Search Engine Land: “Traffic is a vanity metric.” Chasing AI readiness across every page is a vanity goal of its own, when the job is getting the pages that count cited and stopping there. An audit that ends with “fix these eight pages” is more useful than one that ends with “fix everything”. When I ran the same audit on my own site, published with the failures left in as an AI readiness audit example, the pages that get me hired scored lower than the blog, which is exactly the kind of finding a short fix list acts on.
The AEO foundations behind all this, and why substance has to lead, are in AEO won’t save your content strategy. The audit is how you find out where your library stands against them before you spend an hour optimising the wrong page.
Frequently asked questions
An AI readiness audit is a page-by-page assessment of how well an existing content library can be extracted and cited by AI systems such as ChatGPT, Claude, Perplexity and Google’s AI features. It scores each page against five checks (front-loaded answer, citable substance, standalone sections, attributed evidence, retrievable structure) on two underlying questions: does the page say something worth citing, and can a model extract it? The output is a prioritised list of what to fix, rewrite or leave alone.
About a week for a typical B2B library. Score every high-traffic or high-intent page in full, sample fifteen to twenty pages from the long tail because failures cluster, and time-box the scoring pass to a day or two. Then fix in batches by failure type (promoting buried answers, sourcing orphan stats, building tables) instead of fixing each page end to end.
A traditional SEO content audit checks keyword targeting, traffic, backlinks and technical health, all aimed at ranking and click-through. The AI version checks whether content can be cited when there’s no click, so it grades front-loaded answers, citable substance, standalone sections and attributed evidence. The two overlap on structure, and they differ on the goal: SEO optimises for the click, AI readiness for being the cited answer.
Yes, and it’s the most common false positive. A page can have perfect schema, question headings and an FAQ block, score green on any automated tool, and never get cited because it says nothing a model can’t get from ten other pages. Substance (an original position, attributed data or a named source) is what earns the citation, which is why the audit grades substance first and treats structure as the delivery layer.