A content repurposing strategy only works if the derivative list is written at brief stage, before the source piece is outlined. I plan up to twelve assets off one substantial, research-led idea, sequence them across channels over the following months, and repurpose the research, never the finished sentences. The derivatives go into social, email, sales enablement and slides, and none of them becomes a second blog post, because one canonical page earns more in search and AI citation than several thin ones competing for the same query. The method assumes there’s material worth multiplying; applied to a thin post, it produces twelve thin assets.
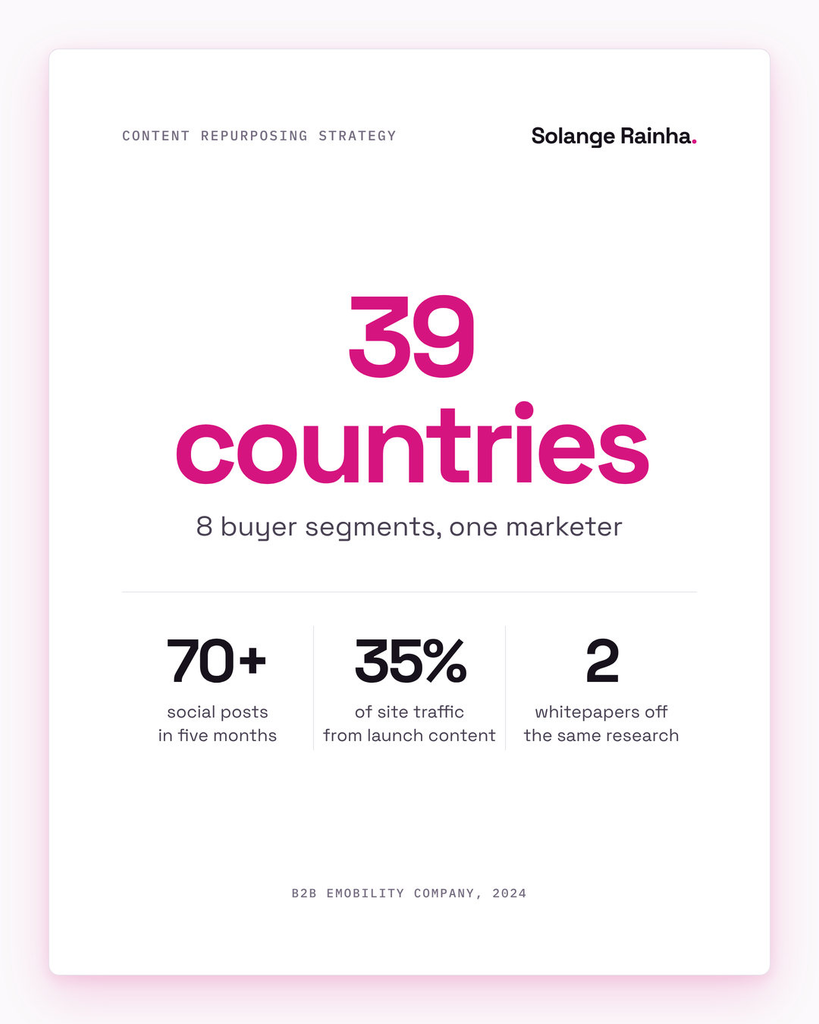
I plan around twelve assets off every substantial idea and decide all twelve before I outline the source piece. At a B2B eMobility company in 2024, that’s how one person covered eight buyer segments across 39 countries: 12+ articles, 15+ web pages, two whitepapers and a case study, plus 70+ social posts in five months, all pulled from the same research rather than researched separately. A content repurposing strategy has to live in the brief, because when the derivatives get written off the finished article they read like a copied introduction, which is what most of them are.
Atomisation, the industry’s term for this, means breaking one source asset into smaller pieces built for each channel. My version adds one constraint the standard version doesn’t: I repurpose the research, never the text.
What does this content repurposing strategy assume?
This content repurposing strategy assumes a lean function, usually one person, in B2B with a considered purchase, and material worth multiplying: original data, a position of your own, named sources, evidence somebody had to go and gather. Applied to a thin post, the multiplier faithfully produces twelve thin assets. It also assumes you own the calendar, because when an editor hands you a list of titles, the derivative planning comes too late to change the source piece, and half the value goes with it.
There’s one shortcut I won’t take: I could point a model at any published article of mine and have it generate all twelve derivatives in about twenty minutes. I don’t, because derivatives generated from finished prose inherit the prose: they arrive as compressed paragraphs with the transitions removed, and the LinkedIn version of an article opening is the most recognisable format failure on that platform. AI does draft derivatives for me, from the research and with the target format’s constraints stated, which is the split I set out in delegating to AI as a solo marketer.
Why does a content repurposing strategy beat publishing more?
It beats publishing more because the expensive part of a piece is the research, the interviews and the argument, which happen once, while everything downstream is an editing job against material that’s already been checked. The pressure to publish more is in the survey data: in the Content Marketing Institute’s 2026 B2B research, a survey of 1,015 B2B marketers fielded with MarketingProfs between June and August 2025, 39% put resource constraints among their top three challenges, and 28% named producing enough quality content. Human resources came last on the 2026 investment list at 9%, behind AI tools at 45%, so the same small team feeds more channels with more tooling and no more people.
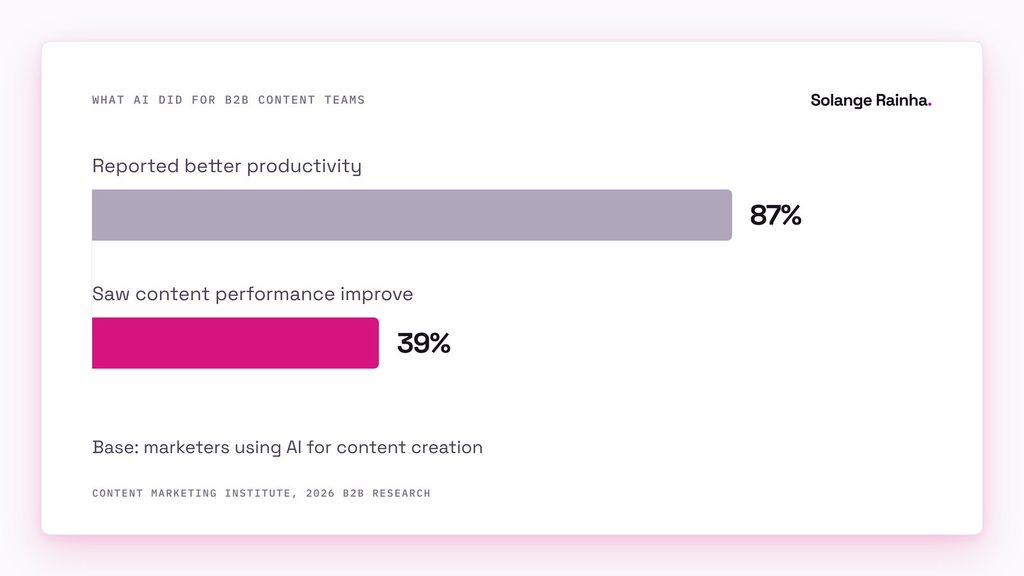
AI hasn’t closed that gap: among marketers using AI for content creation, the same research found 87% reported better productivity, while only 39% saw content performance improve. MarketingProfs’ Ann Handley summed it up in the report:
AI is like giving every marketer a turbo-charged typewriter.
Typing faster doesn’t produce a second idea, so multiplying one good idea across channels does more for a small team than a faster route to a second, weaker one.
Why write the derivative list before the outline?
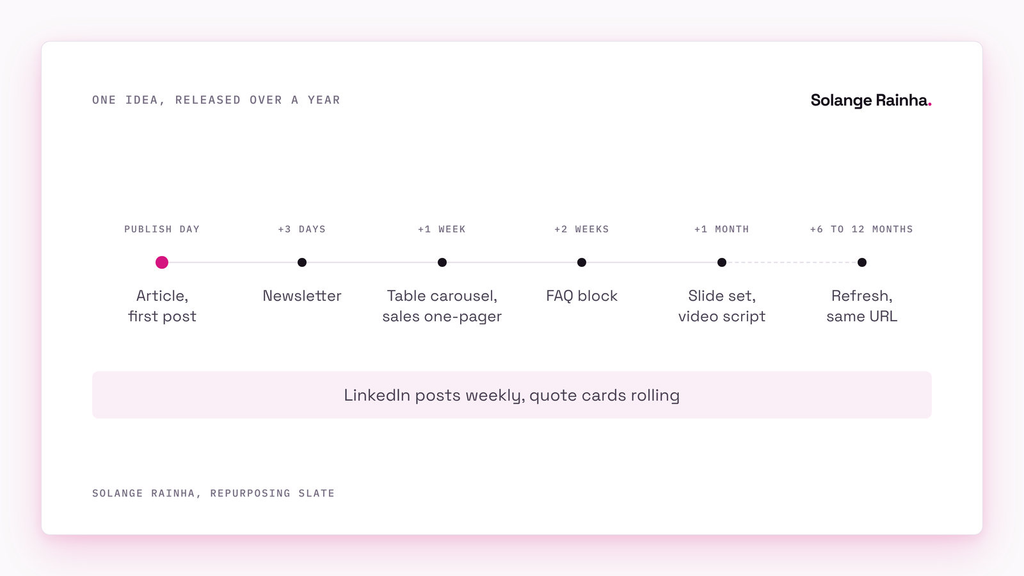
Writing the derivative list first changes the source piece, which is the whole point. The brief has a section listing every asset that will come out of the piece, filled in before I write a word of it. Knowing I owe a slide set changes which comparison I build, and if there’s a sales one-pager on the list, I answer the main objection head on instead of in passing. Here’s the slate off a research-led article, the highest-yield source format I run:
| Asset | Channel | What it reuses | Goes out |
|---|---|---|---|
| The source article | Blog | Everything | Publish day |
| 4 to 6 LinkedIn posts | Personal social | One claim each, stated on its own | Publish, then weekly |
| 1 newsletter issue | The argument, rewritten shorter | +3 days | |
| 1 comparison table, standalone | Social carousel | The table without the prose | +1 week |
| 1 sales one-pager | Enablement | The objection section | +1 week |
| 1 FAQ block | Product or help pages | The three Q&A pairs | +2 weeks |
| 2 to 3 quote cards | Social | Named sources already cited | Rolling |
| 1 slide set | Webinar, speaking | The structure, expanded | +1 month |
| 1 short video script | Video | The single sharpest claim | +1 month |
| Refresh with new data | Blog, same URL | The whole piece, updated | +6 to 12 months |
Twelve is the most a substantial idea supports, and some pieces only yield five. The comparison table earns its own row because a table is the format both readers and models lift most cleanly, which I’ve argued in the B2B comparison page.
What’s the difference between an extract and an entry point?
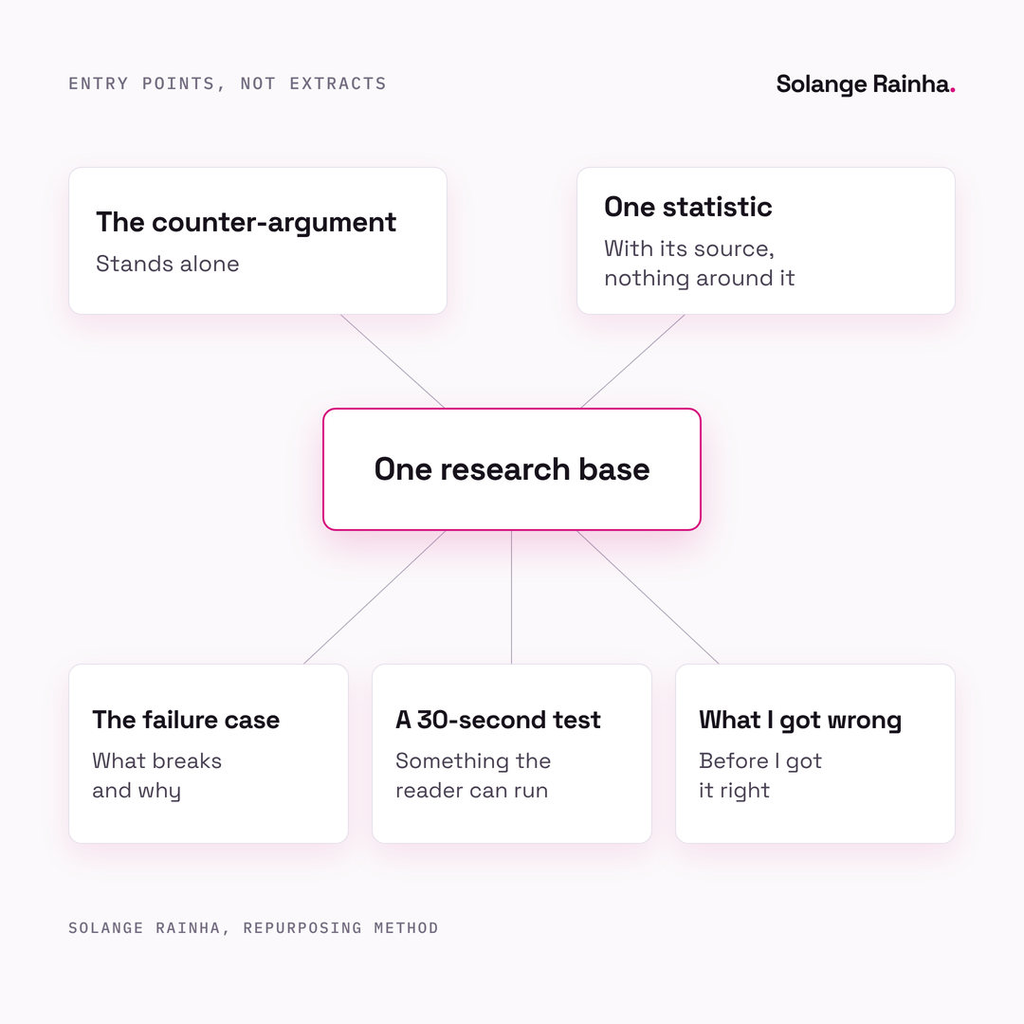
An extract is a paragraph lifted out of the source; an entry point is a different way into the same argument, and only entry points are worth a slot in their own channel. Off one article I’ll usually find the counter-argument standing alone, one statistic with its source and nothing around it, the failure case, a diagnostic test a reader can run in thirty seconds, and what I got wrong before I got it right. Each of those needs its own opening sentence, written for the channel it’s going to.
The test for whether a derivative works is whether it makes sense to someone who never sees the source piece. A LinkedIn post that only lands if you’ve read the article is a trailer, and people scroll past trailers.
Should derivatives become blog posts of their own?
No: keep one canonical page and let every derivative point at it, because several blog pages off one argument compete with each other for the same query. Here I disagree with a lot of published repurposing advice. Cognism’s guide, for example, says repurposing gives “a big SEO boost” because more sharing creates more chances for backlinks, and suggests turning content into videos targeting your key search terms. Sharing the canonical page more is fine; publishing blog-to-blog derivatives of the same argument is how you end up splitting authority across two thin pages instead of stacking it on a good one.
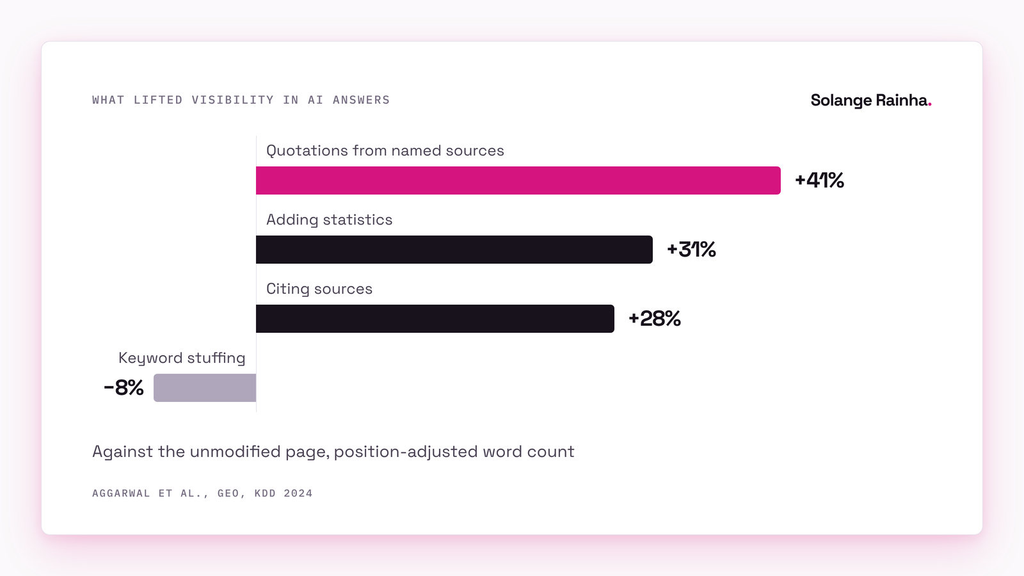
The AEO and LLMO case points the same way. AEO (Answer Engine Optimisation) is the work of being the answer a search engine serves directly; LLMO (Large Language Model Optimisation) is the work of being a source an AI model cites. The Princeton GEO study (Aggarwal et al., KDD 2024, 10,000 queries) found the methods that lift visibility in generative answers are about substance: quotations from named sources added about 41% on its main measure, adding statistics about 31%, and citing sources about 28%, with Search Engine Land’s write-up reporting a 115.1% lift for sites ranked fifth. Keyword stuffing came in below the unmodified baseline. Twelve derivatives carry the same substance as the source page, so they add no citability it doesn’t already have.
Most answers arrive without a click anyway. SparkToro found 68.01% of Google searches in the first four months of 2026 ended without one, and G2 found 51% of B2B software buyers now start research with an AI chatbot more often than with Google. The derivatives do a different job from the canonical page: they get the argument in front of people who’ll never search for it, which builds the familiarity that makes someone type your name later. How the citable page gets built is in the AEO/LLMO content optimisation framework and, at sentence level, in the tactical guide to AI-citable content.
How do you sequence the releases, and what gets cut?
Sequence every derivative with a date in the brief, and cut any derivative that needs research the source piece didn’t do. A piece published once and shared once on the day reaches whoever happened to be online that morning. Everything in the table has a lag against it, and without a written date, the lag is the first casualty when a deadline moves. The full checklist for getting a piece seen without budget is in content distribution for B2B SaaS with no budget.
The kill rule is simpler: any derivative that needs new research gets cut, or it gets promoted to a source piece of its own with its own slate. A “customer quotes” carousel that requires four new customer emails is a separate project, and it’s how a twelve-asset plan turns into a six-week one.
What did twelve assets look like on two product launches?
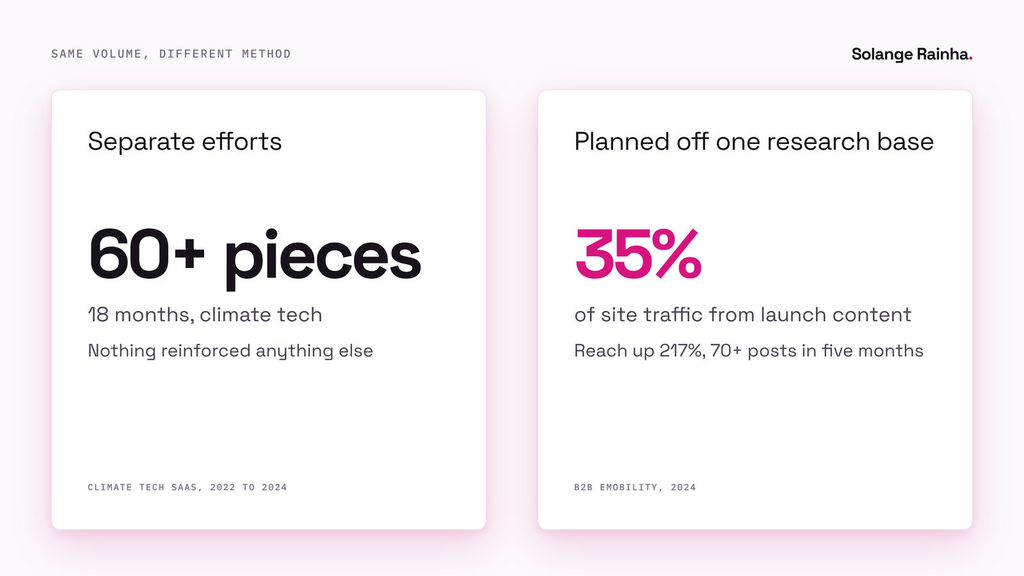
The clearest version I’ve run was two product launches at that eMobility company, where launch content drove 35% of total website traffic during the campaign windows. The research happened once and everything downstream came off it: segment-specific web pages, a whitepaper, social sequences across three platforms, and the sales material. Across five months the social work alone ran to 70+ posts, with impressions up 24% and reach up 217%. The mechanics are in the product launch piece and the 217% reach turnaround.
Before I worked this way, at a climate tech company, I produced 60+ pieces over 18 months as mostly separate efforts. Similar volume, far worse hours, and none of it reinforced anything else, because nothing had been planned to.
Where does this method break?
It breaks on video and on refreshes. Video has been the weak link for two years: I plan the script, I write the script, and it sits there, because the production step needs a skill I’m still slow at, so the slate ships eleven assets. I’m testing whether cutting straight from the slide set gets me past it.
The refresh line at the bottom of the table is the other one. In my experience, updating an existing URL returns more than a new post on the same topic, and it’s still the least satisfying work in the slate, so it slips first when the calendar tightens. Tracking it as a review date instead of a good intention helps without fixing it. What’s worth refreshing at all is a call I make with the content prioritisation framework.
What the multiplication frees up is the research budget: when one idea has to carry twelve outputs, three days of interviews and data looks like the cheapest decision available instead of an extravagance, which is the argument I’d make for original research to anyone still funding content by the piece.
Frequently asked questions
A content repurposing strategy is a documented plan for turning one substantial source asset into several derivatives built for different channels, decided before the source asset is written. It names each derivative, the channel it serves, which part of the source research it draws on, and when it goes out. The version I run yields up to twelve assets from one research-led article and treats the research as the reusable material, never the finished sentences.
Resharing puts the same asset in front of an audience again with a new caption. Content repurposing rebuilds the argument for a different channel with that channel’s constraints in mind, so a LinkedIn post derived from an article has its own opening line and makes one claim instead of summarising nine. The test is whether the derivative makes sense to someone who never sees the source piece.
Not when the derivatives make the same argument. Several blog pages off one idea split authority across thin pages and compete for the same queries, while one deep, well-sourced page earns more in both search and AI citation. Keep one canonical page, put the derivatives in channels that don’t compete with it (social, email, sales enablement, slides), and link everything back to it.
As many distinct entry points as the argument has. For a research-led B2B piece with original data and named sources, that usually works out at ten to twelve, while a thinner opinion piece yields four or five. Forcing a fixed count produces derivatives with nothing in them, and a content repurposing strategy that manufactures assets to hit a target has recreated the volume problem it was meant to solve.