From 15 September 2026, Cloudflare’s new defaults block AI crawlers used for model training and agent access on pages that carry advertising, while search crawling stays allowed. They apply to new domains and, per Cloudflare’s press release, to new sites from existing customers and free-tier accounts that hadn’t changed their settings. If your B2B site runs no ads, the new default does nothing to you, and your exposure sits elsewhere: blocking Training, including through the legacy “Block AI Bots” toggle, now blocks Googlebot too on ad-carrying pages, and the third-party pages citing your category may be the ones going quiet. You can change all three settings in your dashboard at any time.
What did Cloudflare change on 15 September?
The default for AI traffic now splits into three categories, and two of them are switched off on monetised pages. Cloudflare announced the change on 1 July 2026, and in its own words, “the categories of Training and Agent will be blocked by default on the pages that display ads”, while Search stays allowed (Cloudflare). Its changelog still lists 15 September 2026 as the date the new defaults take effect.
Who it reaches depends on which Cloudflare page you read. The press release names new customers, new sites added by existing customers, and “all existing free customers that have not changed their settings by September 15, 2026”. The changelog and the docs mention only new domains. Paying customers with existing zones keep what they had either way, and since the two descriptions don’t match, the only safe answer for your site is the one in your own dashboard.
The settings take about a minute to change in zone Security settings, and you can do it whenever you like. Cloudflare promised to keep notifying customers in the run-up, which was a reasonable promise and not one I’d have built a plan around, because those emails go to whoever registered the domain four years ago.
Why did Cloudflare split AI crawlers into search, agent and training?
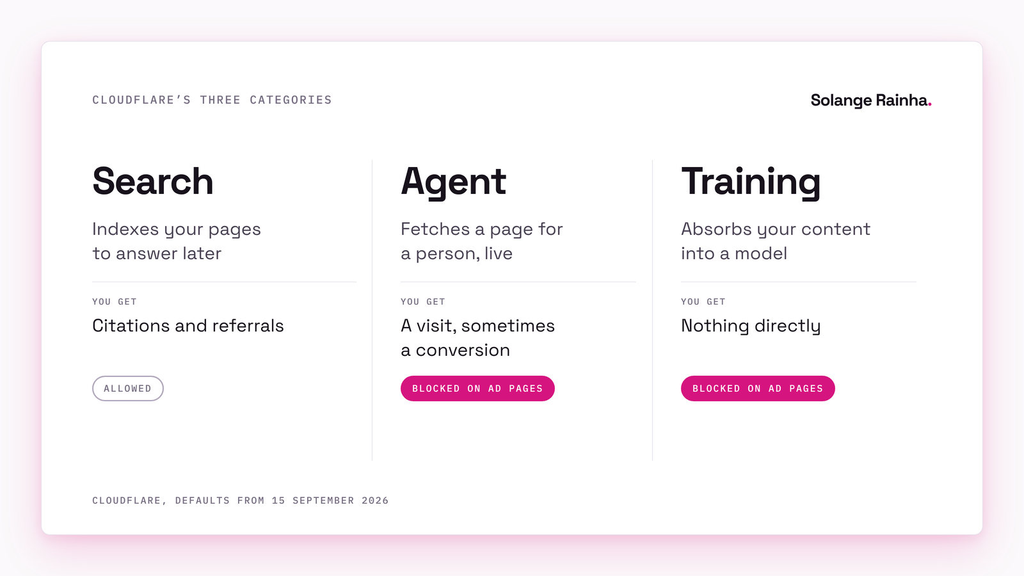
Because the three ask for very different deals, and the old single “Block AI Bots” toggle priced them identically. The new taxonomy sorts automated traffic by what a bot does with what it takes.
| Category | What it does | What you get back |
|---|---|---|
| Search | Indexes your pages so an engine can answer questions about them later. | Referral traffic, or the AI-era version of it: citations. |
| Agent | Fetches a page in real time on a person’s behalf, with a human waiting. | A visit, sometimes a conversion, no lasting index entry. |
| Training | Absorbs your content into a model’s weights. | Nothing directly, ever. |
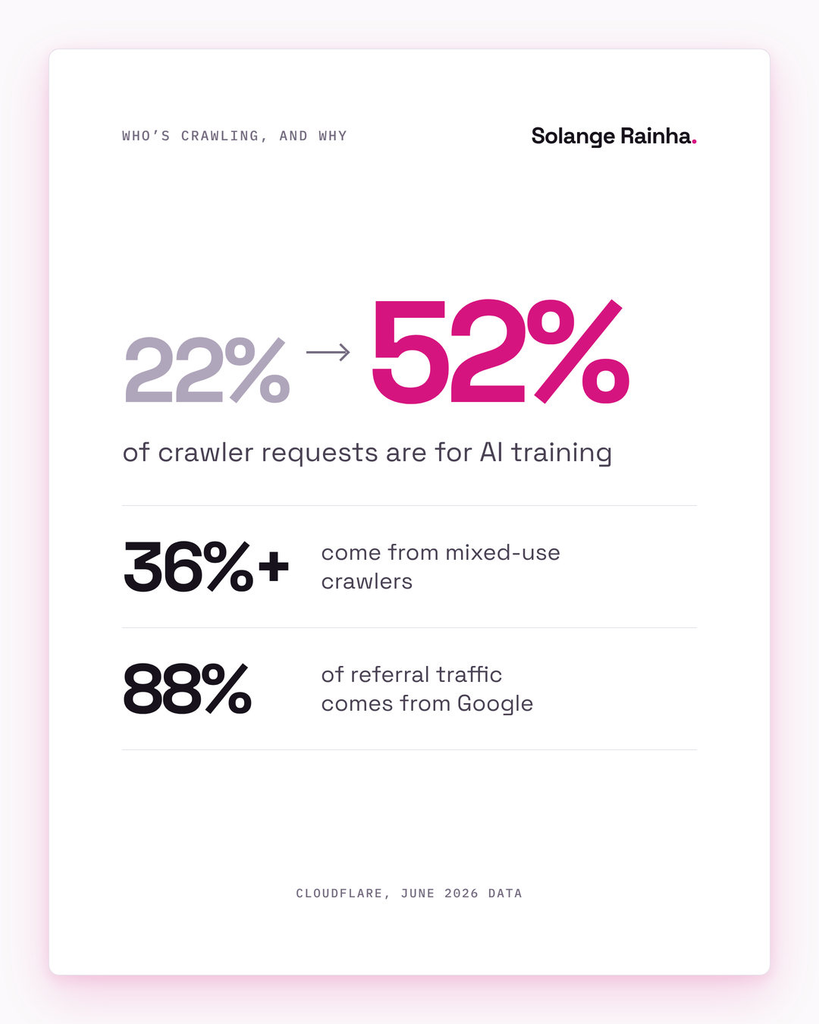
Publishers forced the split, and the data made it impossible to ignore: 52% of crawler requests were for AI training as of June 2026, up from 22% in spring 2025, and mixed-use crawlers that blend search, agent use and training made up more than 36% of activity (Cloudflare).
Cloudflare is also testing a fourth field for Content Signals, the robots.txt preferences it publishes, that says how a crawler may reuse what it takes: use=immediate to interact but store nothing, use=reference to index, excerpt and link back, or use=full to summarise and reproduce. If you’ve switched on Cloudflare’s managed robots.txt, it now adds use=reference for you. These are stated preferences, so they ask crawlers to behave; they don’t block anyone.
Does the new default affect a B2B marketing site?
Usually not, because the default only fires on pages that display advertising. Most of the coverage framed this as the web putting up a turnstile, and for publishers that’s fair, but for a B2B SaaS marketing site it’s close to a non-event: your product pages, blog and case studies almost certainly display no ads.
| Ad-supported publisher | B2B marketing site | |
|---|---|---|
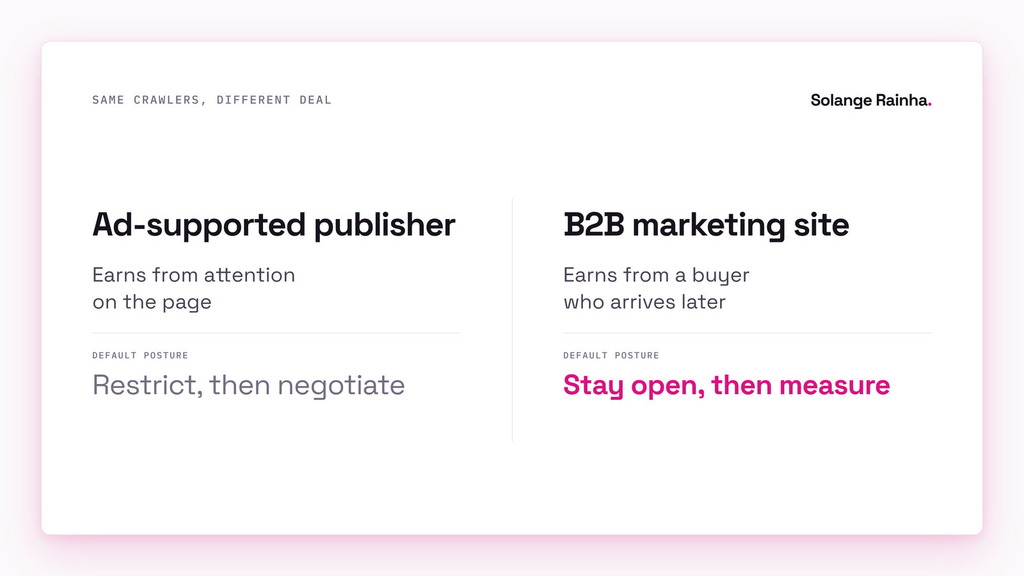
| How the page earns | Human attention on the page. | A named buyer entering a pipeline weeks later. |
| What a training crawl costs | Direct revenue substitution. | Bandwidth, and some pride. |
| What a citation is worth | A fraction of a lost click. | A qualified visitor who arrived pre-sold. |
| Correct default posture | Restrict, then negotiate. | Stay open, then measure. |
Nobody reading your blog generates revenue by being there, which is exactly why choosing to block AI crawlers that put you inside an answer is a self-inflicted wound. I’ve argued the same point from the other direction in Your next buyer might be a bot: if agents do early-stage evaluation on a buyer’s behalf, an agent block is a lead block.
Should a B2B marketing site block AI crawlers?
For training crawlers, a soft yes if you have proprietary research behind a form, and a firm no for everything else. For search and agent crawlers, blocking makes almost no sense unless you’re going dark on purpose, because when you sell software, the loss arrives when nobody reads the page at all.
The one place I’d take training blocking seriously is original research: a survey you ran, a benchmark you published or a dataset nobody else has. It’s the only material on your site with scarcity value, and it’s worth treating differently from the rest of the library, a case I made in Original research is the one content asset AI can’t copy.
Can blocking AI training crawlers block Googlebot?
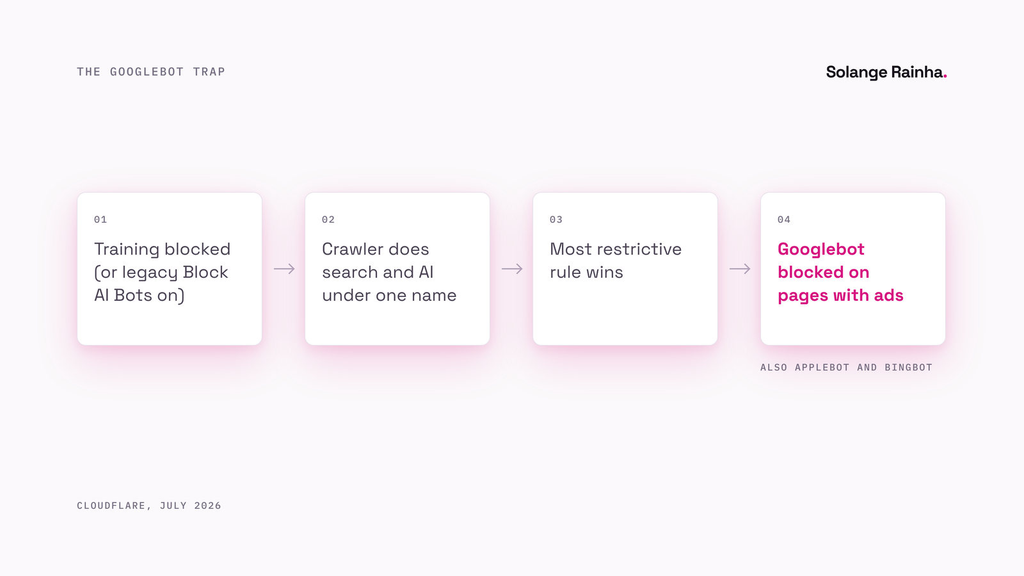
Yes, on pages with ads. Cloudflare judges multi-purpose crawlers against all their declared behaviours, and the most restrictive rule wins. Googlebot, Applebot and Bingbot each crawl for search and for AI features under one user agent, so Cloudflare says they will be blocked for customers who block Training, whether through the new options or the legacy “Block AI Bots” service (Cloudflare). Search Engine Journal reported a site owner seeing Googlebot and Bingbot get 403 errors on a sitemap with AI Training blocked, back in August.
Somebody at your company probably flipped that toggle in July 2025 during the first wave of coverage, told nobody, and left. If your site carries advertising anywhere, including a sponsored placement on a resources page, that decision now has a search consequence attached.
Google is why this is happening at all: it accounts for approximately 88% of referral traffic and runs a mixed-use crawler, which Cloudflare says gives it about twice the information access of AI companies that separated their bots (Cloudflare). Matthew Prince, Cloudflare’s chief executive, put the aim plainly:
“We hope that our proposed default changes encourage mixed use crawlers to separate out search from agent use and training.”
That message is aimed at one company, and every site with a legacy toggle gets caught up in it.
Is Pay-Per-Use worth it for a B2B site?
No, but the reporting attached to it might be. The other half of the announcement reshapes Pay-Per-Crawl into Pay-Per-Use, paying content owners when their work shows up in an AI answer instead of when a bot fetches the page. Cloudflare’s reasoning holds up: “crawling is a crude measure of value”, since a page can be crawled once and cited a thousand times, or crawled endlessly and never used (Cloudflare).
For a publisher with a million-page archive, this is the start of a revenue stream, while a B2B marketing site with 200 pages would get an annual cheque that wouldn’t cover a Semrush seat, and chasing it means restricting the access that gets you cited in the first place, so skip it.
The useful part is the reporting: sites in the Ceramic.ai pilot see the top queries that led to their content appearing, the page and snippet used, and an average result position. That’s the first native answer-engine equivalent of Search Console I’ve seen offered. Until it’s generally available, the manual method works, and I wrote mine up in How I track whether AI is citing my content.
What should you check now?
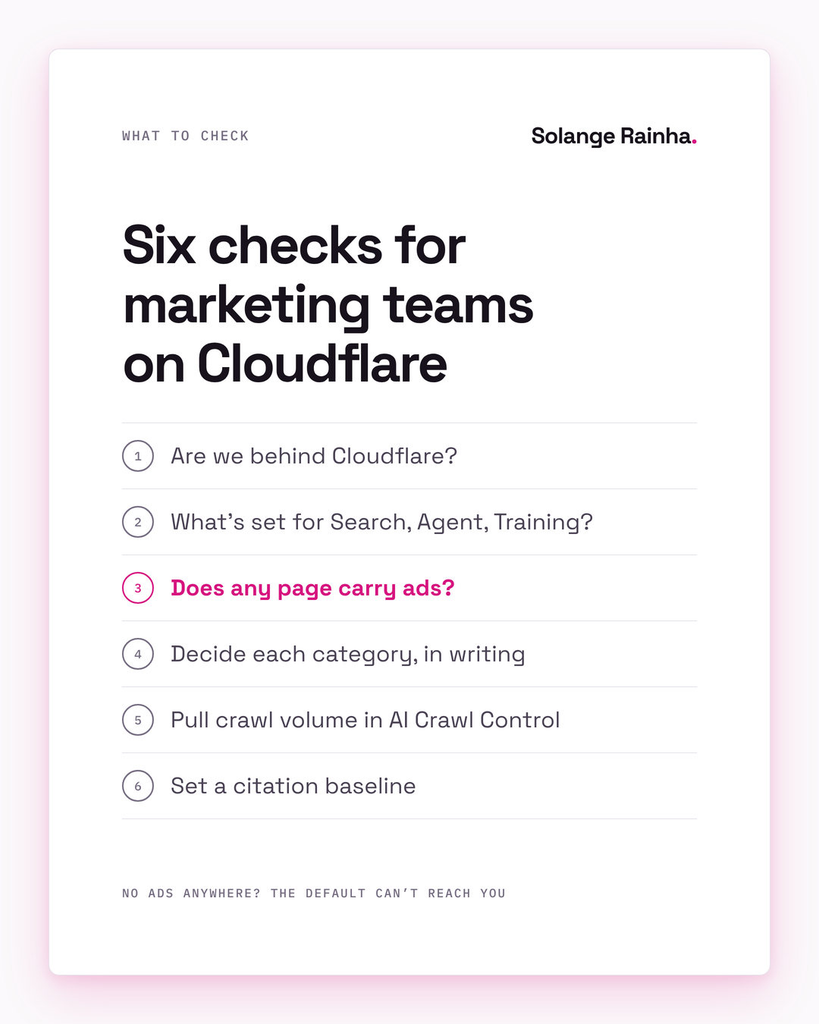
Six checks, in the order I’d do them, whether or not you mean to block AI crawlers. Start by finding out whether you’re behind Cloudflare at all. A surprising number of marketing teams don’t know, because IT set it up, so check your DNS or ask.
Then open zone Security settings and read what’s set for Search, Agent and Training, noting whether the legacy AI-bots toggle is on and who turned it on. Third, confirm whether any page on your domain serves ads: sponsored logos, a partner banner, a monetised resource hub. If the answer is no, the new default can’t reach you and you can stop worrying about it.
Decide Search, Agent and Training separately, in writing, then put the decision somewhere a future colleague will find it. Next, pull your crawl volume: AI Crawl Control, available on every Cloudflare plan, shows which AI services reach your content, and Enterprise Bot Management customers also get a Business Insights dashboard with crawl-to-referral ratios by operator. That figure is usually bigger than the human one, since more than half of online traffic is now non-human and Cloudflare says over half of good-bot crawl traffic re-fetches pages that haven’t changed (Cloudflare).
Last, set a citation baseline, so that if your AI visibility moves you have an earlier figure to compare against, plus a page-level read of what’s extractable, which is the job of an AI readiness audit, and it’s the check that gets skipped and later regretted. When I built AEO/LLMO from zero at a B2B SaaS company serving 200+ higher education institutions, what made the work stand up in a leadership meeting was having tracked visibility from the start instead of reconstructing it afterwards, the argument I make in which content marketing metrics tell you anything. At OpinionX I set one up across 20 buyer prompts and five AI engines, and it’s the measurement layer analytics can’t give you.
When does this not apply to you?
When you’re not behind Cloudflare, or you’re a paying customer with an existing zone and no ads. Nothing here forces you to block AI crawlers or stops you from doing it.
The second-order effect is where it does reach you, and almost nobody is writing about it. The pages that supply AI answers in your category include forums, trade press and ad-supported publishers, which are exactly the properties the new defaults are built for, so as they restrict access, the pool of citable sources in your category thins out. That’s an argument for publishing more original material, the same logic underneath the AEO/LLMO framework I use, and the reason I keep arguing that structure without substance gets you nowhere.
What are the limits of this advice?
I’m a content marketer, not an infrastructure engineer: I can read a bot policy and tell you what it does to a content strategy, and I’d want a sysadmin’s eyes on any setting before it goes live.
Classification details can still move, Cloudflare’s own pages describe the scope of the free-plan change differently, and Pay-Per-Use is explicitly an experiment with two partners, Ceramic.ai and You.com. Treat the mechanics above as a guide and check your settings page before acting on any of it.
I don’t know whether staying fully open will look smart in two years, and the economics of being crawled are being rewritten in public by a company that makes money from both sides of it. I’m confident about the near-term call: a B2B marketing site that chooses to block AI crawlers feeding AI answers pays a cost today against a benefit that’s still hypothetical.
Frequently asked questions
Only if your site is behind Cloudflare, carries advertising on at least some pages, and falls into an affected group. Cloudflare’s press release names new customers, new sites from existing customers and free-tier accounts that hadn’t changed their settings; its docs mention new domains. Training and agent crawlers are blocked on ad-carrying pages, while search crawling stays allowed. Sites with no advertising are unaffected, and every customer can change the settings in zone Security settings.
It can. Googlebot crawls for both search indexing and AI features through one user agent, and Cloudflare applies the most restrictive matching rule to multi-purpose crawlers, so a site with Training blocked, including through the older “Block AI Bots” toggle, will have Googlebot blocked on ad-carrying pages. Applebot and Bingbot are treated the same way. If you rely on organic search, check that setting now.
For most B2B SaaS marketing sites, no. The content exists to be found by buyers, and AI answers are a discovery channel more than a threat to a paywall you don’t have. The exception worth weighing is proprietary material such as original survey data or a benchmark you produced, where scarcity has value. Everything else earns more by being citable than by being protected.
Search crawlers index your pages so an engine can answer questions and cite you later. Agent traffic fetches a page in real time on a person’s behalf. Training crawlers take your content to train or fine-tune a model and send nothing back directly. Cloudflare’s new defaults allow Search and block Agent and Training on pages with ads, and you can set each category separately.